FOCUS – A New Series Focused on Breaking Down Brick Walls

When I teach about genetic genealogy, people often ask, “What’s next? How can I break down my brick wall?” Sometimes I can reply that a Y-DNA test or mitochondrial DNA will help them under specific circumstances. But more often than not, what they really need is a precise, step-by-step methodology that includes autosomal DNA and utilizes multiple tools and techniques across vendors.

Even after people have taken Y-DNA and/or mitochondrial DNA tests PLUS autosomal tests at the major vendors, we still need a methodology to work with combinations of those results. Often, the answers we need aren’t just sitting there like a pretty rock, waiting to be picked up and admired, but depend on us using the results and matches as tools to help focus our search in the right direction.

It’s more like a scavenger hunt than a single discovery.

Focus

Sometimes I feel like a fish out of water – flip-flopping from ancestor to ancestor, match to match and hint to hint, hoping that the magic bullet will fall into my lap, but that almost never happens.

By this point in my research, I’ve perused all the easy records and many of the not-so-easy ones. If you don’t have a surname, or you don’t have a first name, or worse yet, you don’t have either, how is one supposed to search for records?

The good news is that you still carry at least one record in your own body and/or the bodies of your relatives. The DNA of your ancestors.

This is where we’re going to focus our efforts – hence FOCUS, the name of this new series.

Everyone is going to select their closest, or one of their closest, brick-walled ancestors, and we’re going to use several methods and tools to focus on identifying that ancestor.

Prepare

Before I publish the next article in the series, there are a few things that I’d like you to think about and do in preparation.

  • First, there’s no guarantee that you’ll break through your brick wall during this series. You might, and you also might not. You stand a much better chance of breaking through that brick wall if you focus and follow these steps than if you don’t.

Keep in mind that even negative evidence is evidence, and just because you don’t break through right away doesn’t mean you won’t. New people test everyday and new records become available too. If nothing else, your ancestor will have more meat on their bones, and you’ll have a process to build upon.

  • Second, if your brick wall is very close in time, meaning parents or grandparents, you’ll want the already-written “In Search Of Unknown Family” series, which you can find, here.
  • Third, you’ll need to keep a research journal or log by ancestor, family or location, which will also include your other related ancestors. For example, if you’re looking for Lucy whose surname you don’t know, but you know that she married William Moore, then your research journal will apply to William Moore too, and other people including their children and either spouse’s parents and siblings, whether that was your intention or not. The neighbors are probably relevant as well.

That “it takes a village” saying is particularly relevant here. People didn’t tend to move to the next location alone, and often their community consisted of their cousins and relatives – who are also your relatives, and hold clues to the identity of your ancestor. When I’m extracting records for the Moore surname in Halifax County, VA, for example, I extract everything for that and similarly spelled surnames, not just one particular person, so I don’t have to replow that field.

Tracking and Recording Your Research

If you don’t already have a research journal methodology, I would suggest a spreadsheet.
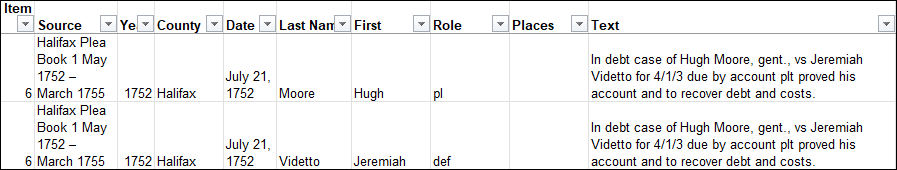
Here’s a screenshot of two rows in my “Halifax County” spreadsheet where I’ve recorded separate rows for each person in every record. Note that I started this spreadsheet years ago and omitted some columns that I later wished I had included, like the access date.

You’ll want to record:

  • Item number beginning with 1. In the example above, the item number is 6, and it’s 6 for every person in that record. Each person in this transaction gets their own separate row, with the same item number. The next record I extracted would be item 7.
  • Access date (date you found and retrieved the record)
  • Last name
  • First name
  • State (add a column for country if multiple countries are relevant for this family)
  • County
  • Town, township or city
  • Geographic places like road or creek names (these can be VERY important)
  • Year, month and day that the record occurred
  • Record repository or source (including a link if applicable – you may want to add a separate column for the link)
  • Record type (deed, will, tax list, etc.)
  • Role of individual (buyer, seller, witness, etc.)
  • Names of additional people in the record (I retain the same item number and other information, changing the name of the person, their role and sometimes an associated comment)
  • Transcribed text of the record itself
  • Comment, which can include things like the name of an image, something about what you were searching for when you found the record, links, or anything else relevant

You will want to be able to sort and filter this spreadsheet when you are finished. Hint – be sure your date fields and formats are sortable in the way you wish. I normally use filters instead of the sort feature.

The goal isn’t just to record your findings, but to make this spreadsheet as useful as possible to make discoveries that are only available by comparing and incorporating multiple records.

For example, let’s say that you’re extracting all of the Moore records in a Halifax County, VA deed book, and you want to know how many times the surname Henderson is found in the Moore deeds or in conjunction with the Moore family. Is there a pattern? You won’t recognize a pattern from any ONE record, but you may eventually wonder if the Henderson’s are related to the Moore family, and if so, how.

You’ll also want to record nonproductive or negative evidence. For example, let’s say you searched the Halifax County Plea Book for William Moore (including More and Mohr) and found no occurrences. That’s important, because otherwise you‘ll eventually search again, so enter that as a record item.

Note that with the full text search feature introduced by FamilySearch a couple of years ago, if you extracted records from a book that did NOT include every-name indexing including property lines, creek names and witnesses – you’ll want to redo that search using the full text feature at FamilySearch. There’s often LOTS of valuable information buried in records that won’t be found if you’re only viewing records indexed by buyer and seller, for example.

Your To-Do List Before the Series Begins

The In Search Of Unknown Family Series introduces important concepts, so reading that series is your first assignment in preparation for the upcoming FOCUS articles.

Test Your DNA With the Major Vendors

It’s important to test with the major vendors. Each vendor has matches and tools that the others don’t, and we need to identify and work with as many relevant matches as possible.

If you have NOT taken an autosomal DNA test at the first three following vendors, order these tests now so you have results to work with.

  1. AncestryDNA
  2. FamilyTreeDNA – Purchase a Family Finder test or upgrade an earlier Family Finder test to the new Family Finder NGS test. You should upgrade if you uploaded your autosomal DNA file from another vendor at any time, or tested at FamilyTreeDNA directly before March of 2026. The upgrade is only $29.
  3. MyHeritage DNA
  4. A fourth vendor, 23andMe, is optional, but testing there certainly won’t hurt.

23andMe Sidebar

I have an issue with 23andMe’s policy of forcing customers to repurchase a DNA test at $199 PLUS a subscription at $149 for the first year, renewable at $69 per year, in order to obtain any of their latest tools. This happened around the time of their data breach and subsequent bankruptcy.

I would feel much better about the situation as a whole if a new owner had taken the wheel, but the original owner resigned from the 23andMe board, formed another corporation, and was allowed to buy 23andMe out of the bankruptcy that occurred on her watch.

Furthermore, 23andMe does not support genealogy trees, nor do they have Y-DNA or mitochondrial DNA testing and matching, or research records.

I have (begrudgingly) ordered an upgrade for my own 23andMe test in order to include accurate information in these articles, but I won’t be focusing on 23andMe specifically aside from any unique feature. You can apply the same concepts and techniques to results at 23andMe where possible.

Test Your Relatives

If you have close upstream relatives, such as parents, grandparents, aunts, uncles, and cousins who also descend from your brick-walled ancestor, please ask them to test too.

I explain what I’m trying to achieve, why their test is important, and offer scholarships to sweeten the pie. I view purchasing their DNA tests in the same way I view purchasing a rare research book that I KNOW includes my ancestors but it not available anyplace else.

Your shared matches are extremely important and may provide that brick-wall-breaker. Perhaps even more importantly, they will have relevant matches that you don’t.

So how do you know who to test? You certainly want to test everyone relevant, without wasting money.
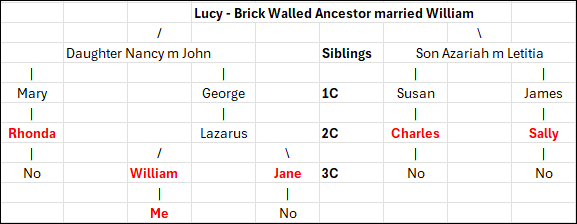
Let’s look at this example where Lucy is the brick-walled ancestor I’m seeking to identify. Her children (labeled siblings) and grandchildren (1C) are all deceased, but second cousins (2C), Rhonda, Charles and Sally are all available to test. Test each of them because they will all have some different segments of DNA from Lucy that the others don’t have.

Lazarus is also a second cousin, but he’s deceased. However, William, my father (in this example, not my real pedigree), and his sister, Jane are both available to test.

You ALWAYS want to test both of your parents and every available grandparent or direct ancestor. In this example, I’ll only inherit some portion of Lucy’s DNA that my father has, but Jane, my aunt, will carry segments of Lucy’s DNA that my father didn’t inherit from Lazarus. Jane’s matches on those segments that neither my father nor I have may be just what we need to identify Lucy.

If Lazarus has other children not shown in this example, we certainly want to test them too.

If the relevant parent has tested, you don’t need to test any of their children. However, if the parent hasn’t tested, absolutely test as many of their children or descendants as possible.

In this case, Rhonda, Jane, Charles and Sally have all tested, so I don’t need to test their children. Their children can only have as much of Lucy’s DNA as their parents had.

However, if any of them had been deceased, then I should test as many of their children as I can to “gather up” as much of Lucy’s DNA as possible.

If any of the people upstream of the bold red people have other children, those children or their descendants would be testing candidates too. Ideally, you want as many descendant testers as possible to increase your chances of identifying that ancestor.

Selecting Your Brick-Wall Ancestor

I want you to be successful, so you’re going to select your closest brick-walled ancestor within certain parameters. If you have multiple brick-walled ancestors at the at the same genealogical distance, you’ll choose one to focus on.

Why your closest brick-walled ancestor? If your brick wall is 5 generations back from you, and they are 5 generations back from your DNA match as well, that means you’re dealing with a 4th cousin match.
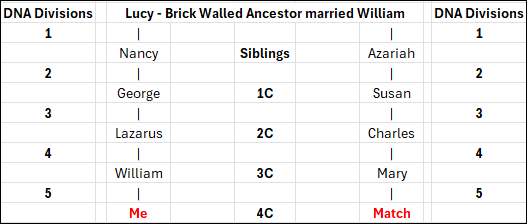
This also means that ancestor’s DNA has been divided a total of 10 times – five times on the path of descent to you, and five times on the path of descent to your match.

A 4th cousin match is likely to be in the 35 cM range. You can view the matching ranges for various relationships at DNAPainter, here.

The entire 4th cousin (4C) matching range is 0-139 cM. You won’t match all of your 4th cousins and are likely to match only 50-70% of your 4th cousins.

That said, the average person has between 1,500 and 4,000 4th cousins. At the 4th cousin level, you have 32 ancestors, so only between 46 and125 4th cousins will descend from any given ancestor, and of those, only a few will have taken a DNA test. The more children that ancestor had that lived to marry and have children of their own, the better your chances of more matches.

The Selection Process

I’m going to be stepping through the ancestor selection process with you, discussing who is and isn’t a good candidate, and why. I’m also going to be using this same methodology to (hopefully) identify one of my own mystery ancestors too.

I have no brick walls closer than 4th cousins. If I did, I’d choose the closest brick wall. You should too in order to have the best chance of solving this puzzle. The further back in time, the more difficult the solve will be.

In my tree, I have four mystery ancestors at the 5X great-grandparent level on my father’s side, and one on my mother’s side.

Those will be the four ancestors I consider selecting. And no, before you do it, I don’t recommend working on all four of them at the same time. Remember, the purpose is to FOCUS.

  • Select an ancestor as close generationally as possible, because it’s more likely that both you and other people will carry at least some of their DNA, and the same segment(s) of DNA. Matches closer in time generally carry more total DNA in common, which means better matching and more shared matches.
  • Given that the majority of testers are from the US, and assuming you are from the US too, I don’t recommend selecting an ancestor from another country unless you are very comfortable with that language and working with those records. Generally, there will be fewer people who have tested from other countries. If you are going to work with an ancestor from another country, be sure you are in both the MyHeritage and FamilyTreeDNA databases.

My mother’s entire paternal line is either Dutch or German Brethren, and her Dutch ancestors only immigrated in the mid 1800s, so have few descendants in the databases.

My closest brick wall on her paternal line is Traut Enterlein, a German man who was named in an out-of-wedlock baptism for his daughter in Germany in 1823. He is not found in any other records in that part of Germany, so actually identifying “who he is”, even with a name, would be extremely difficult, and I have nothing to “anchor to” here.  He is eliminated as a candidate because he’s found in a country where I don’t speak the language, where fewer people have taken DNA tests, and we’ve already spent a substantial amount of time trying to identify him in the records.

Brick-walled ancestors on Mom’s maternal side are two generations further back in time. Half are German and the other half are a combination of English and Acadian.

  • Avoid both endogamy and pedigree collapse, if possible. I don’t recommend a line with baked-in challenges that will make DNA more difficult.

Acadians are heavily endogamous and often suffer from pedigree collapse since there were so few founding families in the mid-1600s. The same goes for Brethren families who immigrated in the early 1700s. Those lines are too far back generationally anyway, so they have already been eliminated, but if they weren’t, I’d eliminate them because of heavy endogamy and pedigree collapse, both, not to mention record loss.

My father’s side has much better candidates.

  • Try to select an ancestor where you have some familiarity with the location, the culture, and the records. If you have printed resources at the ready, possibly ones that are not online, that’s a plus.
  • When you’re trying to decide between ancestors, select one whose spouse you are sure of, and who has children you can document. Do you know important things about them like their religion, where they lived during specific times, and who their neighbors were? If not, take some time now to brush up on what you do know about their spouse and children.
  • Check back at all of the records vendors and resources, including Ancestry, MyHeritage, WikiTree, and FamilySearch, to see if anything new is easily available for either your brick-wall candidate or their spouse.
  • I do NOT recommend selecting an ancestral couple, neither of whom you can identify, unless you’re “lucky” enough to have no other brick-walled ancestors to choose from. It’s possible to solve this “double-blind” couple, but it’s substantially more difficult because you have no same-generation anchor.

My Candidates

I’m selecting one of my brick walls and hope to solve it during this process. Let’s run through the decision-making process so you’ll understand some of the considerations and why they weigh as factors. I wish I didn’t have so many choices, and I’d like to solve them all, but my best chance is to work on one at a time.

Most candidates are women because their birth surnames tend to easily become lost after they marry, and with their surname, their parents are lost too. Given how little we know, we have to presume (dangerous word), at least for now, that your missing female ancestor was the mother of all of their husband’s children, unless we know or subsequently prove otherwise.

Let’s review my candidates.

  1. Lucy was born about 1754, probably in Virginia, and died in 1832 in Halifax County, VA. She married William Moore between 1772 and 1774, who may or may not have been a circuit-riding minister at that time. She is found under her own name on the 1830 census, there’s an 1826 chancery suit, and I know who her children and neighbors are, so she might be a good candidate. One vote against selecting Lucy is that I don’t know where she was born, nor do I know where they were married, although there’s a very strong possibility that it took place in Halifax County. The fact that he was a circuit-rider means he could have met her anyplace. If they were married in Halifax County, their families could have been allied before arriving there. William Moore’s family came from Prince Edward County about 1770, and we know who his parents were. One good thing is that Lucy is a fairly uncommon name, but there are multiple William Moores in Halifax County, and there are two other Lucy Moores. One is her daughter, and one is her daughter-in-law. The fact that Lucy and William Moore had 12 known children, with at least 8 who married, means there is a good chance of matching at least some descendants. Unfortunately, I don’t have her mitochondrial DNA, which removes one possible tool unless I can find a tester.
  2. Jane, born about 1760 in an unknown location, but probably Virginia, was the wife of Lazarus Dodson. They moved across multiple frontiers into what would become early Tennessee, an area that sustained substantial record loss. Jane died between 1830 and 1840. There’s a lot of uncertainty about Jane’s life. She probably had at least 8 children, and we know something about six of them. Given that we already have a better candidate with Lucy, I’ll eliminate Jane for now.
  3. William Crumley’s wife, whose name I don’t know, was born around 1765 or 1770, possibly in Virginia. She was married to William Crumley around 1786 or 1787, probably in Frederick County, VA, or nearby. I do have her mitochondrial DNA and we know the family was Quaker which are both benefits. I’ve been working with a cousin who has delved deeply into Quaker records, and I have some records from a trip to the FamilySearch Library in Salt Lake City that I have not yet processed. She and William had at least 10 children who married, and I know quite a bit about them. She would probably be an excellent choice. For lack of another name, I’ve been calling her H2a1, her legacy mitochondrial haplogroup before Mitotree, but she has a much more complete haplogroup now. She would be a good candidate, and I REALLY want to identify her.
  4. Mary, wife of John Harrold (by various spellings), was born about 1750, possibly in Ireland, although it would be unusual for a first-generation Irish immigrant to end up deep in the Appalachian frontier. Mary died in 1826 in Wilkes County, NC. We know nothing about John’s background, other than he served in the Revolutionary War, in Virginia. He may have been living in Botetourt County, although we don’t know for sure, and there are multiple men by that name. Mary had at least 7 children, six of whom were married. We do not have her mitochondrial DNA. Given that we know so little about John, and we have better candidates with both Lucy, William Moore’s wife, and William Crumley’s wife, I’m eliminating Mary for now.
  5. Isabel, the wife of Michael McDowell – another couple from Wilkes County, NC. Their daughter married the son of Mary and John Harrold. Isabel was probably born about 1750, someplace in Virginia. We don’t know where they were married, but it could have been in Franklin County, VA. They lived in Wilkes County for several decades before moving on to Claiborne County, TN. We know very little about Michael’s early life, other than his Revolutionary War service, although I’ve written about him four times as additional information dribbles out. They had at least 8 children, and a deposition after Michael’s death tells us where they moved and settled, which is a very big plus. We know her first name thanks to a 1793 deed. Isabel is a reasonable candidate, but I eliminated her after comparison to the other candidates, in part because of multiple frontier moves with few records and no known point of origin.
  6. Elizabeth, wife of Andrew McKee, was born about 1767, possibly someplace in Virginia. They were in Washington Co., VA by 1789, although we don’t know where either originated. They may have married before they moved to Washington County, where we find several records. They had 14 children. Twelve are known to have married, and the other two probably did as well. We know who their neighbors were. We also have Elizabeth’s mitochondrial DNA. Unfortunately, we know nothing about Andrew McKee’s family or where he was from. However, Elizabeth is a strong candidate because so many records exist in Washington County, they had a large number of children, and many continued to live in Washington County or nearby, making them easier to track.
  7. If I didn’t already have good candidates, there’s one more ancestor I’d consider, even though James Lee Claxton/Clarkson is a generation further back in my tree, born about 1775, and his unknown parents are the brick walls. I know I just told you NOT to do this, so I won’t either, but the reason I might have considered his parents, or more specifically his father, as a strong candidate is because we have several Y-DNA matches, including Big-Y testers, and we know the ancestors of his matches came from NC. We also have many autosomal testers and matches, which would help immensely, and there’s a Clarkson/Claxton DNA Surname Project. A contiguous surname is a HUGE benefit not available with female ancestors, and I just feel that I’m SO CLOSE to solving this mystery. For now, James’s parents are eliminated because they are two generations further back in time than our other candidates, we know nothing about either of them, except Y-DNA results, and we have better candidates for this exercise.

After evaluation, I still have two candidates in the running – Lucy, wife of William Moore, and H2a1, William Crumley’s wife. I haven’t decided for sure yet, but right now, William Crumley’s wife is leading because I have an amazing collaborator along with some unprocessed records that may hold important information. I know there probably aren’t any smoking guns there, but when combined with DNA, we may well ignite that gunpowder.

FOCUS

Are you ready to focus?

Let’s get our ducks in a row.

  • Order any DNA tests you need to order for yourself and relatives now.
  • Select your ancestor.
  • Prepare your research journal by reviewing which records you’ve already researched and record what you have.
  • Refamiliarize yourself. Take a look at those results again with fresh eyes. It helps when reviewing match results to be able to view surnames in your matches trees and recall that you’ve seen that name before, and where.
  • Check to see if any new records or resources are now available.

Who do you want to find?

_____________________________________________________________

Share the Love!

You’re always welcome to forward articles or links to friends and share on social media.

Subscribe!

If you haven’t already subscribed, it’s free. You’ll receive an e-mail whenever I publish by clicking the “follow” button at the top of the main blog page, here.

Help Keep This Blog Free

I receive a small commission when you click a vendor link in my articles and purchase that item. This does NOT increase your price but helps me keep the lights on and this informational blog free for everyone. Please click on the affiliate links in the articles or to the vendors below if you are purchasing products or DNA testing.

Thank you so much.

DNA Purchases and Free Uploads

Genealogy Products and Services

My Books

Genealogy Books

Genealogy Research

The New Family Finder NGS Test Results, Comparison, and Preparation

This article is focused on two things.

  1. Comparison of my new NGS and the earlier Family Finder tests
  2. How to prepare for yours if you’ve ordered the upgrade

I compared my results from my older Family Finder test with my new NGS Family Finder test results. As an early beta tester, I have two separate tests, a strategy that is not recommended because it causes duplicate matches for people within the database. Additionally, multiple kits for one person doubles the results and could skew future ethnicity research for myOrigins.

Therefore, FamilyTreeDNA has announced very attractively priced upgrades at $29 for both:

  • People who have taken Family Finder test directly at FamilyTreeDNA
  • People who have uploaded their DNA files into Family Finder from other companies

After seeing my comparison, you may want to compare your own results when they arrive, so I’ve documented that process. Warning: this took between 4 and five days because I was working with a spreadsheet with more than 15,000 rows, and I had to write scripts to perform multiple functions. It was NOT fun and I do not recommend it.

Personally, had I known then what I know now about how reliable the new NGS test is, I wouldn’t have bothered with the comparison. However, I would have downloaded my original match list for posterity, just in case.

If you purchase an upgrade to the new NGS Family Finder, your new test results will replace your older Family Finder test results, but will preserve important account features such as linked matches, any notes you have taken, and more. That’s another reason to upgrade rather than order a separate new test. They’ve done the heavy lifting, not to mention that you’ll save about $50 when compared to the price of a new test.

Why is the New NGS Family Finder Test Better?

The new NGS test holds immense promise for the future. This includes better matching, beginning now. Essentially, FamilyTreeDNA is skating to where the puck is going to be (hockey analogy) and preparing for future tools. That future is not far away!

An amazing new set of tools is goaled for release around the end of the year. And I do mean amazing. They are being beta-tested internally now.

Dave Vance spoke about the new Family Finder NGS test at the ECGGC conference in late August, which you can view through the end of 2026 if you register for the virtual  conference, here, and watch the recorded sessions. You’re looking for the DNA Academy on Saturday evening. I can’t share specific preview slides with you as they are noted in his presentation as “not for distribution,” so my pen is capped for now.

All I can say is that after seeing what’s in store, people were literally throwing their billfold at the folks at the FamilyTreeDNA booth – and I do mean literally. “Here – take my money, please!” as the billfold went sailing. We all had a good laugh, but he was serious.

One presenter (not me, just in case you are wondering) left her credit card and a list of tests to upgrade while she was presenting.

They ran out of swab kits at the conference shortly after Dave’s presentation about what the future holds.

Additionally, you will also be treated to THE absolute best presentation I’ve ever seen about what NGS testing is, how it works, and how it compares to traditional tests, low-pass whole-genome tests, and medical-grade whole-genome tests.

You’ll be a passenger on the Genome Valley train, so climb aboard!

So, without spilling any beans, what’s so great about the NGS test?

To begin with, the older Family Finder tests won’t be able to provide everything the new NGS test will be able to offer – and those completely new tools are in active development today.

Why?

The NGS test targets over 280 million base pairs, up from the currently available 700,000.

That’s more than 400 TIMES the coverage.

This increases coverage in the human genome from about .02% to about 9%.

To quote FamilyTreeDNA, “This change allows us to deliver more precise autosomal results today while creating a strong foundation for future reports and tools.”

You can read the FamilyTreeDNA FAQ here.

Before we move on to the comparison, let’s talk for a minute about test types and uploads from other vendors.

Tests and Uploads

All new Family Finder tests purchased at FamilyTreeDNA since March 2, 2026 have been tested using Next Generation Sequencing (NGS), so the following matrix does not apply to those tests. Those tests don’t need to be upgraded.

If you sign on to your account, on the Family Ancestry dashboard, and see that your NGS button is grey, then you have not upgraded. Click on that grey button to read more and to upgrade. Right now the upgrade is $29, but I don’t know if that is a promotional price or permanent.

If you tested at FamilyTreeDNA prior to March 2, 2026, or uploaded a DNA file from another vendor, your test will fall into one of the following upgrade path categories.

Tested at FamilyTreeDNA before March 2, 2026 Uploaded and purchased the Unlock Uploaded but did not purchase the Unlock
Upgrade Path Can use sample stored in lab if enough DNA remains* If you purchased any other type of test at FamilyTreeDNA, they will use DNA stored in the lab if enough remains. Otherwise, you will be sent swabs. If you purchased any other type of test at FamilyTreeDNA, they will use DNA stored in the lab if enough remains. Otherwise, you will be sent swabs.
New Swabs* If needed, they will notify you Yes, if needed, will notify or send swabs if you have not taken a direct test at FamilyTreeDNA Yes, if needed, will notify or send swabs if you have not taken a direct test at FamilyTreeDNA
NGS Results Will replace existing results Will replace existing results Will replace existing results

*You will be notified if enough DNA does not remain, and you will be sent new swabs. Be sure your address is current.

One of the reasons the NGS test performs better, even with existing matches from earlier tests, is because less imputation is involved. Let’s talk for a minute about imputation and how it works.

The Concept of Imputation

Most vendors change chips internally from time to time, and FamilyTreeDNA is no different. The difference this time is that the new NGS test covers exponentially more DNA than any earlier test, and all earlier tests combined. This means more than 400 times greater coverage, which in turn means less imputation is needed to compensate for the inevitable no-reads and to be compatible with files that tested different DNA locations.

Imputation is also used when comparing DNA files between vendors who don’t test the same locations.

Click to enlarge any image

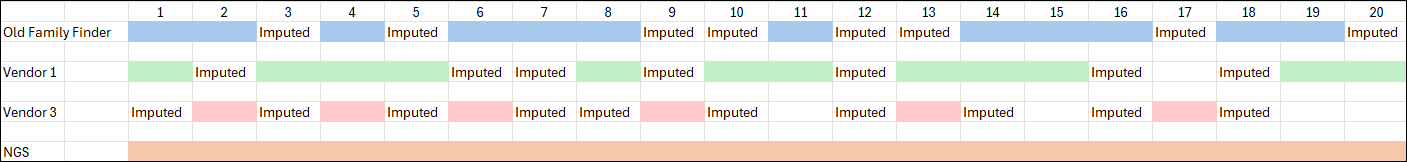
Here’s an illustration of the concept of how imputation works.

All of the FamilyTreeDNA chip versions over the years have included about 700,000 locations, as have most other vendors. But the locations tested are not universally the same.

In our simplified concept example, FamilyTreeDNA’s tested “locations” are shown with blue cells.

The total of 20 squares shows the maximum amount of DNA tested by any of the three vendors shown, combined.

Green Vendor 1 in our illustration tests the same amount of DNA that FamilyTreeDNA tests, 12 squares, but some locations are the same and some are different. Of the 12 colored squares for both vendors, seven are the same locations, and five are not. The locations that are the same can be compared directly, but the locations that are different have to undergo special handling called imputation.

Looking at any location in our DNA, one of four nucleotides, or letters, can be present: T, A, C or G on each strand of our chromosomes, although we are only looking at one strand in our example.

Using a very simplified model of imputation, think of imputation as “filling in the blanks” using clues from surrounding letters – kind of like a crossword puzzle.

When two vendors’ data doesn’t overlap, imputation is used to fill in the blanks, as accurately as possible, for the missing data.

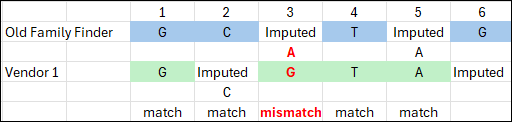
Using a word analogy, for vendors one and two only, we see that blue location three has no Family Finder data, where green Vendor 1 does, and the same with location five. If blue locations two and four are C and T, and three has to make a word, then there are few options. In this case, let’s say it’s cat, and location five is imputed to an A too.

Now moving to green Vendor 1, their locations two and five need to be imputed. Moving away from the word analogy, let’s look to the human genome, and let’s say that most of the time, location two is a C if location one and three are Gs. So green location two is imputed to C.

If there’s not enough quality surrounding data, imputation can’t be performed reliably. Hence, location six is still in limbo here.

You can see that in our scenario, location three is the only mismatch, out of three imputed locations. Does location three mismatch because imputation was wrong? We don’t know. Do locations two and five match because imputation was wrong? We don’t know.

All things considered, imputation is based on the science of probability, and is usually relatively reliable, but it’s still not the same as comparing actual data. The more locations that have to be imputed, and the longer the stretch, the greater the possibility of error. Every vendor implements imputation differently too. Even vendors who don’t and have never accepted uploads still use imputation internally to equalize their own legacy files from earlier test versions.

Stepping back once again to compare the four vendors, you’ll notice that pink Vendor 3 only tested half as much DNA as the blue Family Finder test and green Vendor 1, and again, not all of the same locations. That’s exactly what happened with one of the vendors last December – they dropped the number of DNA locations tested to about 400,000 from about 700,000. In our example, you can see how much would have to be imputed. Locations 11, 15, 19 and 20 can’t be imputed for the pink vendor’s file because there’s no surrounding DNA. Location 17 can’t be imputed for the green vendor for the same reason.

When vendors impute to match multiple versions of other vendors’ uploaded files, it can quickly become messy.

The answer, of course, is a “supertest,” which tests all of the locations that overlap everyone, including that vendor’s own earlier tests.

Welcome to Family Finder NGS, shown in orange at the bottom of our example comparison.

As you can see, the orange NGS test covers all of the locations tested by all of the other tests.

NGS is targeted testing for a specific set of locations that are known to undergo mutations in the human genome and provides extremely high-quality results. Imputation for the NGS file is rarely necessary, although imputation for the other vendors’ and earlier file versions is still required for them to match to each other.

This is exactly why the upgrade is recommended, and why there’s no benefit to retaining your old test. The NGS test tests far more data and provides much more reliable matching.

NGS is the great equalizer.

NGS Test Comparison Process

I took my NGS test during the initial R&D development and testing phase, so my original Family Finder test was not upgraded. This afforded me the opportunity to compare the two results.

I downloaded the match files for both of my tests, the original Family Finder and the new NGS Family Finder test, color-coded the background of the cells, not the text inside the cells, and dropped them into a single combined spreadsheet.

It doesn’t matter what colors you choose, but be sure you can easily see the difference. I used apricot for the original Family Finder test matches and light purple for the new NGS test.

As we walk through these results together, you’ll notice that I continue to refer to them by color. In part, that’s so I can maintain my own sanity as I compare results. When I write these types of articles, I have to check and recheck results.

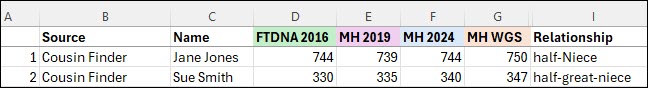
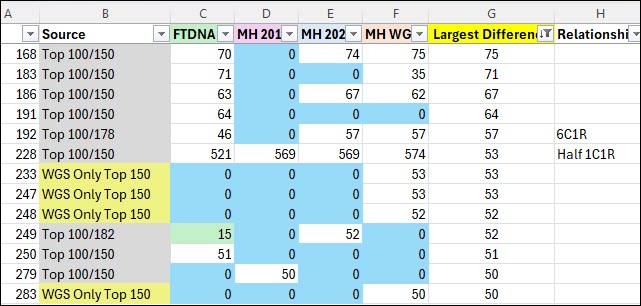
When the same person showed as a match to both tests (meaning they had both an apricot and purple row), I calculated the difference in matching amounts of DNA (cMs) between the match’s results on both tests. I added several calculation columns, which are not shown above.

I’ll tell you, this was not a trivial exercise. It was painful and I really don’t recommend it.

Let’s take a look at the results.

Total Matches

I have some matches with the new NGS test that I do not have with the legacy Family Finder, and I have some matches on the older test that are no longer present on the NGS test.

  Old Family Finder (apricot) NGS Family Finder (purple) Difference
Total Matches 9014 7719 1,295
Maternal 1665 Not linked
Paternal 3783 Not linked
X-Matches 2198 1849 349

I have not yet linked the same matches in my NGS test, so I can’t compare the number of maternal and paternal matches. Fortunately, when you upgrade an existing test, FamilyTreeDNA preserves your linked matches, so you won’t need to relink.

Relationship Estimates

  Old Family Finder (apricot) NGS Family Finder (purple)
1st-2nd cousins, Great/Half Uncle/Aunt/Niece/Nephew, Great-Grandparent/Grandchild 6 6
1st-3rd cousin 1 1
2nd-3rd cousin 5 4
2nd-4th cousin 127 132
3rd-5th cousin 1937 1900
4th to remote 6938 5676
Total 9014 7719

The closest relationships remained the same. One 2nd-3rd cousin moved to the 2nd-4th cousin range by losing 10 cM, 194 cM to 184 cM, but they were apparently on the threshold anyway. That match is actually my second cousin, so both ranges are accurate. It was also a transfer kit, so they did not test at FamilyTreeDNA. This revised match is probably the difference between actual reads and imputed reads in some regions, meaning the match is now more accurate.

275 matches had a predicted relationship change, but not uniformly in one direction, and no one moved more than one category in either direction. This all makes sense.

Match Differences

  Number
Matches found in both the apricot and purple spreadsheets 7,352
Unique (comparable) matches in both spreadsheets 7,174
Matches in original Family Finder apricot only 1,681
Matches in NGS purple only 400

A total of 7,352 matches appear in both spreadsheets, meaning the apricot and purple names matched exactly.

Unfortunately, some people had multiple tests, so I couldn’t always compare apples to apples because they appear three times or more on the combined spreadsheet, and I don’t know which of their kits are which.

If someone with the same exact name had more than one match for either or both tests, I did not compare them because their matching amounts were different, and I didn’t know which one(s) my old test matched, versus which one(s) my new test matched. Usually, one was an upload and one was a test at FamilyTreeDNA, but not always. I excluded those 178 match rows from the analysis.

Therefore, 7,174 matches could be directly compared.

There were 1,681 people who match ONLY on the old Family Finder test, and 400 that match only on the new NGS test. And yes, I downloaded the match files at the same time on the same day, so this comparison was controlled for any time difference.

cM Differences

  Number
Largest apricot match not in purple (NGS) list 26.3 cM
Largest purple (NGS) match not in apricot list 27.63 cM
Largest difference 69.86 cM NGS kit more
NGS detected greater over 10 cMs 19
NGS detected less over 10 cM 7
Total NGS greater 2,924
Total NGS less 3,040
No change 1,090

The largest value difference where a match appeared in the original apricot Family Finder test, and not in the purple NGS test, was 26.3 cMs.

The largest value difference where a match appeared in the NGS purple Family Finder test, and not in the apricot original Family Finder test was 27.63 cMs.

The largest difference between the two tests was 69.86 cMs larger detected by the NGS test. This match was a known second cousin whose matching cMs went from 373.06 to 442.92, but the longest block only increased a negligible amount from 87.47 to 87.69.

The next largest difference was with a 1C1R with a 41.56 cMs difference, also with the NGS-detected value being larger.

In all cases where the number of differing cMs was 16 or greater, the NGS had detected more.

There were very few tests that differed more than 10 cMs. In 19 cases, the NGS test detected a greater difference of 10 cMs or higher, meaning if the original test value was 100 cMs, in the NGS test, it was 110 cMs or greater.

In 7 cases the NGS test detected a smaller difference of 10 cMs or more, meaning that if the original test value was 100 cMs, in the NGS test, it was 90 cMs or smaller.

Out of the 7,174 tests being compared, 19 tests with greater than a 10 cM variation isn’t very many, around 0.26%.

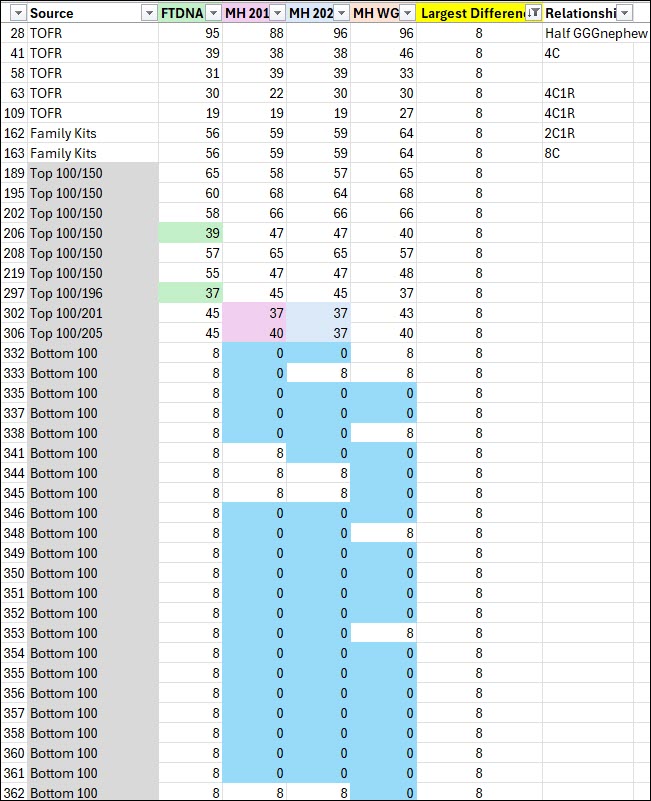
In total, 1,090 matches had no change at all, while 2,924 NGS matches had more matching DNA detected, and 3,160 matches had less.

All but 287 of those differences were less than 5 cMs, and 6778 were less than 1 cM. In other words, literally not worth counting.

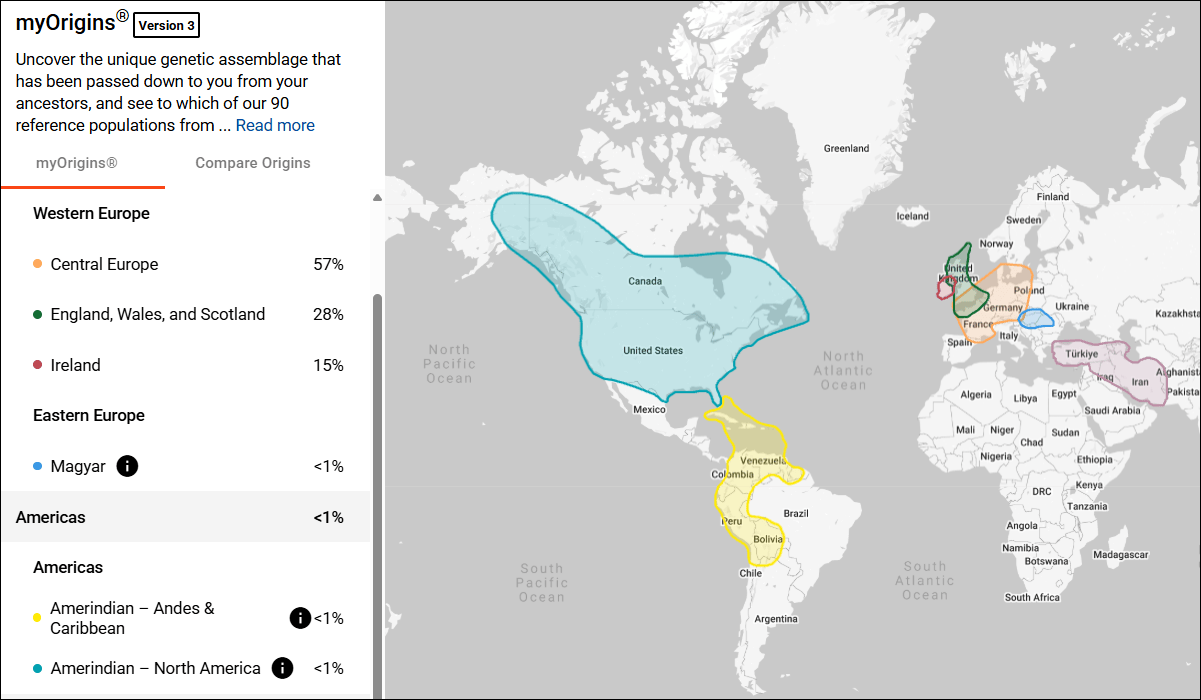
myOrigins Ethnicity

We all know to expect changes in our ethnicity from time to time at all vendors. The NGS test is exciting because it covers a much larger portion of our genome. As more people test, the reference library also becomes larger, which means that the ethnicity predictions can and will become more refined too

myOrigins Old Family Finder (apricot) NGS Family Finder (purple)
Central Europe 57% 52%
England, Wales, Scotland 28% 33%
Ireland 15% 14%
Magyar <1% <2%
AmerIndian Andes and Caribbean <1 (see below) N/A
AmerIndian North America <1% (chr 1 & 13) <1 (chr 1 & 2)
Anatolia, Armenia, Mesopotamia, North Africa <1 (chr 13) <1% (chr 10)

None of my major categories changed, but the amounts attributed to each category changed somewhat.

Trace regions, which are less than 1%, shifted some as well, as did their chromosome locations.

For me, this is particularly interesting, because I paint my ethnicity segments at DNAPainter in order to overlay my Native American segments over the matches with whom I’ve identified common ancestors.

Those segments, matches, and ancestors, taken together, help identify the source of the Native American segments.

My Native segment on chromosome one stayed essentially the same, but the Native segment on chromosome 13 is not present on the new NGS test. However, a new Native American segment is now shown on chromosome 2 in the same location that 23andMe also shows a Native American segment.

Chromosome one has already been proven to a Native American ancestor on my mother’s side, but I have hit a brick wall on the chromosome 13 segment. Now, I’ve painted the Native Segment on chromosome 2 and it aligns with the same ancestral line as my Native American segment on chromosome 1.

My Middle Eastern/North African segment still exists, but the location has changed. This segment was adjacent to my Native American segment on chromosome 13 before, on my father’s side, which suggested a history of enslavement. I thought I knew which ancestral line they both descend from, but now I need to review my matches and reconsider.

Unfortunately, my parents are both deceased and there’s no DNA available, so I cannot upgrade their tests or purchase new ones for them. No aunts or uncles are available either. In this case, cousin matches and their associated genealogy on those segments become critically important.

Native American and African American segments are often the best, and sometimes the only hints we have to find and identify those ancestors.

Preparing for Your NGS Results

To be very clear, you don’t necessarily need to compare or prepare, BUT, if you order an upgrade to an existing test, your old match list will be replaced with the new one. Your old match list will not be preserved unless you do it.

What may change?

  • Your ethnicity results will probably change somewhat
  • You will have matches you did not have before
  • Some existing matches, especially at low matching levels, will no longer be there
  • The amount of DNA you share with some people will change

Important: Any notes you have recorded on your matches and any matches that you have linked will be preserved and carried over to your new results when your new test is complete.

If you want to preserve your matches from your earlier test, or your myOrigins results, you’ll need to download your match list, and either download or take screenshots of your ethnicity information.

Ability to Download Tested at FamilyTreeDNA before March 2, 2026 Uploaded and purchased the Unlock Uploaded but did not purchase the Unlock
myOrigins Can download Can download Cannot download
Chromosome Painter (ethnicity) Can download Can download Cannot download
Match list with segment and other information Can download Can download Cannot download
Raw data file Can download Cannot download* Cannot download*

*On tests you uploaded, you don’t need to download the raw data file because you already have it from the originating vendor.

What information is included in your Match List download file?

  • Match name
  • Relationship Range
  • Shared Data cMs
  • Longest Block cMs
  • Linked Relationship (if you linked them in your tree) – this feature is what allows FamilyTreeDNA to assign your matches maternally, paternally or to both sides using triangulation
  • Ancestral Surnames that they’ve entered
  • Y-DNA Haplogroup if applicable
  • mtDNA Haplogroup if applicable
  • Notes
  • Paternal/Maternal or Both side(s) match (if you’ve linked people and this match can be assigned using triangulation. (This is why it’s important to link as many people as possible to their place in your tree.)
  • X-Match cMs
  • Autosomal Transfer yes/no

If you match the same person on the NGS test, this information is preserved for that match.

Where to Download

You must have 2FA (Two-Factor Authentication) enabled for all downloads.

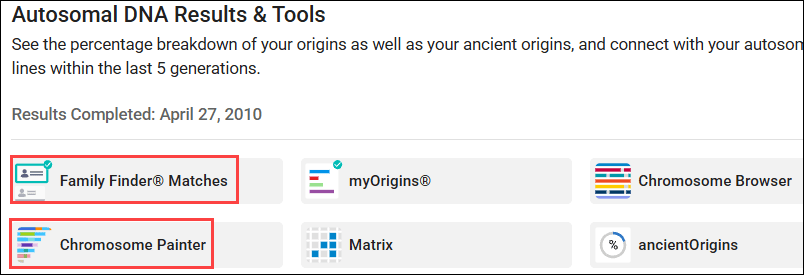
The files you may want to download are found on your dashboard in two locations.

  • Family Finder Matches
  • Chromosome Painter (ethnicity)

Family Finder Matches Download

To download your list of matches with their complete information, click on Family Finder Matches on the dashboard, then on “Export CSV.”

This download provides all the fields mentioned above, whereas the Chromosome Browser segment download provides only your matching segment data, without the additional information.

Download MyOrigins Ethnicity Segment Data

To download your myOrigins ethnicity segments, click on Chromosome Painter on your dashboard, then on “Download Segments.” You can also view or copy those segments by viewing the Detailed Segments tab.

I paint these segments at DNAPainter so that I can correlate my ethnicity regions with my ancestors’ segments.

To assign segments accurately, it helps immensely to have at least one parent’s DNA results too, and preferably both.

You may also want to take a screenshot of your myOrigins map. Note the left-side scroll bar when you’re taking screenshots.

What’s Next?

What else can you do at FamilyTreeDNA to benefit your genealogy?

  • If you haven’t already, upload a GEDCOM file or create a tree at MyHeritage, and link your Family Finder test to your results.
  • Link your individual matches to their place in your tree. This allows FamilyTreeDNA to use segments triangulated with linked matches to assign other matches to either the maternal or paternal side of your tree, or both.
  • Add your line to WikiTree. It’s easy. Begin with yourself and add ancestors until you connect with someone who is already in WikiTree. For me, it was the grandparent level.
  • Add your WikiTree link to your FamilyTreeDNA account under the gear in the upper right-hand corner, then Genealogy, then Family Tree. This gives your matches an easy way to identify common ancestors by using WikiTree’s Find Relationships feature, and provides two types of tree resources for you and your matches – MyHeritage and WikiTree.
  • Make sure your Earliest Known Ancestor information is correct and up-to-date with your most recent research, including a specific map location. You’ll find that under the gear too, then Genealogy, then Earliest Known Ancestors.
  • Add your surname list to your profile under the gear, Genealogy, Surnames tab.
  • Use the Matrix tool at FamilyTreeDNA to see how much DNA your shared matches share with each other.
  • Y-DNA – If you’re a male, test your Y-DNA, which is your father’s direct paternal line. The Big Y-700 test provides you with matches and the most detailed information possible.
  • mtDNA – Everyone can take a mitochondrial DNA test, which shows matches and provides information about your mother’s direct matrilineal line.
  • Use Advanced Matching, found under Additional Tests and Tools on your dashboard page, near the bottom, which allows you to select from multiple tests to see who matches you on both types of tests. For example, those who match you on both your full sequence mtDNA test and your Family Finder test.
  • Join projects relevant to your family surname, geography or broader interests. You’ll find Group Projects in the top banner of your dashboard page after signing in.
  • Utilize the Discover tools for both Y-DNA and mitochondrial DNA results.

Check your matches often to see who is new and what might have changed as people upgrade to the new NGS test and more people test.

_____________________________________________________________

Share the Love!

You’re always welcome to forward articles or links to friends and share on social media.

Subscribe!

If you haven’t already subscribed, it’s free. You’ll receive an e-mail whenever I publish by clicking the “follow” button at the top of the main blog page, here.

Help Keep This Blog Free

I receive a small commission when you click a vendor link in my articles and purchase that item. This does NOT increase your price but helps me keep the lights on and this informational blog free for everyone. Please click on the affiliate links in the articles or to the vendors below if you are purchasing products or DNA testing.

Thank you so much.

DNA Purchases and Free Uploads

Genealogy Products and Services

My Books

Genealogy Books

Genealogy Research

What is a Quick-and-Dirty Tree, and When Might I Need One?

You may have heard genealogists talk about creating a quick-and-dirty tree.

What is that, exactly? When and why would you want one?

Good questions.

Matches and Trees

DNA matches don’t always have useful trees.

They might have:

  • No tree
  • A partial tree with only a few people in the closest generation or two
  • A tree with some lines built out, but others not so much

What’s a genealogist to do? After all, it’s your match’s tree, not your tree, and you have no way to expand their tree.

Except, you do.

It’s called a quick-and-dirty tree.

Quick-and-Dirty Trees

A quick-and-dirty tree is essentially a “throw-away” tree that you construct at Ancestry with the express purpose of obtaining hints, including potential parents, in order to quickly build your matches tree backwards in time until you (hopefully) reach a common ancestor.

And yes, of course trees, hints and suggestions of any kind can be wrong – but that doesn’t mean they’re always wrong, and you’re not adding anything from your quick-and-dirty tree to your tree – or even displaying it publicly.

You’re simply trying to find a common ancestor by using what your match has provided in their tree. Think of a quick-and-dirty tree as a scratch pad of sorts.

Let’s work through an example.

Initial Analysis

In this example, Ancestry has already told me that this match is most probably my half-second-cousin (half 2C) or second-cousin-once-removed (2C1R) based on the amount of DNA that we share, although the full relationship range includes several more options.

Ancestry also tells me that this match is on my maternal side. There’s no information provided about whether this match is on their maternal or paternal side, or even both.

A second-cousin (2C) relationship means that we share great-grandparents, and once removed means that one of us is one step further down the tree than the other person.

In other words, I’m 2C with my match’s parents, or my match is 2C with my mother. I wrote about this in the article, Concepts: What Does a Cousin “Once Removed” Mean?

I see that my match has a public linked tree with 7 people, which probably isn’t going to be terribly helpful.

Of course, the first thing to do is to review my match’s tree and see if I recognize either their surname or the names in their tree.

This tree only reaches back two generations, and our common ancestor, based on the relationships predicted by shared DNA, would be another generation, or two, further removed.

I don’t recognize any of these names, although I’ll review each person for a location to see if I can narrow the scope to the couple most likely to lead to our common ancestor.

On my mother’s side, one of her parents is from northern Indiana, and one is from southern Indiana, but not everyone enters locations in their trees, and they aren’t necessarily accurate.

The list of “all people” in my match’s tree, under “Find in tree”, at far right, provides additional information. Unfortunately, this tree shows Earl Townsend’s wife’s name as Mildred Ideal Thorstenson Townsend Smith here and in her profile, but the name order differs. To begin, I’ll enter Thorstenson Smith, not her married name of Townsend, in the quick-and-dirty tree I’m building. You can refine this shortly.

In this case, it looks like the Townsend line is most promising to find a common ancestor, given that Fulton County is in northern Indiana, but we’ll find out that this isn’t the case when we construct our quick-and-dirty tree.

Building the Quick-and-Dirty Tree

You need to build a new tree, NOT add to your “real” tree.

At Ancestry, go to Trees in the top banner, then click on “Create and Manage Trees.”

You’ll see the list of trees that you own. This is where all of the trees that you create live.

At the far bottom, you’ll see the prompt to create a new tree. Click there.

Next, you’ll see a blank tree.

For the home person, you can enter your match’s name, but be sure to list them as living so you’re not revealing private information.

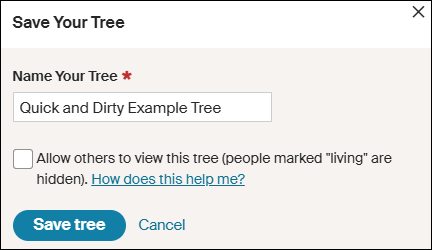
After adding one parent, you’ll be prompted to save and name the tree. Both the tester, who is designated as male by the Ancestry icon, and his father are either both living, or private, so I’m simply entering the surname of Robinson based on the grandfather’s surname. That could be incorrect of course, but it’s all I have to go on – yet.

Ironically, their grandfather’s surname was spelled Robison, without the “n”, not Robinson, but I accidentally entered Robinson and still got where I needed to go.

Clearly, I’m not going to allow this tree to be viewed by others, aka public, so I’m not checking that box. If it’s checked by default, uncheck it.

I don’t make my quick-and-dirty trees public because they are entirely unproven and unverified. I’m literally quickly searching for hints with every intention of abandoning the tree when I’m finished. If you want to clean the tree up later, you have the option to change the tree’s privacy settings.

Information in Your Match’s Tree Might Be Wrong

Complete the tree to be the same as your match’s tree. After saving your tree, click on the individuals you’ve added to view their hints.

Let’s start with Earl Townsend who appears to be our best candidate based on location.

Earl Russell Townsend has 13 hints, including a marriage license that confirms his birth date and location and provides the names of his parents, plus his wife’s name as Mildred Thorstenson. Based on what we know already, this is probably the correct Earl Townsend.

Of course, the wife’s surname could be incorrect. It could be her first or second marriage, or she could have been a widow when they married, so this surname might not be her birth surname.

Look for additional records in Earl’s hints.

Russell’s death certificate confirms that information, as do the birth and death certificates of their children.

Accept those hints.

If you determine that the original information in your match’s tree is incorrect, you’ll want to correct it in your quick-and-dirty tree. Remember, this is a scratch pad – you can’t hurt this tree.

Let’s change Mildred’s name to reflect her birth surname.

I refined Earl’s wife’s name to Mildred Thorstenson, which then produced 12 hints for her, including her marriage and Social Security record, with her birth and death dates, and her parents’ names. Her name in my match’s tree of Mildred Ideal Thorstenson Townsend Smith had produced zero hints.

Additionally, census records showed Mildred with her parents.

These seem to align, so accept those hints.

Looking at the pedigree view of my quick-and-dirty tree, we now see that both Russell and Mildred’s parents identified in the records are suggested as their potential parents.

Review each suggestion. If they look accurate based on the records identified, accept those potential parents in order to view the next generation.

Based on these names and census information, I can eliminate the Thorstenson line. It’s Swedish, not German or Dutch, which comprise my mother’s northern Indiana lines, My mother has no known Swedish ancestors, and we have proven her Indiana lineage in this timeframe.

Accepting the hints for the parents of both Earl Townsend and Mildred Thorstenson, parent hints appear for John Townsend and Eva Martin.

Now we’re viewing the next group of hints, which would be the great-great-grandparent generation. If these are our common ancestor, that would mean that I’m third cousins with my match, which is beyond the predicted relationship range. Third cousins is not impossible, but it’s beyond the probable match level based on the amount of shared DNA. furthermore, I don’t recognize any surnames.

So, let’s move to the Robison (incorrectly spelled Robinson) line and step through the same process. We can always come back and work with more parental hints on the Townsend/Martin line if we need to.

Rolland Robison only has a death year in my match’s tree, and that combined with the misspelled surname meant he had no hints on Ancestry, so I clicked on “Search” in my quick-and-dirty tree.

I’m searching for a man by this name, with a wife whose first name is Chloe.

AHA!

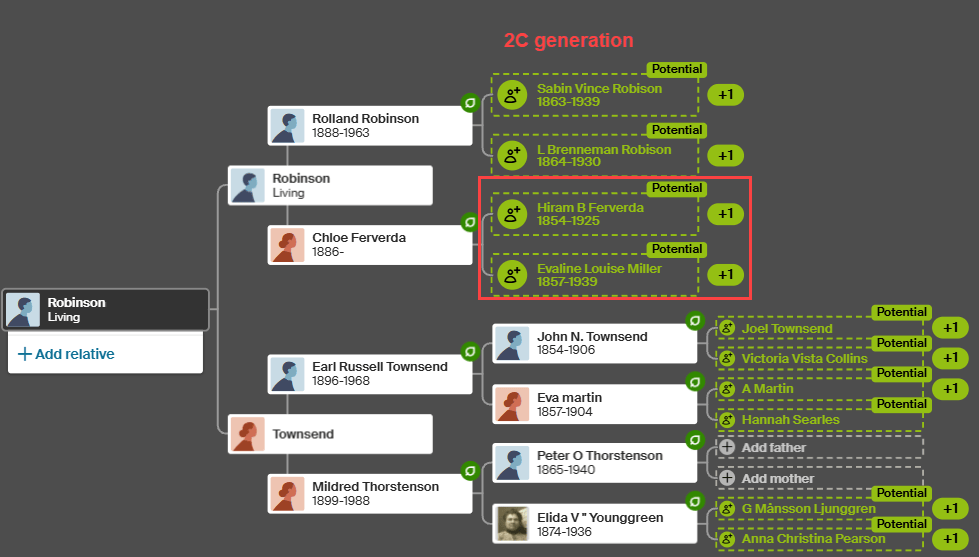
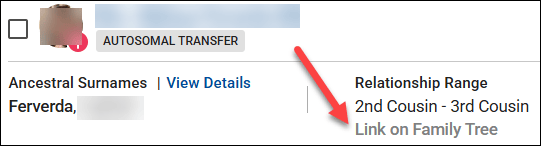
There it is! Note that Ancestry found Rolland Robison, not Robinson, married to Chloe.

Chloe was a Ferverda. My mother’s father was John Ferverda, and the location is correct for this family.

I saved this record to Rolland Robinson and added Ferverda as Chloe’s surname in our quick-and-dirty tree. This provided Rolland with 12 hints.

Adding Ferverda as Chloe’s surname provides her with a dozen hints too, including potential parents, Hiram B. Ferverda and Evaline Louise Miller – my great-great-grandparents who are indeed the 2C generation.

These common ancestors fall within the expected amount of shared DNA for second cousins, so this aligns well.

My quick-and-dirty tree has revealed at least one pair of common ancestors. Could there be more common lineages? Yes. I would continue building out this quick-and-dirty tree for (at least) another couple of generations on the other lines just to be sure.

What Next?

That depends on what you want to accomplish and your genealogy goals.

I used a DNA match at Ancestry in this example, but your match might be at a different vendor. Regardless, you’ll still want to use Ancestry to build your quick-and-dirty tree based on how they present hints and potential ancestors.

Now that you know how your DNA match connects:

  • Minimally, make a note on the match that indicates the most recent common ancestor(s) identified. I include a link to the quick-and-dirty tree I’ve created.
  • You can add your match and their ancestral path to your common ancestor into your own tree at whichever vendor where the match occurs.
  • If you match at either FamilyTreeDNA or MyHeritage, both of whom provide segment information, I suggest painting your matching segments to DNAPainter.

Painting your segments identifies your matching segments as descending from those ancestors and makes it easier to identify the shared ancestral lineage of anyone else who shares that segment on the same side of your tree (maternal or paternal).

Word of caution here: You can potentially share multiple ancestral paths with any match, so different segments with one match can descend from different ancestors.

  • If your match is at FamilyTreeDNA, you’ll want to link your match to their place in your tree.

Using triangulation, FamilyTreeDNA utilizes linked matches to assign matches who share the same segments to the maternal or paternal side of your tree (or both) using triangulation.

  • You may be trying to break through a brick wall by identifying common ancestors BETWEEN your shared matches that aren’t in your own tree.

This approach is obviously easier the closer your brick wall is in time to the present. Great-grandparents, at the second-cousin level, and great-great-grandparents at the third-cousin level are much easier than 5th- or 6th-generation ancestors who lived before birth and death certificates and detailed census records existed.

Furthermore, the further back in time, the more likely that you may encounter:

  • Pedigree collapse, where the same ancestors appear more than once in your tree
  • Or you share multiple common ancestors with your matches

Of course, there’s always the possibility of endogamy too, where you descend from a historically heavily-intermarried population, such as Ashkenazi Jews or the Amish, for example, which means you may share segments passed down within the population from distant common ancestors you won’t be able to identify. While endogamy in your lineages may increase the amount of shared DNA, which in turn can skew relationship estimates, it won’t prevent you from using quick-and-dirty trees to locate common ancestors.

And finally, unexpected parentage or issues like record destruction may impede your progress, but you’ll never know if you don’t try, which brings us back to the purpose of quick-and-dirty trees.

Building a quick-and-dirty tree is the easiest way to grow your matches’ trees to reveal your common ancestors.

_____________________________________________________________

Share the Love!

You’re always welcome to forward articles or links to friends and share on social media.

Subscribe!

If you haven’t already subscribed, it’s free. You’ll receive an e-mail whenever I publish by clicking the “follow” button at the top of the main blog page, here.

Help Keep This Blog Free

I receive a small commission when you click a vendor link in my articles and purchase that item. This does NOT increase your price but helps me keep the lights on and this informational blog free for everyone. Please click on the affiliate links in the articles or to the vendors below if you are purchasing products or DNA testing.

Thank you so much.

DNA Purchases and Free Uploads

Genealogy Products and Services

My Books

Genealogy Books

Genealogy Research

Robert Vernon Estes (1931-1951): DNA and Hope for Military Repatriation

Robert Vernon Estes was my first cousin, my father’s brother’s son. I’m named after him, but I never knew him. He died years before I was born.

Robert, known as Bobby, was born on March 27, 1931 in White County, Indiana. He, along with his unit, were captured near Kunu-ri in North Korea on November 30, 1950, and he died as a prisoner-of-war around January 31, 1951 – at least that’s the date officially assigned to his death.

Truth be told, his death date is an estimate based on the recollections of men who survived the horrific deprivation, freezing temperatures, and starvation endured by the captured soldiers. He was likely buried in a mass grave outside the compound where Bobby, along with most of the other US soldiers who were held there, died.

Bobby was posthumously awarded the rank of Corporal. 

The Korean conflict active combat operations ended on July 27, 1953, when an Armistice agreement was signed between the US, North Korea, and China. A demilitarized zone (DMZ) was established, but a peace treaty was never signed, so technically, the US and North Korea are still at war. The two countries do not maintain diplomatic relations, and their relationship could be described as “frosty” at best.

While some military personnel from both the US and our ally, South Korea, have been repatriated, a long history of hostility and other challenges, including the remains of US soldiers being used as bargaining chips, have prevented the return of more than 5300 service members whose remains are still essentially being held hostage in Korea. If I sound bitter, that’s because I am.

Beginning in 1954, some remains have been brought home, but identification from the beginning was difficult, often due to comingled remains resulting from mass burials. Those remains were identified when possible, using techniques available at the time, and all remains were honorably buried.

Recently, due to advances in processing forensic remains and autosomal DNA matching, another 100 people have been identified from 55 boxes of mixed remains turned over following the 2018 Singapore Summit. Those boxes are believed to hold bones from roughly 250 distinct individuals, so the majority have yet to be identified.

Unidentified remains are buried at the Punchbowl, the National Memorial Cemetery of the Pacific, in Honolulu, Hawaii. More than 800 graves are marked as “Unknown” from the Korean War and await exhumation for advanced DNA testing.

By Gage Skidmore from Surprise, AZ, United States of America – National Memorial Cemetery of the Pacific, CC BY-SA 2.0, https://commons.wikimedia.org/w/index.php?curid=115138509

While there is no burial, missing service members are honored in the Honolulu Memorial within the cemetery. 

The names of the missing are etched on the walls of the Courts of the Missing.

Bobby’s name was also engraved on the Wall of Remembrance at the National Korean War Veterans Memorial in Washington DC when they included the names of the missing in 2022.  

Here’s a closeup.

Because Bobby was held above the DMZ, in North Korea proper, in a deserted mining camp called the Pukchin Camp, nicknamed Death Valley, and because the North Koreans were uncooperative, Bobby’s remains were classified as “nonrecoverable” in January 1956.

Hope Rekindled

Unrecoverable in 1956 based on political circumstances and lack of information about which soldiers had been captured, where they were held, when they died, and where burials for that facility occurred, doesn’t necessarily mean unrecoverable forever.

Today, Bobby’s status has been updated to “deferred” which isn’t quite as final and hopeless as “nonrecoverable.”

In 1956, they had no way of knowing about DNA and technology that would become available decades in the future.

Unfortunately, the political environment has remained essentially unchanged now for 70 years, but 70 years isn’t forever.

Yes, I know that identifying Bobby’s remains and bringing him home are both extremely unlikely, but a very low probability is not zero.

As genetic genealogists, we understand that with the passage of generations, the amount of shared autosomal DNA decreases with each generational recombination, so it was important for me to work with AFDIL to preserve my DNA in the hope of one day identifying Bobby – even after I’m gone from this mortal realm.

I might not be able to stand in Arlington, honoring Bobby as he is buried, but maybe my daughter will. Hope springs eternal!

DNA Analysis

The military began collecting DNA samples using bloodstain cards in 1992. For soldiers who served before that and whose remains needed to be identified, various types of forensic analysis were performed.

In the 1990s, when DNA first began to be used for service member identification, DNA matching was performed using mitochondrial DNA because there are hundreds of copies of mitochondria in the cytoplasm of each cell, which means mitochondrial DNA is easier to recover in degraded remains.

This also meant that a sample was needed from the soldier’s mother, sibling, or a relative in the soldier’s direct matrilineal line, not interrupted by a male. Women contribute their mitochondrial DNA to children of both sexes, not intermixed with any DNA from the father, but males do not pass it on to their children.

Around 2010, Y-DNA, passed from father to son, began to be used by AFDIL as well.

At that time, the remains were not processed to extract DNA for autosomal matching, as ancient or forensic DNA extraction technology did not yet exist – and has only been refined for widespread utilization in the past few years. Initially, autosomal matches for repatriation were only used to match immediate family members, so DNA testing was unavailable to cousins of soldiers.

Men who died in WWI, WWII, Korea, and Vietnam may not have immediate family members left – and that number dwindles daily.

  • Bobby had no children.
  • Bobby’s mother, Lucille Latta, was born in 1906 and died in 1952. She had only one sibling, a brother who died in 1966, and their mother was adopted, so there was no source to obtain Bobby’s mitochondrial DNA for matching.
  • Bobby’s only sibling, a brother who had no sons, died in 1986, and their father, Joseph Estes, died in 1994, eliminating the possibility of Y-DNA matching.

This means that there were no immediate or appropriately related family members available for either mitochondrial or Y-DNA testing – effectively slamming the door on the possibility of identification.

The DNA results of soldiers’ remains, and their family members, are held separately from any commercial or law-enforcement databases, so without an appropriately descended family member’s DNA test submitted for this specific purpose, there is no opportunity to identify the soldier.

Until recently, more distant family members were precluded from participating.

The AFDIL Team

In 2023 and 2024, I was privileged to work with the AFDIL team on the Washington Family Project. This was a proof-of-concept project, of sorts. AFDIL undertook this project in the process of refining their methodologies for working with badly degraded remains. The Washington Project was perfect because we knew who was supposed to be buried in each location. The team authored an exciting paper detailing the results.

It gives me cold chills to realize that I was a small part of the effort to open the door for more distant family members to submit autosomal results to identify their missing service members. When we started working together, they had no idea that I’m a Gold Star family member, representing Bobby, and I had no idea the doors this project would open.

Today, those efforts have borne fruit. AFDIL has expanded its family participation policies and guidelines.

Needless to say, I’m thrilled.

Swabbing for Bobby

I requested my swab kit as soon as possible.

I was so excited the day the package arrived.

In addition to swabs, the package included a letter plus several pages of information and instructions.

For notification, be sure that someone living and reliable is listed as the primary contact for your soldier. We discovered that no one was listed for Bobby, but now I’m his official contact and I’m also his closest living next-of-kin.

Oh good, now we’re getting to the DNA swabbing part! Not that I’m anxious or anything!

I had to sit down and really study this chart, which was difficult given my level of excitement. I needed to make sure I really qualified. I mean, I knew I was supposed to – but this was the hard line do-not-pass-go paper right here. A tiny part of me was terrified that something had gone wrong and I wouldn’t be accepted.

The missing soldier is the blue center. I labeled “Me” four images to the right.

AFDIL invested a lot of time in creating this chart that includes autosomal candidates in yellow, mitochondrial candidates with red borders, and Y-DNA candidates with thick dark blue borders.

They had put an oval around “me” on the chart based on their understanding of our relationship from previously submitted documentation. In the paperwork, they asked me to confirm the relationship again.

Next came the swab kit and the labels.

Now I’ve swabbed and labeled everything, following the instructions.

Popping them into the included FedEx envelope.

All I had to do was find a FedEx shipping location and drop the envelope off. I cried as I did the handoff – praying that someday these little vials will provide the key to identifying Bobby.

A week or so later, I received an email stating that my sample had been received and was being processed.

They would be in touch if anything else was needed from me, or, if anything was found.

Now…we wait. Perhaps forever.

But maybe not.

I’ve now preserved the possibility of identifying Bobby’s remains if they are ever returned. And a tiny part of me has my fingers crossed that some of his bones were in that mixed sample, simply waiting for the technology to catch up.

This Memorial Day Weekend

This Memorial Day weekend, in addition to writing this article, I’m working on a wall-hanging to honor Bobby and his ultimate sacrifice.

I’ve been working on this for a while, but it’s so emotionally intense for me that I have to put it away and give myself a break from time to time.

Obviously, I’m working on the layout and I’ve laid these blocks alongside the panel to illustrate. When finished, there will be two rows of stars that function as borders surrounding the center panel.

I’m debating whether I should put a gold star in the center of both sides, or a smaller gold star in the center of a star block, or maybe gold stars of some sort in all four corners. I’m also considering having Bobby’s name, along with his birth and death dates, embroidered near the boots.

After my death and my daughter’s, I’ve left instructions for this quilt to be donated to the Indiana Soldiers’ and Sailors’ Monument, if they want it, where the brick honoring Bobby’s service was laid in the summer of 2021.

You can read more about Bobby in these articles:

Honoring Bobby and Other Unrecovered Soldiers

For years, it has been my dream to attend Bobby’s military burial at Arlington National Cemetery. He has earned that, and it seems that’s the least, the very least, we could do for him. Of course, part of warfare is psychological, not just physical, and refusing to return the remains of those killed is part of that. Even worse is knowing how he was tortured and died.

My heart still bleeds for him and his mother.

We don’t know if Bobby’s remains will ever be “discovered” and brought home. I’d say it’s extremely unlikely.

We don’t know if, by some miracle, Bobby’s remains are among those unidentified mixed samples already buried in Hawaii. That too is unlikely because Bobby was held in a remote location and his remains, wherever they actually lie, are not easily accessible.

As each generation dies, and as Bobby’s bones age, the chance of obtaining a quality DNA match decreases.

While I can’t do anything about the passage of time, nor about Bobby’s bones deteriorating, I can make sure my own DNA is preserved in AFDIL’s Family Reference Database, maintained by the Family Reference Sample Laboratory, a division of the Armed Forces Medical Examiner System’s DNA Identification Laboratory (AFMES-AFDIL). You can read more here and here.

You can search for a POW/MIA service member, here.

If you qualify to submit a sample for a deceased service member whose remains have yet to be identified, you can’t order a DNA sample kit directly like we do from testing companies. You need to request a DNA sample kit after providing information about how you and the soldier are related. You’ll be assigned a case number and a case worker.

Click on this link for more information, including websites, or call the appropriate number below to determine if you qualify and to request a DNA kit.

  • United States Army: (800) 892-2490
  • United States Marine Corps: (800) 847-1597
  • United States Navy: (800) 443-9298
  • United States Air Force: (800) 531-5501
  • Department of State: (202) 485-6106

This Memorial Day, please remember the sacrifices of our fallen heroes, those veterans who never came home, and their families who never stopped waiting.

The New FamilyTreeDNA NGS Family Finder Test

Click on any image to enlarge

Recently, in a press release, FamilyTreeDNA announced a new version of their Family Finder autosomal test that increases coverage from about .02% to about 9% of the human genome. Increasing coverage to this level using precision genomics holds great promise for the future.

Everyone who has purchased a Family Finder test since the beginning of March is automatically tested using the new technology – and it doesn’t cost any more than the earlier test.

Image not to scale because if it was, you would be able to see the bottom line at all:) This is meant to convey the message of more data!

As shown in this slide presented by Dave Vance, Senior VP and General Manager at FamilyTreeDNA, the new test covers 400 times more DNA locations than the industry-standard microarray chip-based test.

The typical vendor microarray autosomal DNA test covers somewhere between 400,000 and 750,000 locations.

Utilizing this new technology is an investment in the future.

You Don’t Know What You Don’t Know

To quote Dave:

Two numbers I want you to remember.

0.02 is the percent of your whole genome reported by standard autosomal tests today. All of your ancestry estimates, shared segments, and autosomal matches come from that small fraction.

9 is the percent of your genome that our new Family Finder test reports at high quality coverage. Starting right now — that’s over 400 times more data, from the very same test.

And the real point isn’t the number. It’s what that data makes possible. This gives us the foundation to unlock deeper, more meaningful insights — not just today, but for years to come. And when it becomes possible to go even further, I want FamilyTreeDNA to lead the way.

But what does that 9% mean for your genealogy research?

It means fewer unexplained matches, a clearer understanding of how people are related, and more confidence in the conclusions you draw from your autosomal DNA. Moving from connections to explanations, and from data to answers.

And until we can start rolling out those deeper insights, for now you’ll still get the same trusted Family Finder experience you’re used to — but you’ll also have the benefit of data that’s ready to unlock even more as new insights become possible.

In fact, you can watch Dave for yourself, at RootsTech, on the mainstage, here, having the unenviable position of following the Irish-step-dancing Gardiner Brothers. Yea, Dave, I didn’t get that gene either!

What makes NGS sequencing so special?

Sequencing Types

NGS is the abbreviation for Next Generation Sequencing, also called massive parallel sequencing. Rather than using individual probes, NGS is a high-throughput technology that simultaneously sequences millions of DNA fragments while still allowing targeting of specific regions.

Dave wrote about the differences between different types of sequencing, here.

All vendors select or target locations in the human genome that are most relevant for their product set, purpose or goals.

The older microarray sequencing machines have been in use for many years. They use probes to read specific targeted addresses, one by one, identifying which of four nucleotides is present at each location on your two copies of each chromosome.

The four nucleotides, adenine (A), thymine (T), cytosine (C), and guanine (G) are the building blocks of DNA, and you receive one from each parent at every location on chromosomes 1-22. Chromosome 23, the sex selection chromosome is a little bit different due to X-DNA and Y-DNA, but the locations are still read the same way using NGS technology.

The results of DNA testing are essentially a downloadable output file with the following information for each read:

  • The RSID SNP cluster ID chromosome
  • The chromosome number
  • The position (think street address) on the chromosome
  • The results, which are the abbreviations for the nucleotide found on the first and second strands of your DNA at that location

In autosomal DNA testing, positions on strands cannot inherently be identified as maternal or paternal without additional techniques such as parental comparison or phasing.

This data file is not meant for you to analyze, but for computers to compare to other DNA testers. Needless to say, the power of the data lies in the information it holds, such as ethnicity, haplogroup-identifying mutations, and matching with other testers.

The output files must be compatible with each other, or the vendors must make accommodations for any incompatibility.

Regardless of the sequencing type, currently, all genetic genealogy vendors’ download files use this same pattern.

The difference between the files and file types from each vendor is:

  • The technology used for the test
  • How much DNA is tested
  • How many rows of data are provided in the download file
  • The quality of the results

Sequencing Type Differences

Let’s put this in terms that we all understand.

With microarray sequencing, a utility worker is sent to each address to read the two nucleotides.

With both NGS and whole-genome sequencing, many addresses are read at the same time. Think of a fleet of drones flying over a neighborhood and reading what is written on the rooftops of each house address.

The difference between the type of NGS sequencing utilized by FamilyTreeDNA, and whole-genome sequencing is threefold:

  1. NGS targets specific addresses and neighborhoods in a controlled manner, because we know they are useful and are specifically interested in the data at those locations. In other words, it omits oceans, deserts, and other places that we know aren’t useful for genealogy.
  2. Whole-genome sequencing covers the majority of the genome, even though more than 90% of the genome is identical in all humans. In other words, the fleet of whole-genome sequencing drones flies over everything, including oceans and deserts, reading and storing everything.
  3. The number of times the drones fly over each address.

For example, a low-pass whole-genome test would fly over the entire world (your genome), scanning it once or twice, but there will be cloud cover and weather in some locations. Typically, you want at least two complete reads from each address to compare to ensure a minimum level of quality. The missed areas need to be estimated with tools like imputation to fill in the blanks.

The breadth of DNA covered is known as “coverage”, or “pass coverage”. So, whole-genome testing covers all or most of the genome, including more than 90% that is not genealogically relevant because it’s identical in all humans.

With NGS sequencing, you specify which locations or neighborhoods you want the drones to read, and you instruct them to fly over just those regions, say, 5 or 10 times. Even if there’s weather or another issue, chances are that at least some of those passes will be able to read both nucleotides.

How many times a particular location, or base, is read is known as “read depth” or “sequencing depth”. The greater the depth, the higher the quality and accuracy of the targeted locations, which means less imputation or “fixing” is needed.

Within the industry, confidence to coverage correlation is about 93% confidence of accuracy for both alleles at a given location at a depth of 5X, which rises to about 99% accuracy at a depth of 10X.

Using our examples, whole-genome sequencing covers about 98% of the genome, at a depth specified by the vendor. Low-pass whole-genome testing is typically performed at a depth of 2X, meaning each location is scanned twice.

NGS combines the best aspects of both “drone style” and “targeted” reads, providing the highest accuracy for the areas that are most important for genetic genealogy at an affordable price, while also targeting enough of the human genome to allow for new discoveries that may be important to either population genetics for ethnicity identification, or to identify your own family lineage mutations.

Yes, you can get both high coverage and very deep reads. That’s called medical-grade whole-genome sequencing, where your entire genome is sequenced to a depth of at least 30X, but it’s both expensive and not useful for genealogy. None of the genealogy vendors are prepared to, or need to, process the massive amount of data generated by a medical-grade whole-genome test, so there is no benefit to taking that type of test for genealogical purposes.

Why is NGS Sequencing Important?

FamilyTreeDNA has moved from the 700,000+ SNPs previously read on their microarray chip, to more than 280 million base pairs. So, from about .02% to about 9% of the 3.1 billion base pairs of the human genome.

Technology has improved to the point where NGS sequencing is no more expensive than microarray sequencing and provides substantially more results.

In other words, there’s no reason NOT to implement this technology now. The new Family Finder test is fully compatible with their earlier Family Finder tests, so everything is painless.

Plus, NGS allows FamilyTreeDNA to target specific locations that benefit their customers, such as both Y-DNA and mitochondrial DNA SNPs. Of course, you’ll still need to take the Big Y-700 or the full sequence mitochondrial DNA (mtDNA) test for full results and matching – but males will receive a confirmed Y-DNA mid-level haplogroup now, with midrange mtDNA haplogroups coming in the future for Family Finder testers. This is a feature that other vendors don’t target or provide at the same level.

I’m very hopeful that these foundation haplogroups will serve as an “appetizer” and will encourage more people to take both the Big Y-700 (males only) and the mtFull test (for everyone), as applicable, to receive those types of specific matches and learn more about their ancestors.

Speaking of the future, how do you future-proof your DNA?

Future-Proofing Your DNA

If you’ve already tested, should you purchase a new Family Finder test for yourself now?

No.

I know you didn’t expect that answer, but here’s why.

Everyone who purchases a Family Finder test, which uses NGS technology, receives the same matching and features as the legacy test.

FamilyTreeDNA doesn’t yet know the benefits and discoveries that will eventually be available, and they won’t know until after they have results of customers to work with.

Having said that, you will definitely want to future-proof your DNA and the results of anyone whose results you count on to help sort through your own.

So, let’s make a plan!

Assuring Future Compatibility

Plan 1 – Test Your Relatives:

Your closest relatives are your best assets. They help you determine how you match others, who you share ancestors with, and the identities of those ancestors. You absolutely need to test the following relatives if they are available:

  • Parents
  • Grandparents
  • Siblings, both full and half – test all of them if both parents aren’t available for testing.
  • If your sibling(s) are deceased or not available, their children carry half of their DNA, but not the same half, so test everyone available. You don’t need to test your siblings’ children if that sibling is available to test.
  • Aunts and uncles, or their descendants if they are not available
  • Great-aunts and uncles, or their descendants if they are not available
  • First and second cousins

Plan 2 – Person Has Never Tested:

Plan 3 – Already Tested at FamilyTreeDNA:

  • If they or you have already taken a Family Finder test at FamilyTreeDNA, an upgrade offer will be forthcoming soon. You don’t need to do anything now.
  • If the person is critical for your research, elderly, or there is some other reason for concern, the tester or kit manager can contact FamilyTreeDNA customer support now and inquire whether or not there is an unopened vial of DNA.
  • To assure that there is enough DNA left for the future, or that the DNA sample is not too old, you can request that a “C/D vial” set be sent to you/them just in case. Be sure the current address is valid.
  • This is also a good time to be sure that your/their Beneficiary Information and/or Kit Manager information is current as well. You’ll find both under Account Settings beside the name in the upper right corner of the page.

Plan 4 – Uploaded From Another Vendor:

  • If you uploaded your DNA file to FamilyTreeDNA from another vendor instead of testing there, hold your horses for now. You’ll clearly have to swab, because when you do an upload, only the data file is uploaded. No DNA is actually transferred or uploaded. I’m not sure what process will be put in place for transfer/uploaded testers, but FamilyTreeDNA will let you know when something is available.

What NOT to Do

I contacted FamilyTreeDNA and this is what they ask customers NOT to do:

  1. Don’t request that your current test be deleted so you can order a new one. This removes everything – linkages, trees, family matching, permissions, project membership, other tests, and notes. Not just for you, but for your matches who have done work on their match with you as well.
  2. Don’t order a second kit, which causes “twins” in the system. I don’t have inside knowledge, but I’ll bet there will be special upgrade pricing if you just wait a bit!

I’m Excited

I don’t know what the future holds, but I’m hoping for:

  • More granular ethnicity (we always want that, right?)
  • More confident matching
  • Improved relationship identification
  • Additional tools to identify descendants of specific ancestors
  • Tools to identify missing ancestors

As a contract member of the R&D team, I’ll let you know when my NGS results are back and how they compare to my matches on the current chip. You know I’m building that spreadsheet already!!

_____________________________________________________________

Share the Love!

You’re always welcome to forward articles or links to friends and share on social media.

Subscribe!

If you haven’t already subscribed, it’s free. You’ll receive an e-mail whenever I publish by clicking the “follow” button at the top of the main blog page, here.

Help Keep This Blog Free

I receive a small commission when you click a vendor link in my articles and purchase that item. This does NOT increase your price but helps me keep the lights on and this informational blog free for everyone. Please click on the affiliate links in the articles or to the vendors below if you are purchasing products or DNA testing.

Thank you so much.

DNA Purchases and Free Uploads

Genealogy Products and Services

My Books

Genealogy Books

Genealogy Research

RootsTech 2026 – The Wind Beneath Our Wings

I started writing this article on Sunday evening, the day after RootsTech ended, and I’m basking in the afterglow. Also, my back and feet may never forgive me.

As a tongue-in-cheek comment, I think someone coined the word “exhausterwhelmulated” and defined it as being exhausted, overwhelmed, and overstimulated all at once. Yep, that’s me.

However, I need to add another couple of words to this – gratitude and joy.

Gratitude and Joy

I’m going to try to express this without sounding too sappy.

Do you recall the joy you used to feel when you spotted a relative you loved dearly but didn’t get to see often? Think of the unbridled joy as you piled out of your parents’ car and spotted your grandmother coming out of the door because she saw the car pull up. You ran as fast as your little legs could carry you directly into her arms, and got hugged so tightly it nearly squeezed the breath out of you.

I don’t know what the word for that would be, but it’s similar to how RootsTech feels.

Let me explain. Continue reading →

MyHeritage Whole Genome Sequencing (WGS) Results and Comparison

I’m excited to receive my low-pass whole-genome sequencing test results from MyHeritage. When MyHeritage initially introduced their new test, I wrote about what that means in the article, MyHeritage Introduces a Low-Pass Whole Genome Autosomal DNA Test and Why It Matters.

In that article, I said I was ordering a WGS test and would publish a comparison of the new test with the two tests I’ve previously taken with MyHeritage, plus a test I uploaded to MyHeritage from FamilyTreeDNA in 2016.

Before I review these comparative results with you, I want to properly set expectations.

What To Expect from the MyHeritage Whole Genome Sequence (WGS) Test

From Ran Snir, Vice President of Product Management for MyHeritage DNA:

  1. Those who take a MyHeritage DNA test now are all sequenced with WGS and will receive the same access to features and results as those who have taken a MyHeritage DNA test and were genotyped with an old chip in the past. In fact, all samples processed by the lab in December were already processed with WGS.
  2. The transition to WGS does not introduce new features and capabilities immediately.
  3. The new WGS technology has minor implications when it comes to the ethnicity estimate results and DNA Matches, but people should not expect to get “something completely different”.
  4. The transition to WGS and having more people processed with it opens the door for deeper research and more insights. It will allow MyHeritage to drastically improve its phasing, imputation and matching algorithms. This will take time as MyHeritage needs to amass a lot of data first. In the long run, MyHeritage plans to improve the product, build new features and introduce new capabilities which will be based on learnings from WGS.

Thank you, Ran.

In this article, I am not focusing on ethnicity, but on DNA matches, which I depend on to help me unravel those pesky genealogy puzzles.

Also, please note, some features I’m discussing here are free with the purchase of a DNA test, and others require a subscription at some level. I have a subscription, and I use it nearly every day.

Coupon Code for a $20 DNA Test

That said, if you already know you want to order the WGS test, or you’re a new tester, use this special coupon code at checkout to reduce the test to $20 through the end of February 2026. That’s a great value!

Coupon Code: RobertaFeb26

Now, let’s look at my results when comparing the WGS test to the results of my other three tests at MyHeritage.

How does the new WGS test fare?

My Results

Before ordering my WGS test from MyHeritage, I already had three tests at MyHeritage to choose from.

MyHeritage allows you to select between different tests, including uploads and tests you’ve taken at MyHeritage at different times. There’s absolutely no need to delete older tests there, and in fact, I recommend that you don’t. This article illustrates why.

My four tests include:

  • FamilyTreeDNA (FTDNA) test uploaded to MyHeritage in 2016
  • MyHeritage health test taken in 2019
  • MyHeritage test taken in June 2024
  • MyHeritage low-pass whole genome test (WGS) taken in December 2025
FTDNA 2016 MH Health 2019 MH 2024 MH WGS
Total Matches 19,722 17,179 17,767 17,676
TOFR 128 111 108 Not ready

This chart shows the total number of matches and Theories of Family Relativity for each test in January 2026.

What Are Theories of Family Relativity (TOFR)?

I have several very useful Theories of Family Relativity (TOFR) where MyHeritage uses trees and other documentation, such as census records, to connect you and your DNA matches to common ancestors. TOFR is one of MyHeritage’s most beneficial tools.

In this example, my match only provided their father’s name, but that name was linked to our common ancestors by connecting through a FamilySearch tree. Often, multiple potential relationships and paths are shown. Like with any other tool, each theory needs to be reviewed for accuracy.

Please note that TOFR is only run periodically and has not yet been calculated for the WGS test results. I’m sure that will happen soon.

Evaluating Matches

I wanted to know if (and how) the same people matched me on the different tests, including the new low-pass whole genome (WGS).

  • Are there differences?
  • Are the differences slight or pronounced?
  • Do some people match me on some tests, and not others?
  • Do some people match me on earlier tests, but not the WGS?
  • Do some people match me on the WGS, but not earlier tests?
  • What is the takeaway from all of this?

To compare the results of all four tests, I created a side-by-side comparison spreadsheet.

The Spreadsheet

I created a spreadsheet where I recorded 434 individual matches by entering information in the following columns:

  • A – Match number that I assigned
  • B – Match source (more about this in a minute)
  • C – FTDNA 2016 test matching number of cMs
  • D – MH 2019 matching number of cMs
  • E – MH 2024 Health matching number of cMs
  • F – MH Low Pass Whole Genome Sequencing (WGS) matching number of cMs
  • G – Relationship if known
  • H – Common Ancestor if known

I included several other columns in my spreadsheet for my own genealogical research purposes that show my matches’ tree size, and the actual lineage from them to our common ancestor couple. However, for comparing matches and accuracy, I’ve utilized the columns indicated above.

Match Sources

I wanted to compare different types of matches, meaning not just the closest or the most distant, or only the matches I can identify. These are the sources of the matches I compared.

  • Cousin Finder – I actually started a spreadsheet back in October 2025 when I was using Cousin Finder to find cousins, meaning people with common ancestors identified by MyHeritage. Twenty-eight of the 378 people that MyHeritage identified as cousins are DNA matches, so those were the first matches I entered into this comparison spreadsheet, along with our most recent common ancestors.
  • TOFR – All Theories of Family Relativity begin with DNA matches, then connect you and your matches together using trees and/or documents, when possible. Because matches vary with each of the tests, so do the TOFRs. WGS theories aren’t yet calculated, but the matches are, so I’ve included TOFR matches here.
  • Family Kits – These 15 matches are family members’ tests that I manage and match, so I clearly know how we’re related.
  • Top 100/150 – The first group of matches, other than the above categories, were the top 100 matches using the FamilyTreeDNA 2016 kit, which was my first test at MyHeritage. All tests continue to accumulate matches over time, so it just made sense to start here.

However, after I finished transcribing each of those 100 matches into the spreadsheet and started transcribing the top 100 matches for the MyHeritage 2019 test, I quickly realized that the top 100 matches were not the same between tests. Therefore, I used the top 100 matches from all 4 tests. For every name included from any test in the top 100, I included the matching cM amount from all four tests. This means that in total, there are more than 100 in the “Top 100”, so now it’s called the Top 100/150, but all of the top 100 matches from each of the four tests are included in the spreadsheet. In total, there are about 220 in that category.

  • Bottom 100 – Last, I included the bottom 100 matches on the FTDNA 2016 kit, meaning I listed those and searched for them on the other tests. If I had included the bottom 100 from all four tests, it would have been more like the bottom 350.

When I finished listing all of these matches, I had 434 to work with for this comparison. .

Minimum Matching

The minimum MyHeritage reported match is 8 cM, and at that level, a surprising number of tests don’t match either parent, although some clearly match with close relatives on that parent’s side, which means that either:

  • Those tests (either mine or the match’s, or both) were uploaded and imputed
  • Some portion of the parents’ test did not read
  • These are not valid matches, meaning they are identical by chance, not by descent.

About Imputation

Imputation is a widely used technology among vendors to bridge small sections of unread DNA. This is useful when comparing files from different vendors for matching.

Vendors use imputation internally too.

For example, vendors often use different DNA chips in the lab. They sometimes change chips internally, as well, for a variety of reasons. Regardless of why, the same locations aren’t always read, or aren’t read successfully. Imputation levels the playing field, allowing backwards compatibility, and compatibility for matching across platforms. Imputation fills in the blanks to equalize those files, allowing them to be compared for matching.

Let me give you an example. Let’s say you have the letters c_t, where the middle letter between c and t is missing. In English, there are a limited number of letters that can be. To begin with, it must be a vowel. In this case, it has to be either a, o or u. Next, looking at context, if the surrounding words are “the c_t chased a mouse,” the missing word is not cut or cot. It’s almost certainly cat, so the “a” is filled in using imputation.

Imputation usually works well, but occasionally it can extend matching areas improperly. This has always been true, and it’s still true with the new low-pass WGS test. The new WGS test only scans the genome twice to keep the test affordable. Any “no read” area must be imputed. I wrote about imputation here.

Ok, back to the MyHeritage comparison!

Test Comparison Methodology

If you’re recreating this process with your own results:

  • Color-code the column headers for the various tests
  • Label them clearly so you can easily differentiate between tests
  • Freeze your top row

Select the test you want to search for matches, and record the people you want to cross-check. I began the process with my FTDNA test that I uploaded to MyHeritage in 2016.

I entered the matches on my spreadsheet, recording the matching cM amount. Then I selected the other tests, one by one, and searched for the same match name.

In this case, I started with the FTDNA 2016 test. Jane Jones (not her real name) matched me at 744 cM.

Then I selected the MyHeritage 2019 test, searched for Jane’s name, and recorded the match amount – 739 cM. I did the same with the 2024 test, and last, the WGS test.

When searching by surname at MyHeritage, don’t always expect the person to be at the top of the list where you might expect. Be sure to scroll down a bit, even to page two, especially with common names. MyHeritage also displays people with the same surname in their trees.

Match Analysis

As we work through these match results, keep in mind that the comparison percentage numbers only pertain to the 434 people that I’ve selected to compare across all four tests. This is NOT the total amount in any category for all of my matches. There’s no way to make that determination without manually comparing every single match for all four tests – which is why I selected what I felt was a representative sample.

You’ll quickly discover that many people DON’T MATCH you on all the DNA tests. You’ll notice as I give examples that I’ve colored coded some cells for my own use in both interpreting matches as well as sorting them. For example, People who don’t match on that test were labeled “none” and colored bright blue. Eventually, I simply entered “0” instead of the word “none” so I could perform math functions on those cells. I retained the blue so I could filter by cell color. You get the idea.

Using the new WGS test, 16 people (3.7% of 434) match me ONLY on the WGS test, but do NOT match me on any of the other tests.

Interestingly enough, they are all in the Top 100/150 category for the WGS test. Those match results range from 45 cMs to 53 cMs.

That’s NOT a trivial amount of DNA. It’s rather confusing how someone could match at that level on the WGS test, but not at all on the others.

Equally as interesting is that two of those 16 WGS matches don’t match either of my parents.

So, let’s say this another way to be clear – I only see these matches on the WGS test, and none of the other tests.

How Many People Match Me on Only One Test?

Ok, so how many people match me on ONLY one test?

FTDNA 2016 Only Matches MH 2019 Only Matches MH 2024 Only Matches MH WGS Only Matches
44 (10.1%) 3 (0.7%) 3 (0.7%) 16 (3.7%)
  • 44 people match me ONLY on the FamilyTreeDNA 2016 uploaded test.
  • 3 people match me ONLY on the MyHeritage 2019 and 2024 tests, respectively, but not the same three people
  • 16 people match me ONLY on the MyHeritage WGS test

Extrapolating these percentages to the rest of my matches suggests the following number of people would match ONLY on this test in the entire match list for each test.

FTDNA 2016 MH Health 2019 MH 2024 MH WGS
Total Matches 19,722 17,179 17,767 17,676
Extrapolated Matches on Only This Test 10.1% or 1992 matches 0.7% or 120 matches 0.7% or 124 matches 3.7% or 654 matches

 How Many People DON’T Match Me on a Specific Test?

Now, how many people DON’T match me on a specific test?

No FTDNA Match No MH 2019 Match No MH 2024 Match No MH WGS Match
36 (8.3%) 117 (27%) 126 (30%) 96 (22%)
  • 36 people don’t match me on the FamilyTreeDNA test, but do match me on at least one other test at MyHeritage
  • 117 people don’t match on the 2019 MyHeritage test, but do match on at least one other test at MyHeritage
  • 126 people don’t match on the 2024 MyHeritage test, but do match on at least one other test at MyHeritage
  • 96 people don’t match me on the WGS test, but do match me on at least one other test at MyHeritage

Extrapolating these percentages provides an extrapolated number of matches that I don’t match on any specific test, but that I do match on at least one other test.

FTDNA 2016 MH Health 2019 MH 2024 MH WGS
Total Matches 19,722 17,179 17,767 17,676
Extrapolated # That Don’t Match on This Test 8.3% or 1637 matches 27% or 4638 matches 39% or 5330 matches 22% or 3,889 matches

How Many Match Me On All Tests

  • 195 matches, or 44.9%, nearly half of my matches, match on all four tests at some level.
  • Out of those, 68, or 15.7% of the total number of matches match me at exactly the same cM level across all 4 tests. That’s pretty remarkable.

The Largest Differences Between Tests

Another question might be how large the difference is between the various matches.

I calculated the largest differences between the highest and lowest match values between the four tests, and placed that value in column G. This means that I subtracted the lowest value of the four tests on this particular match, from the highest value.

In the first row, that means I subtracted 0, the MH 2019 test value, from 75, the WGS test value. The difference between the lowest and highest values is 75 cMs.

Next, I sorted, highest to lowest in column G, so the largest difference is displayed at the top.

I was VERY surprised to see a difference as high as 75 cM, so let’s evaluate the results where the difference is 50 cM or greater. Thirteen matches fall into this category.

  • Entry 168 – The largest difference at 75 cM. This person matches me at 70, 74 and 75 cM, but not at all on the 2019 test, which caused me to go back and check again. Did I spell the name correctly? Yes, I did. We don’t know why I don’t match this person on the 2019 test, but the other matching cM values are very close so they look to be correct.
  • Entry 183 – I match this person on both the FamilyTreeDNA uploaded test at 71 cMs, and the WGS test at 35 cMs, around half as much on the WGS test as the FamilyTreeDNA test. I don’t match them at all on either the MyHeritage 2019 or 2024 kits. I have no explanation.
  • Entry 186 – Like entry 168, we match on three of four tests at 62, 63 and 67 cMs, with the non-matching test being the 2019 test. I would presume that this match is accurate as well.
  • Entry 191 – This one is interesting because I match this person on the FamilyTreeDNA uploaded test at 64 cMs, but none of the other tests.
  • Entry 192 – We match at 57 cMs on both the WGS and the 2024 tests, but not the 2019 test, where we don’t match at all. The match on the FamilyTreeDNA test is 11 cMs lower, at 46 cMs.
  • Entry 228 – This person is my half 1C1R, and I match them on all the tests, of course. However, there’s a 53 cM difference between the WGS and the FamilyTreeDNA uploaded test. In a relationship this close, 53 cM is a small percentage and won’t affect matching, but it’s not an insignificant amount of DNA.
  • Entries 233, 247, 248 and 283 – I match these people ONLY on the WGS test at 50, 52 and 53 cMs, so if I hadn’t taken the WGS test, I wouldn’t match them at all. Without additional research, we can’t tell if this is a legitimate match or not, but 50-53 cM would be a lot to be imputed or to be identical by chance. These people also match one of my parents’ tests, which eliminates the identical by chance possibility, meaning some of the DNA matches my mother and some matches my father – at least on my end. We can’t determine if this match is identical by chance on their side. I’ve never seen a 50+ cM segment (or even close) that is identical by chance, though.
  • Entry 249 – Matches on the FamilyTreeDNA test at 15 cM, and the MyHeritage 2024 test at 52 cM, but not the others.
  • Entry 250 – Matches at 51 cM on the FamilyTreeDNA test, but not on any of the MyHeritage tests.
  • Entry 279 – Matches only on the MyHeritage 2019 test at 50 cM.

Difference Range

Next, let’s review the entire range of differences, meaning the largest matching difference for any one person across all four tests, by group. I’m including all 434 here so you can judge for yourself.

  • 50-75 cM difference – 13 matches analyzed above

  • 45-49 cM difference – 22 matches

  • 40-44 cM difference – 11 matches

  • 35-39 cM difference – 9 matches

  • 30-34 cM difference – 10 matches

  • 25-29 cM difference – 12 matches

  • 20-24 cM difference – 26 matches

  • 16-19 cM difference – 28 matches

  • 13-15 cM difference – 29 matches

  • 9-12 cM difference – 29 matches

  • 8 cM difference – 78 matches

The 8 cM difference has the most of any value or category because this is the lowest level of matching at MyHeritage. Many tests have a minimum level match on a test or tests, and no others.

  • 6-7 cM match difference – 41 matches

The match differences at 5 cM and below are inconsequential. 57 matches fall into this category.

Commentary

One of the indicators of a valid match is if a parent has tested and also matches,

Of these 434 matches, 35 match neither parent, and most of those are at the smallest match level, meaning 8 cM. Of all the match amounts, that would be the least reliable, and most likely to be a false positive match, or identical by chance.

However, that’s not universally the case. Some WGS results match people at significantly higher levels, but don’t match parents. Two WGS matches match people at 47 and 49 cMs, respectively, and not on any of the other tests. Those two WGS matches don’t match either parent.

After reviewing all 434 selected matches, it appears that both the FamilyTreeDNA 2016 test, and the WGS test produce the most consistent and reliable results of the four tests.

44 people, or 10%, match on BOTH the WGS and the FTDNA tests, but neither of the other two tests. A total of 13.8% match EITHER the FTDNA test OR the WGS test, but not the others.

Conclusions

I think we can draw several conclusions from this comparison.

First, let’s evaluate the number of matches. Looking at the differences between the total number of matches between the various tests, especially the three MyHeritage tests, over time, isn’t that great. That’s exactly why you can’t depend on these numbers as an accurate comparison.

FTDNA 2016 MH Health 2019 MH 2024 MH WGS
Total Matches 19,722 17,179 17,767 17,676

There are only a few hundred differences between the three MyHeritage tests, and about 2000 between the FamilyTreeDNA test uploaded in 2016 and the various MyHeritage tests. That’s a substantial difference.

The difference number of matches between tests may seem irrelevant, especially the MyHeritage tests, until you realize that those who match AREN’T ALL THE SAME PEOPLE. In other words, comparing the MyHeritage 2024 test with the WGS test only shows a difference of 91 matches. This DOES NOT mean that the MyHeritage 2024 test and the WGS test have 17,676 of the same people who match both tests, and that the 2024 test simply has 91 more matches than the WGS test.

As we’ve seen, many people who appear on any one match list don’t appear on other match lists.

Our analysis showed that 44.9% of my 434 matches compared appear on all match lists, which means that more than half of my matches appear on one or more match lists, and not the others. Therefore, just comparing the number of matches isn’t really relevant. You need to compare the people included on all the different tests, which is why I created my spreadsheet and included people from a wide variety of sources.

3.7% of my matches on the WGS test were not on any other test, which extrapolates to approximately 654 of my total WGS matches that I wouldn’t receive any other way.

I care a great deal about those matches, especially since at least some appear to be high value.

Yes, I absolutely, positively want those matches, especially when you consider that some of the matching differences are as high as 75 cM. A 75 cM match can be in the second, third or fourth cousin range.

Realistically, they may or may not be valid or useful matches – but if I don’t have the opportunity to compare them, I’ll never know.

Should You Purchase the WGS Test If You’ve Already Tested?

So, now for the question you’re surely asking yourself.

Truthfully, when I ordered my test back in December, I was ambivalent. I only ordered it to do this comparison for my blog readers – and I really dislike spending money on something that I don’t think will benefit me.

Note the words “don’t think.”

I’ve changed my mind, for several reasons, and I’m glad I ordered the test.

The thing that changed my mind was that I received a nontrivial amount of matches on the WGS test that I didn’t receive on any of the others – even if some of them turn out to be identical by chance.

Since we can’t go back in time and take the earlier tests, and MyHeritage no longer accepts uploads from other vendors, our decision now is whether or not we should take the new WGS test, or not, especially if we already have a DNA test at MyHeritage.

If you’re a new tester, by all means, test at all four of the main vendors. DNA matching is the best thing since sliced bread.

However, the people I’m really speaking to here are those who already have a test of some sort at MyHeritage.

Here’s the bottom line:

  • You will receive WGS matches that you didn’t receive on your other test – and vice versa, so don’t delete your older test at MyHeritage
  • Some of those new WGS matches may well be high-value matches – as was illustrated in the “differences” I discovered.
  • Given the differences in who is included in the match list, your TOFR will be different too – perhaps leading to a brick wall breakthrough. I have two that I’m just itching to solve.
  • Use matches, shared matches and TOFR from ALL of your tests at MyHeritage.

My Biggest Regret

As Ran Snir said, new features and developments at MyHeritage will be based on the WGS test. We don’t know what those developments might be, or when they will become available. But it’s very clear that while testers on the older testing platforms will receive as much as MyHeritage can give them, the MyHeritage DNA future is being build on the WGS platform. I want to be there and benefit from new discoveries.

My biggest regret is that my parents aren’t around to take the new WGS test – and neither are several other family members.

Of the 15 family members whose tests I manage at MyHeritage, 9 are deceased, and I think that four more are as well. Two others are now quite elderly and are no longer able to consent or retest.

Your closest family members are your DNA anchors, identifying lineages and pointing you in specific directions, guiding your research.

The very best thing you can do for your genetic genealogy is to test your grandparents if they are living, and your parents. If they aren’t available, test your closest relatives such as grandparents, siblings, aunts, uncles and first cousins.

Preparing for the Future

So, here’s my advice:

  • Take the WGS test yourself in order to glean as much information as possible and to benefit from future developments.
  • Retest any relatives whose tests you manage on the WGS platform, if possible.
  • Test your close family members and anyone you know whose DNA test could help you identify ancestral lineages.

Why is testing your relatives important?

Close relatives will carry some of the DNA from your mutual ancestors that you don’t.

Having the known DNA of your ancestors means that you can evaluate and analyze the trees of the entire group of people who match those identified DNA segments to see if you can break down an upstream brick wall.

I’ve been successful doing this for some time – and am in the process again by combining DNA matches and traditional records research.

Coupon Code for $20 DNA Test

MyHeritage has been kind enough to provide a limited-time coupon code (RobertaFeb26) for my readers which DROPS YOUR PRICE for the DNA test to $20 through February 28th at midnight.

This is the absolute lowest price I’ve ever seen for a DNA test.

You’ll receive the following features that are included with every test:

  • Ethnicity and ethnicity map
  • DNA matches and the ability to contact them
  • Shared ancestral surnames
  • Chromosome browser
  • cM Explainer

In addition, with this code you’ll receive both Shared DNA Matches and Shared Ancestral Places that usually require a subscription.

Normally, a subscription is required to access:

  • Trees of DNA matches
  • Shared DNA Matches (free now with the coupon code)
  • Shared ancestral places (free now with the coupon code)
  • AutoClusters
  • Theory of Family Relativity (TOFR)

If you’re interested in trying a subscription, click here to purchase a MyHeritage subscription with a free trial.

Here’s the link to purchase the DNA test, and here’s the coupon code to enter at checkout: RobertaFeb26

And yes, absolutely feel free to share the coupon code with your family, friends, and anyone else who might benefit.

Let me know how your results compare when you receive them.

_____________________________________________________________

Share the Love!

You’re always welcome to forward articles or links to friends and share on social media.

Subscribe!

If you haven’t already subscribed, it’s free. You’ll receive an e-mail whenever I publish by clicking the “follow” button at the top of the main blog page, here.

Help Keep This Blog Free

I receive a small commission when you click a vendor link in my articles and purchase that item. This does NOT increase your price but helps me keep the lights on and this informational blog free for everyone. Please click on the affiliate links in the articles or to the vendors below if you are purchasing products or DNA testing.

Thank you so much.

DNA Purchases and Free Uploads

Genealogy Products and Services

My Books

Genealogy Books

Genealogy Research

AutoKinship by Genetic Affairs Builds Family Trees from Your Matches at FamilyTreeDNA, and More

Genetic Affairs released a new AutoKinship tool designed for FamilyTreeDNA’s autosomal Family Finder matches, which also incorporates information from other sources. I must have fallen asleep at the wheel, because AutoKinship has been available for more than six months now.

I’ve been testing this tool with my matches, and it’s an immense help to those of us trying to untangle complicated family relationships using DNA evidence. I don’t know about you, but I have a long list of brick well where I could use help!

How to Use This Guide

This article is long and there are many steps involved – but it’s well worth it at the end.

My suggestion for using this article effectively is to read it through, at least once, to see what you’re going to be doing, and why.

Then, after you get things set up at Genetic Affairs, and any files you want to include, come back and use this article as a step-by-step guide to navigate these new tools.

Here’s the bottom line. The Genetic Affairs tools use matches, along with shared and bucketed matches at FamilyTreeDNA, plus their archived trees, in addition to external GEDCOM files and other information that you can provide in order to create customized, focused clusters and potential family trees for your clustered matches.

These tools combine DNA matching with internal and external trees for the composite best of both types of information.

So grab your favorite drink and let’s get started.

FamilyTreeDNA

AutoKinship works in conjunction with FamilyTreeDNA’s tools, such as Shared Matching, the Matrix tool, and Family Matching, also known as bucketing, which assigns parental sides to your matches using linked matches.

Linked matches are your matches whose relationship to you is known. If you haven’t already, link them to their profile card on your tree by clicking on “Link on Family Tree.” This allows FamilyTreeDNA, by using triangulation, to “bucket” your matches either maternally or paternally – meaning if they are related to you on your maternal side, paternal side, or both.

In my cousin Patricia’s case, the little pink icon by her profile picture shows that she has been bucketed maternally. That occurred when I linked my mother’s DNA to my tree because Patricia matches us both, plus other linked maternal cousins, on the same segments. For bucketing to occur, you don’t have to do anything except link known relatives to their proper place in your tree. FamilyTreeDNA does the rest by assigning your matches either maternally or paternally if they match on common segments.

Upload DNA Files to FamilyTreeDNA from Other Vendors

If you have not taken the Family Finder test at FamilyTreeDNA or uploaded your DNA file from 23andMe (Dec 2010 to present), Ancestry (May 2012 to present), or MyHeritage (March 2019 to May 7, 2025) to FamilyTreeDNA, you should do so now to take advantage of their tools, plus AutoKinship at Genetic Affairs.

What is AutoKinship and Why is it Different?

AutoKinship takes traditional clustering and kicks it up several notches. Instead of just showing you which matches cluster together, it actually attempts to build family trees based on the shared DNA amounts between your matches.

AutoKinship looks at how much DNA your matches share with you, and with each other, and uses that information to predict their relationships. Then AutoKinship builds potential family trees showing how everyone might connect. Additionally, you get to provide input in the process.

The timing couldn’t be better, especially since FamilyTreeDNA recently launched their updated Matrix tool, showing how your matches are related to each other. I wrote about that, here.

Two Steps

There are two primary steps in the AutoKinship process that build on each other. However, within these steps, there are many stepping-stones, so I’ve documented each one.

We’re going to use these tools, one at a time, in order.

I suggest that you join the Genetic Affairs User Group on Facebook for additional support and information.

Using AutoKinship with FamilyTreeDNA

The AutoKinship functionality for FamilyTreeDNA provides an automated approach using both AutoCluster and AutoKinship, together, then AutoLineage, where you can refine the information in a number of ways.

🔹 Step 1: Automated AutoKinship via Genetic Affairs

The first step involves running the AutoKinship tool directly from the Genetic Affairs members’ site. This process is fully automated:

  • It starts with the FamilyTreeDNA AutoCluster option, which groups DNA matches into shared clusters based on their connections to each other.
  • AutoKinship is then automatically launched on each cluster, adding the DNA tester and generating relationship hypotheses among the group.
  • Several family tree models are produced, showing how the matches and the tester could be connected based on shared DNA and cluster structure.

This step is ideal for getting quick insights into how groups of matches may relate.

🔹 Step 2: Refined Clustering & Relationship Analysis Using AutoLineage

After the automated run, downloadable files for AutoLineage are generated. These files allow you to re-import the match, shared matches, and tree data into the AutoLineage web application for further analysis.

This second step offers greater control and customization:

  • You can redo the clustering, optionally tweaking parameters to fine-tune how matches are grouped.
  • You can redo the common ancestor analysis, optionally tweaking parameters to fine-tune the discovery of MRCAs
  • The AutoKinship tool within AutoLineage becomes available again, this time with additional functionality:
    • Define known relationships between matches, such as parent-child or cousin relationships
    • Define generational information, for instance, if you know certain matches are not on the same generational level
    • Integrate MRCA (Most Recent Common Ancestor) data from reconstructed trees, e.g., from the Find Common Ancestors module.

This enhanced phase is especially useful for integrating genealogical trees for targeted clusters.

By combining both steps, automated clustering with AutoKinship, and manual refinement with known or tree-derived relationships using AutoLineage – you can leverage your FamilyTreeDNA data for in-depth relationship exploration.

Let’s Take AutoKinship for a Spin

As always, I’ll walk you through this process step by step, using my own DNA results as an example.

Getting Started

First things first – you’ll need to be a member of Genetic Affairs, so sign up for their free membership, here. Genetic Affairs’ customers purchase “credits” to spend on various features and reports, but you receive 200 free to start.

The automated AutoKinship analysis available on the Genetic Affairs website can be run using credits from the free tier – perfect for exploring the tool without any commitment. This allows users to generate relationship trees for FamilyTreeDNA clusters right away.

To access the more advanced features in the AutoLineage desktop application—including refined clustering, manual relationship input, and integration of MRCA data from reconstructed trees – you’ll need an active subscription.

To get started, sign in to the Genetic Affairs member site, here.

Let’s walk through the process step by step.

We’ll begin by registering a FamilyTreeDNA profile at Genetic Affairs. Click on “Register a new website” to get started.

FamilyTreeDNA account passwords are not stored at Genetic Affairs.

After clicking “Register profile,” you’ll see a message asking you to double-check the credentials for the kit you’re about to use. This is also a good time to log in to your FamilyTreeDNA account directly to make sure there are no pending actions — such as enabling two-factor authentication or accepting updated terms of service.

Once you click “I understand, continue,” you’ll see a list of all registered FamilyTreeDNA profiles at Genetic Affairs.

Locate the kit you want to analyze and click the blue “Start analysis” button.
This opens a guided wizard that walks you through each step of the setup.

First, select AutoKinship and click “Next.”

You’ll then be asked to define several thresholds:

  • Minimum and maximum shared cM
  • Minimum size of the largest segment
  • Minimum cluster size

A quick word of caution here: selecting a very low minimum cM value may actually reduce the number of usable matches. That’s because the system must download shared match data until it either reaches that threshold, or a preset timer expires, which can limit how much data is downloaded. When in doubt, start conservatively. You can always rerun the analysis later and change the parameters. Unfortunately, there’s no way to simoly “get everything” in one run which is, of course, what everyone would do.

Click “Next” to continue.

This section determines which matches will be included in the analysis.
For your first run, I recommend using the top matches within the selected range. This provides a strong foundation and usually produces the clearest results.

Later, once you’re more familiar with the output, you may want to experiment by analyzing only the shared matches of a specific person or group. For now, keep it simple and click “Next.”

Here, you’ll enter your FamilyTreeDNA password (twice) so the system can retrieve the required data.

If you use two-factor authentication, you can enter the 2FA code here, as well. To do that, log in to your FamilyTreeDNA account, retrieve the code from your email, and paste it into the wizard.

Then click “Next.”

You’ll now see a summary of all the settings you’ve chosen. Take a moment to review everything. When you’re ready, click “Perform analysis” in the bottom right corner.

At this point, the Genetic Affairs servers take over and begin processing your data.

The Results Arrive

When your report is ready, you’ll receive an email with a download link. You can also access it through the notification panel in the top right corner of the Genetic Affairs site.

Downloading the report will result in a zipped file. Save it in a location on your computer where you can find it.

Critical Step

This step is critical and will save you a great deal of frustration: If you’re using a PC, you MUST extract or unzip the files before you can properly use them. I can’t tell you how many people skip this step and then wonder why they’re receiving error messages. Ask me how I know!

This is your zipped file.

If you try to open the HTML file while it’s still zipped, it might appear to work at first, but when you click on any links within the file, you’ll receive an error.

If this happens to you, close everything, right-click on that yellow zipped folder, select “extract all,” and then try again.

Now you’re set up, so on to the fun part – viewing the results.

Exploring Your Results

Once you have everything properly extracted and open the HTML file, you’ll watch your AutoCluster literally fly into place on your screen. I love this part. It’s like watching my family fly into place. I wish the actual genealogy research was this easy.
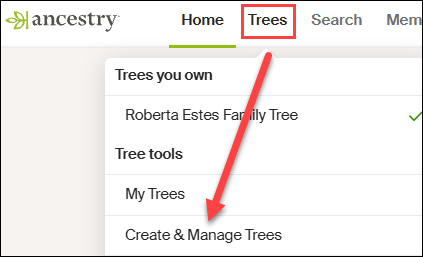
The new Genetic Affairs reports include significantly more information than previous versions.

You can change what’s displayed using the dropdown menu.

By default, you’ll see the shared cM amounts between your matches, but you can change this to show paternal or maternal information if you’ve identified those lineages by linking your matches.

In my case, my maternal line has fewer matches because my mother’s ancestry includes both recent Dutch and German immigrants, so the majority of my high cM matches are US-centric on my father’s side. My father’s ancestors have been in this country since colonial times, and a lot of testers in the US are looking back to the old country for their origins.

Therefore, in my first several clusters, I see squares with the symbol P, indicating they are paternal matches – designated as such through linked family matches, aka bucketing.

You can see the faint Ps inside the orange cells.

Here’s a close-up so you can see the “P” for paternal. If you haven’t linked your matches, you won’t have bucketed matches. Your Genetic Affairs results don’t require bucketing – it’s just a really beneficial feature.

You can change your AutoCluster settings in several ways. I tend to start with the defaults and then modify from there.

Genetic Affairs functions based on the amount of server time a particular tool takes, so it’s not possible to just “run everything,” or trust me, I would.

The Common Ancestor Magic

In your report, scroll down several sections, and you’ll find Common Ancestors – my favorite feature.

This section shows you the common ancestors that have been identified between your matches’ trees.

Looking at the Common Ancestors cluster report, you can click on three things for each cluster:

  • FamilyTreeDNA Trees of Cluster #
  • Common Ancestors of Cluster #
  • Common Locations of Cluster #

Let’s examine the reconstructed trees based on the common ancestor analysis. The first cluster shows some of my close DNA matches that are descendants of my Vannoy line.

You can see that there are six testers, in addition to me, who descend from Joel Vannoy.

Next, scroll down to the AutoKinship section of your report.

The AutoKinship Analysis

The real treasure lies in the AutoKinship analysis, which is presented in a small table on the main HTML page. When you click on the AutoKinship results for any cluster, you’ll see reconstructed trees based on the shared DNA amounts between matches, meaning between you and each of them, and between each other.

You can see that I have 10 reports available based on the cluster numbers indicated.

I clicked on Cluster 1, which shows some of my close DNA matches who are Vannoy line descendants. This includes testers both with and without trees.

Since the AutoKinship algorithm doesn’t have access to age information, it sometimes struggles with generational differences – but the relationship predictions are still remarkably useful.

Alternative trees are also provided, giving you multiple hypotheses to investigate.

Some matches may not be integrated because of incompatible relationships.

The Next Step with AutoLineage – Adding Genealogical Trees to the Mix

We’ve seen AutoTree and AutoKinship. The new upgraded AutoLineage adds genealogical tree information to genetic information by allowing the user to:

  • Import other trees
  • Integrate most recent common ancestors (MRCAs) in AutoKinship trees
  • Set known relationships
  • Provide generational information.

AutoLineage, Genetic Affairs’ online clustering and tree-building tool, has been around for several years but was recently upgraded to create trees based on shared DNA and incorporate genealogical evidence.

This is where the proverbial rubber meets the road.

Setting Up AutoLineage

Return to the home page at Genetic Affairs and select AutoLineage.

If you’re new to this tool, you’ll see a simplified workflow on the start page that walks you through the process.

First, create a profile representing the DNA test taker – in my case, that’s me.

After creating the profile, you’ll be redirected to the landing page of the profile. From there, you can register DNA tests linked to the profile. From the home page, you can see the different profiles.

You’ll register a new FamilyTreeDNA test specifically for each user whose kit you manage and who took a test.

FamilyTreeDNA is the only DNA testing company for which Genetic Affairs runs automated analyses on their site.

Additionally, you can:

Importing the Data

After registering a FamilyTreeDNA test, you are redirected to the overview of this DNA page, where matches are imported.

Click on “Import matches” and select the CSV file from Genetic Affairs. Here’s where that AutoKinship report we generated earlier comes in handy. The unzipped report contains match and shared match information that we can import directly into AutoLineage.

Navigate to the gephi folder in your report and select the nodes.csv file to import your matches.

After importing the matches, a short dialog shows how many matches were imported.

After closing the dialog box, the DNA matches pane is opened.

You’ll see your DNA matches that were downloaded.

Next, import the shared match information from the edges.csv file in the same gephi folder.

Once both data sets are imported, you’ll see that the ICW (In Common With) column has populated, showing how many shared matches are available for each DNA match.

Clustering in AutoLineage

Now, with the shared match data loaded, you can perform your own clustering analysis.

The wizard allows you to set parameters for which matches to include based on:

  • The amount of shared cMs
  • Weighted or unweighted clustering
  • How much DNA is shared between shared matches

You can also define the cluster characteristics, from sparse to very dense clusters.

Last, you can select the coloring scheme. After setting the parameters, click on “Start Clustering,” at bottom right.

After clustering is finished, the clustering chart is displayed. It looks fairly similar to the ones obtained automatically from Genetic Affairs, but with some differences.

The first thing I noticed is that the large orange cluster 1 in the automated clustering is now mostly represented by the purple cluster 4.

Let’s zoom in on this cluster. By looking more closely at the numbers contained in each cluster, you can already make an estimated guess about the richness in relationship information for cluster members. This cluster has lots of close relationships. Clusters whose matches only share a small amount of DNA with each other are not the best candidates for an AutoKinship analysis because they most likely share a distant common ancestor. Unless, of course, it’s a distant ancestor you’re searching for. (Hello brick wall.)

Adding and Importing Tree Information

Now that we have the new clusters, we could continue to directly run the tree reconstruction on these clusters using the shared DNA information, but let’s wait  since we want to include the tree information as well to guide this process.

To use common ancestors, we need to import the available trees that are linked to the DNA matches. Luckily, just like (shared) match information, the tree information is provided with the automated analysis as well. Let’s import the data.

First, navigate to the tree management page. As you can see, no trees have been created or imported. Let’s start the wizard by clicking on the “Import Trees” button.

An “Import tree” wizard pops up, providing different ways to import tree information. It’s also possible to import GEDCOM files or tree data from other resources, but for now, I’m only using the archived trees at FamilyTreeDNA.

Click on the last option and select the files.

Navigate to the matches folder and select the HTML files contained in the folder.

Each file represents a DNA match report, some of which have a tree associated with them.

After importing the trees, they are automatically associated with the concerned DNA matches (using the unique identifier present in each file name). The tree overview page shows which tree is linked to a profile or DNA test, and the amount of DNA shared with the linked DNA match.

If you have created trees for your matches based on your own research (like quick and dirty trees), now is the time to import these using the “Import Tree” wizard again. This is a wonderful feature, because it means you’re not entirely dependant on your match having uploaded a tree themselves.

If you don’t import trees from GEDCOMs, you don’t need the linking wizard.

Click on the “Import Tree” wizard and select the GEDCOM option.

Now that we have imported additional trees, we need to associate them with DNA matches.

You can use a wizard to link the unlinked trees to the DNA matches, or link them from each DNA match. The wizard will try to guestimate, based on the content of the tree file name, which DNA match could be associated with the tree. Change the search criteria if it does not provide the correct results.

TIP: Save the GEDCOM files with the name of the linked DNA match as well the shared cM, which speeds up the importing process

Don’t forget to import your own tree. I imported my GEDCOM file from my computer genealogy software and associated it with my profile so it’s included in the common ancestor identification. You can easily upload your GEDCOM from your computer software, or download your tree from either Ancestry or MyHeritage to upload here.

Visit the profile, and select the tree pane. The tree pane only shows a single individual and allows you to add ancestors to it manually. To associate that individual with an existing tree, click on “Link to Existing Tree”.

A wizard will be displayed, which shows all available trees on the left side. Sort by clicking on the “Created” column to display the most recent trees.

Next, you need to select the root person.

I selected my tree.

Next, the right side of the wizard fills with the people in the selected tree. Select the root person, which is me, and click on “Save” in the lower right corner.

Finding Common Ancestors

Now that we have associated a tree with the profile and imported trees for the FamilyTreeDNA matches, it’s time to locate some common ancestors. Fingers crossed!

Go back to the profile and select the profile overview. Scroll down to the “Find common ancestors” section and click on the “Find common ancestors” button.

The “common ancestors” wizard shows trees that are associated with this profile in the table on the left and provides information about the different steps on the right. You can change the settings to make the search more restrictive or more relaxed.

After running the common ancestor identification, a dialog shows the number of trees and tree persons that were used, and the number of common ancestors that were identified.

After the analysis runs, you’ll be able to view all reconstructed trees or filter them based on common ancestors, trees, or linked DNA matches.

Common ancestors, not surprisingly, often align closely with what the automated analysis discovered.

All six testers are now shown descending from our common ancestor, in the approximate location where they will fit in our common tree.

But we aren’t quite finished yet.

The Final AutoKinship Analysis

Finally, we’ve arrived. The earlier steps were necessary to pave the way.

We have the common ancestors and clusters, and it’s time to go back to the clusters to begin the reconstruction of trees using trees combined with DNA.

Click on the profile and go to the clustering results pane. Select the 1x view, which will show the clustering chart.

Now select the matches pane that shows the different matches that are contained in each cluster. Scroll down until you reach your cluster of interest, which is four for me.

After clicking on any cluster, you’ll be redirected to a cluster view with only the information for that particular cluster.

Let’s view purple cluster 4, which looks fairly dense, with only a couple of empty cells, indicating that these shared matches with white cells did not share (enough) DNA with each other to be included in the cluster. Now select the matches pane in the dashboard at the top of this cluster, which displays the matches linked to this specific cluster. As you can see, a button is now available that allows us to run the AutoKinship analysis. Click on the button.

Single cluster matches are displayed.

Now back to the wizard.

The wizard provides several important parameters:

  • Maximum number of generations between DNA matches
  • Number of trees to analyze in each iteration
  • Final number of trees to keep
  • Whether to include known relationships and/or MRCA (Most Recent Common Ancestor) relationships

In this example, MRCA relationships were found because we performed the common ancestor identification that resulted in common ancestors between the matches of this cluster.

If you know specific relationships between matches, you can set those manually. Sometimes you might not know the exact relationship, but if you can estimate that a match is one or more generations older or younger than yourself, you can set that too.

In addition to setting the relationship between the test taker (indicated in green in the table) and the DNA matches, it’s also possible to set the relationship between shared matches, if known.

The Hybrid Results

After the analysis has finished, an overview of the identified trees is presented.

The final result is a blended tree where DNA evidence fills in the blanks for matches who haven’t uploaded trees, or you haven’t provided a tree, and known genealogy supports the structure where it exists. This hybrid approach gives us the best of both worlds – the precision of documented genealogy combined with the discovery power of DNA analysis.

I particularly like this approach, because when I identify how a DNA match is related to me from any vendor, I enter their lineage in my desktop genealogy software. Therefore, using that GEDCOM file is the most complete source of my identified relatives.

Testers 1-6 were shown using the regular AutoTree, without the integrated tree, but an additional 11 matches were placed for consideration using all available tools.

I was using this as an experiment because I know how most people in this cluster are related, and those are all placed accurately. There is one person, located on the branch between 1 and 5, who I had no idea how they fit into this puzzle. Now, at least I know where to look.

I can’t imagine trying to do all of this manually.

Why This Matters

For those of us dealing with unknown parent or grandparent situations, poorly documented lines, non-existent trees, or just plain stubborn brick walls, this combination of tools is nothing short of amazing. You can now explore relationship hypotheses even when traditional documentation is scarce.

The reconstructed trees show how common ancestor information provides the template, while the AutoLineage tool fills gaps using shared DNA information. The updated AutoLineage is the genealogical assistant that never gets tired and can deal with relationship possibilities much more effectively than traditional hand-based methods.

In Summary

If you haven’t explored Genetic Affairs recently, give it a look. The integration between AutoKinship and AutoLineage represents a significant step forward in DNA analysis.

While AutoKinship offers valuable insights on its own, its full potential is truly unlocked when you export the data into AutoLineage. The combination creates a comprehensive analysis that was previously impossible.

For researchers dealing with complex family relationships or challenging genealogical puzzles, this hybrid approach that combines matches at FamilyTreeDNA with DNA evidence and genealogical trees could be the key to breaking through stubborn brick walls that nothing else has budged.

Last but not least, I suggest reading Dr. Patricia Coleman’s blog articles about these tools and her methodologies here and here. Patricia works extensively with these tools, and I often recommend her for private autosomal research consultations. Patricia’s 2026 RootsTech Session, DNA Case Study: Finding an 1877 Birth Father with Genetic Affairs, BanyanDNA, and No Birth Record, details her work solving a long-standing problem for my cousin in the Speaks family.

_____________________________________________________________

Share the Love!

You’re always welcome to forward articles or links to friends and share on social media.

Subscribe!

If you haven’t already subscribed, it’s free. You’ll receive an e-mail whenever I publish by clicking the “follow” button at the top of the main blog page, here.

Help Keep This Blog Free

I receive a small commission when you click a vendor link in my articles and purchase that item. This does NOT increase your price but helps me keep the lights on and this informational blog free for everyone. Please click on the affiliate links in the articles or to the vendors below if you are purchasing products or DNA testing.

Thank you so much.

DNA Purchases and Free Uploads

Genealogy Products and Services

My Books

Genealogy Books

Genealogy Research

Y-DNA Results at 20 Years: Answers, Lessons, Methods, and Workarounds

Our goal as genealogists is always to learn what we don’t know and reveal anything we should know.

I’m going to share the evolution of four tests, purchased exactly twenty years ago. I haven’t cherry-picked these, so you’re getting the raw story. Successes, challenges and regrets, plus a few hacks to help you out when you’ve hit a roadblock.

I’m also sharing how I work around some issues – like tests that haven’t been (and can’t be) upgraded to Big Y tests.

DNA testing has come a long way from an infant science two decades ago, when we were tentatively establishing a new industry – one that today has evolved into a staple for serious genealogists.

On New Year’s Eve, 2005, exactly 20 years ago, I was doing the same thing I was doing at midnight in 2025 – genealogy.

That was long before the days of social media and chat groups, so some of us geeky types were discussing our genealogy research on the now-obsoleted RootsWeb e-mail list.
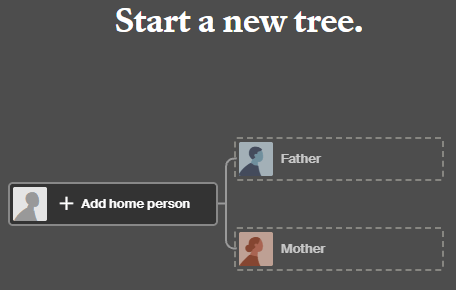
I Was Planning for 2006 Travel

I realized that I was going to be traveling during 2006 and would be asking several men to take a Y-DNA test, so I should purchase several kits while they were still on sale.

Then I got a bit giddy when I realized that I could actually celebrate the New Year by making those purchases right at midnight.

And I did too – I hit it right on the dot.

I mean, for a genealogist, what better way to celebrate? Right?

What I didn’t know is that, quite by accident, I managed to score kit 50,000. That seemed like such a milestone!

And now, I can’t believe it’s been 20 years. How is that even possible?

After I went to bed in the wee hours of January 1, 2026, I decided I needed to check in on the kits I purchased on that fateful New Year’s Eve, 2005, and see how they are doing. What were my goals, aspirations and expectations? Did we accomplish them then? Have we now?

What has happened in the past twenty years?

Let’s take a look, beginning with kit 50,000.

Kit 50,000 – Mr. Miller

Mr. Miller is my mother’s second cousin, so the perfect person to represent our Miller line.

Goals and Questions:

  • Do we descend from Johann Michael Miller born in 1692 in Germany? At that time, we did not know his birth location, and only knew that the line was German. Later research would add two additional generations and place his grandfather, Heinsman Mueller in Schwarzenmatt, Switzerland before 1655.
  • Does the Elder Jacob Miller (born about 1710 in Germany), a Brethren minister, match the Johann Michael Miller line? They were both Brethren, clearly knew each other, and were found in some of the same locations. The answer is conclusively no; the lineages are not the same based on both STR and Big Y-700 tests.

2005 – 12-marker test – $99

  • Initial 2006 haplogroup – R-M269 – about 6,500 years old
  • 2025 haplogroup – R-BY56132 – about 350 years old, obtained via DNA match to another Miller tester

That a HUGE difference!

2006 matches – no Y-DNA matches.

Remember, this was early, with less than 50,000 results in the database, compared to just under 700,000 SNP-confirmed testers today, not to mention probably double many more STR-only testers.

Haplogroups for STR testers are predicted based on marker values and are not SNP tested or confirmed. The Big Y tests, SNP tests and SNP packs which are no longer available, and haplogroups assigned through Family Finder are SNP confirmed.

2025 matches – 2 (yes two) 12-marker matches, both Millers. At 25 markers, he has 7 matches, all Millers.

I created the Miller-Brethren Project in September 2006 for any Miller line that was of the Brethren faith, hoping to differentiate between families with the same names in the same place.

2009 – upgraded to 67 markers – $148

In 2009, I upgraded Mr. Miller to 67 markers and recruited two other Miller males from our believed line. They all matched at 25 markers and above, confirming the lineage to our ancestor, Johann Michael Miller/Mueller. Whew! That one was close, because there was a great deal of consternation and confusion about these lineages.

2011 – added Family Finder – $289

Mr. Miller’s haplogroup today, confirmed by Family Finder, is still same as his predicted R-M269 from his STR results. Unfortunately, the kit has never been upgraded to the Big Y test, and I desperately want our personal lineage haplogroup. However, all is not lost because he matches several males from the same lineage who have been assigned to haplogroup R-BY56132 through the Big Y-700 test.

Every haplogroup is publicly viewable in Discover, but testers can see additional information and features when they click through to Discover from their own account – including the Match Time Tree, Globetrekker™, and more Ancient and Notable DNA Connections.

Discover provides an informative Haplogroup Story, an overview before viewing the dozen reports available in the left sidebar about that haplogroup’s history and lineage. You can take a look, here.

From Discover, we learn that the Miller haplogroup was born (or branches off from) its parent haplogroup about the year 1650 CE, so when the Millers were still living in either Switzerland or Germany. If we match males from either of those locations, they would probably match us upstream at R-BY115568. Their genealogy would certainly help our genealogy!

Ancient Connections, which are ancient DNA matches, extend beyond surnames, revealing connections to both the Yamnaya and Moros cultures and shared ancestry with Bronze Age Balkan burials.

Viewing the Ancient Connections tab, we learn that remains related to or upstream of our haplogroup were excavated in Albania, Germany, Hungary, Bulgaria, the North Banat and Mokrin in Serbia, and Macedonia. The closest genetic connections are shown first.

New Goal: Would love to test and match with Mueller men from Steindwenden, Germany, Schwarzenmatt, Switzerland, or anyplace near either location.

Kit 49,999 – Mr. Estes

Goals and Questions:

  • Do we connect with the Abraham Estes (c1647-1720) lineage?
  • Was there more than one early colonial Estes line?
  • If so, were they related?
  • Did our line come from Kent, England?

2005 – 25-marker test – $150

2006 matches –  54 12-marker matches

2025 matches – 326 12-marker matches

2006 matches – 4 25-marker matches – one to a known cousin, two more to other Estes males

2025 matches – 30 25-marker matches, including several Estes men

Crucial – this tester matched an Eastes male who lived in Kent and whose ancestors never left. This confirmed our oral history and early research suggesting that Abraham Estes’s origins were in Kent.
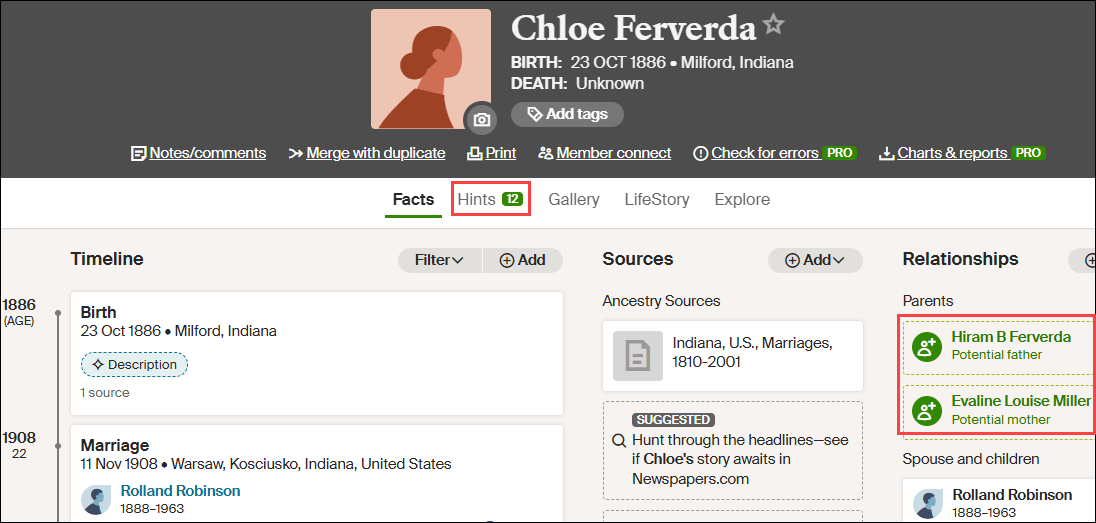
  • Original 2006 haplogroup – R-M269 – about 6.500 years old
  • Current Haplogroup – R-L151 – about 5,000 years old, SNP confirmed from the Family Finder test
  • Match Haplogroup – R-ZS3700 – about 250 years old obtained from STR match to multiple Big Y testers who shares same ancestor

In 2012, we added the Family Finder test for $199, which answered questions about whether multiple half-siblings were actually descended from a close relative of the tester. Family Finder also allowed people descended from this line, but who don’t carry the Estes Y-DNA to confirm their relationship to the Estes family.

This tester has not upgraded to the Big Y-700, but does match at the STR level with those who have taken that test.

Today, the Eastes male from Kent who subsequently upgraded to the Big Y-700 forms the base of the Estes family genetic tree, and others in the American lines form descendant branches based on the Big Y-700 test!

This includes some men whose genealogy we can’t yet connect vis the paper trail, such as kit 491887, shown in lavender below, but we know where he connects genetically. We were able to place him due to his Big Y-700 test results.

Thanks to the man from Kent whose results appear in the pink column, we know that both the Massachusetts and the Virginia immigrants descend from the Estes line in Kent, based on haplogroup R-BY490.

The Massachusetts line carries only R-BY482, so R-BY490 occurred in the generation between Robert b 1555 and Sylvester b 1600. Because the descendant of Sylvester’s brother Robert, born in 1603, does NOT carry the BY490 SNP, so we know exactly where and when it was introduced.

In Abraham’s lineage, two additional branches have been discovered. R-ZS3700, and within that haplogroup, R-BY154784.

All of this structure was built beginning with kit 9,993, followed by 49,999 (for my line), which is not shown in the chart above because there is no Big Y test, but whose STRs do match with kit 9,993, our very first Estes male to test.

Discover shows that R-ZS3700, the defining haplogroup of the Moses Estes lineage, kit 9,993, was born about 1750, which is within the genetic range of about 1600 to about 1820. Moses Estes, the man in whom this SNP originated, was actually born in 1711. The genetic tree closely matches the genealogy tree.

Ancient Connections reveals that we share distant ancestors from about 4400 years ago with Iron Age burials in Scotland, Cambridgeshire, Denmark, Dorset, Cornwall, Bedfordshire, Oxfordshire, Yorkshire, and Iceland. In other words, the Estes lineage has been in England for a very, very long time.

One of the upstream parent haplogroups, R-S252, dating from about 4500 years ago, was found in an Anglo-Saxon burial at Cliff’s End Farm, a mortuary and ritual Bronze Age site in Kent, England.

Cliffsend is only about 10 miles from Deal, where many Estes family records are found, and about 5 miles from Sandwich where Abraham Estes, the immigrant, was a weaver, next to the village of Worth, where he was married in 1672.

Kit 49,998 – Mr. Moore

Goals and Questions:

  • I was desperate to test a male from my Moore family in Halifax County, VA, and was very fortunate to locate Mr. Moore when I visited in person. I had to work on his genealogy, but once I was able to connect him, he was excited to test.
  • Could we connect our line with other Virginia lines, or eliminate them from consideration?

2005 -12 marker test – $99

2006 matches – 37 12-marker matches, two of whom were Moore men. One was a man I believed to be from my James Moore and William Moore line, and one we suspected, but really didn’t know. Many records from that time period are missing, and people were moving to the next frontier, with no connection to where they came from.

Mr. Moore’s matches, combined with his genealogy, confirmed what we thought we knew, but we still needed more.

  • Original 2006 haplogroup – J-M172 – about 28,000 years old
  • Current Haplogroup – J-M241 – about 8,600 years old, obtained from Family Finder
  • Match Haplogroup – J-Z631 – about 2,950 years old, obtained from matches to other Moore men who took the Family Finder test
  • Big Y Match Haplogroup – J-BY136349 – about 1,300 years old, obtained from a 111-marker Moore match to a non-Moore man who has taken a Big Y test

In 2012, we added Family Finder for $199, which provided invaluable matches to known Moore lineage family members, including Mr. Estes, kit 49,999. That makes perfect sense, since they are 4C1R.

2025 matches – 276 12-marker matches, of which five are Moore men, none of whom have taken the Big Y-DNA test.

One Moore match, who has not responded to emails, shows his paternal Moore ancestor as having been born in Scotland.

Three of Mr. Moore’s matches whose haplogroups were determined by Family Finder are J-Z631, which is closer to the present time than Mr. Moore’s haplogroup.

Why might that be?

Different autosomal DNA testing chips were used by different vendors at different times. Mr. Moore and the three other Moore men all took a Family Finder test at FamilyTreeDNA, but at different times when different chips were in use. That’s probably why the haplogroup assignment is different. The other reason could be that one of the SNP locations was missed in the autosomal DNA test. The haplogroup designation from the Family Finder test is a recent freebie, so was never actually intended to be a feature.

That’s all fine and dandy, but I STILL need a Moore Big Y tester to reveal more information about my line.

Workarounds for No Big Y Testers

Without a Big Y-700 Moore tester, is there something else we can try to obtain at least a somewhat more refined haplogroup?

Perhaps.

Without at least one Big Y-700 test, the next two things can do are:

  • Hope that someone has included at least some genealogy for you to follow.
  • One of the 111 marker matches will help by sharing if they have any Moore matches at that level. Remember, this kit, 49,998, only has 12 marker matches.

In this case, there is one match with a tree, but I hit the same genealogical brick wall that they did.

They, and now I am stuck with John Moore, born between 1851 and 1860, possibly in Sullivan County, TN. He was married to Mary, Polly, Mollie (take your pick based on the census and death certificates) Whitaker, who died between 1900 and 1910. John Moore died on September 25, 1936, in Sullivan County, TN, with several children and a brother named Bob Moore who lived in nearby Bristol listed in a brief obituary. I’m doing the “quick and dirty” tree thing, here, hoping to perhaps track his Moore back further than I have my own so we can connect – but so far – no cigar. I’m not finished yet, but this one is challenging. I’m always hopeful that I’ll find some hint about where James Moore (c1718-c1798) came from before Prince Edward and Amelia County, VA.

Eliminating Other Moore Lines

I certainly don’t have as much information as I want about my own Moore line, but I do have something. How can I use this to eliminate other potential Moore lines?

Checking the Moore Surname Project, I use the browser search and located the group of my James Moore testers.

These six men are candidates for Big Y upgrades.

I can also use the browser search to locate other groups of Moore men that have tested and I know we’re not related to.

For example, here’s another group of Moore men that we aren’t related but – but here’s the catch. This is the “other” James Moore that appears in Halifax County, and whose land is located right across the road from my James Moore. I kid you not. I could have SWORN these two Moore lines were the same, but they are not. This line track back to Thomas Moore born in 1720 and who married Mary Farrar. Using genealogy and projects, combined with what we do know, we can eliminate many possibilties.

Ok, let’s set genealogy aside for a minute.

Working With Alternative Haplogroups

What else can we do if we cannot upgrade either our tester or convince other Moore men to upgrade to the Big Y-700?

If a tester has higher level STR matches, meaning 67 or 111, and they match anyone with a Big Y-700 test, they will likely be in the same area of the genetic tree, but probably not the same branch, and possibly not within hundreds to the low thousands of years. This approach is an extremely poor substitute for the Big Y test and should never be used unless there is absolutely no other alternative. Think of it as sitting proxy at home, watching the Jumbotron on your TV, versus sitting behind home plate in the ballpark. It will do if you have no other choice.

That said, let’s see what we have. Our Moore Family Finder SNP is J-Z631, which is about 2,950 years old.

Our J-Z631 haplogroup story shows that the majority are found in Germany, followed by England, and the Ancient Connections are associated with the Roman era in the Balkans and Sicily. Burials from that era were found in Rome, Montenegro, Hungary, Poland, Serbia, Croatia, and Trapani, Italy.

Next, let’s look at one of the Moore men’s 111 matches, who has been assigned the Big Y-700 haplogroup of J-BY136349.

This is quite interesting, because this haplogroup has few testers, but the Ancient Connections are found in some of the same locations.

Next question – how are these two haplogroups related? Let’s see, using Discover’s Compare feature.

Wow, I didn’t expect to discover that J-BY136349 (111 marker match to a non-Moore man) is a descendant of J-Z631 (Moore haplogroup from Family Finder) and is about 2,200 years closer to the present time. Our Moore men, if we can ever find a Big Y-700 tester, will likely be someplace near J-BY136349.

Goals:

  • To upgrade at least one of Mr. Moore’s matches to the Big Y-700, and for some new Moore male to match so we can figure out which Virginia line, and which European line our Moore family descends from.
  • To break through the John Moore brick wall in Sullivan County, TN to see if we can track that lineage further back in time – informing us of our Moore line.

Kit 49,994 – Mr. Speaks

Goals and Questions:

  • To find and test any Speak/Speaks tester for our line.
  • Were the two Thomas Speaks in Maryland in the 1700s related?
  • Were various Speaks lines, by various spellings, throughout the country, related?
  • Where did we “come from?”

Twenty years ago, we had no Speaks males to test until Joyce, one of our long-time genealogy experts, located one man. She visited him and explained why his DNA was important. I provided a scholarship, and the rest, as they say, is history.

Not long after, another Speaks man tested, but did not match our original tester. Everyone was shocked. No one expected that result, and it only confused matters even more.

We needed tie-breakers, meaning other men from both of the known sons of immigrant, Thomas Speake (1633-1681).

At this point, we had far more questions than answers.

The Speaks Family Association had a whole list of questions, in part due to a lack of early records in Maryland, combined with burned southern states in later generations. That list was growing, not shrinking.

How many Speaks lines were there anyway? Had we stumbled across a descendants from the “other” Thomas Speaks in Maryland? I can’t answer that question now, and the answer is no, we had not accidentally found the other Thomas. That Thomas’s will and estate shows he had no sons other than a son Thomas who is not our Thomas, based on the fact that he died before his father. That also means there are no males from his line to test. You can read more, here, if you’re interested.

Did men with the surname Speak, Speaks and similar spellings all descend from the same Maryland line? Apparently not, or maybe not, based on those early results.

Could we determine through which men various testers descend?

At that time, we didn’t even dream that we’d be able to obtain Y-DNA from various men in the Lancashire villages where we thought our line might have originated. That was still years in the future. Our big breakthrough came after a Speaks man from New Zealand tested, and knew the name of the Lancashire village, Gisburn, where his grandfather was born. Working with local historical societies in England, we made that trip happen in 2014 and learned even more about differing Speaks lines.

In other words, in 2005, we were starting from scratch with pockets of men in various locations across the US who shared the same or similar surnames.

2005 – 25-marker – $150

  • Initial haplogroup – I-M170 – about 28,000 years old
  • Current 2025 haplogroup – I-FTA13986 – about 250 years old, obtained from a Big Y test

2014 – 111-marker upgrade – $184

2024 – Family Finder and the Big Y

2006 matches – Mr. Speaks had no 12 or 25-marker matches, which was discouraging. In fact, Mr. Speaks wouldn’t have any matches until the Family Association began actively recruiting testers a few years later. As it turns out, the Speaks family line has a rather unique DNA signature.

Today, Mr. Speak has 61 12-marker matches, and 54 25-marker matches, but it’s his Big Y results that confirm his placement in the tree as a descendant of John Speake the Innkeeper, son of Thomas Speake the immigrant.

Initially, we did the best we could, placing people in the tree based on STR results, but STRs did not provide the granularity we needed to define lines conclusively. STR mutations tend to back-mutate and aren’t always reliable.

Fast forward to January 2026.

The Speaks DNA project now has 48 Y-DNA testers, of which 32 fall into the Lancashire Speaks line we were seeking.

The Speak Family Association funded several Big Y-700 tests and upgrades for critical men in known lines.

Additionally, we’ve finally placed the elusive Aaron Lucky Speaks line, found in North Carolina, without any connecting documents back to Maryland. DNA connected him!

We’ve also eliminated several lines that were possibly connected to the Lancashire/Maryland line, thanks to DNA testing.

The Speak Family DNA Project Time Tree shows the Big Y testers with their self-identified earliest known ancestors (EKA) placed on branches of the genetic Time Tree.

Shifting to Discover, we see that Lancashire SNP, I-BY14004, which defines our Speak line, is associated with Medieval Britain, the early Slavs, and a historical Romanian culture.

Checking Ancient Connections, our ancestors are associated with burials from Yorkshire, Croatia, Romania, Denmark, Italy, the Czech Republic, France, Germany, and more, dating from about 4500 years ago.

Today, if a Speak/Speaks male takes a Big Y-700 test, we can assign his location in the tree very closely, and can tell him definitively which lines he does not descend from.

The Speaks project also welcomes all Speaks descendants, from any line, who have taken or uploaded autosomal DNA tests.

Regrets

Yes, I have regrets – learned in the school of hard knocks.

  1. My largest regret is that I didn’t test all of “my” kits at the highest level possible initially.
  2. My second regret is that I didn’t reach out to matches much earlier (when they still might answer) to inquire about genealogy and offer scholarships for upgrades. My testers need someone from that same line to match at the Big Y level. In some cases, I need that person to upgrade because my tester cannot. The longer you wait, the less likely you’ll receive a response.

Many tests, especially early tests, cannot be upgraded for various reasons:

  • Deceased tester
  • Lost the ability to contact the tester – obsolete or bounced email
  • Tester does not want to upgrade or does not reply to emails
  • Last vial available was already used and tester cannot provide another
  • Last vial was tested and failed

Solutions

  • Buy the most advanced test immediately. I literally have a kit available at all times.
  • Upgrade to the newest relevant tests as soon as they are introduced. In this case, that would be the Big Y-700 today and the Family Finder when it was introduced.
  • If the tester is deceased and you can contact the family, after offering condolences, ask for brothers, sons, or nephews who would be willing to retest.
  • Offer DNA testing scholarships either personally, through family associations, or through surname projects.
  • Request extra vials be sent to the tester so they can be returned and stored for future use.

There’s one more thing you need to do too.

Permissions

Testers can grant various forms of permission to other people, which allows their tests to be upgraded later. One man even sent me an affidavit stating I could do so after he died. Today, that’s not necessary because FamilyTreeDNA provides a Beneficiary service.

Permissions can be granted under the tester’s Account Settings.

  • Ask the tester to designate a Beneficiary which can be a Group Project Administrator. That means any person who is a group project administrator of a project the tester belongs to, after they are deceased.
  • Ask the tester to assign a Kit Manager who literally manages their kit on their behalf.

Under Project Preferences, project members can grant Advanced Access to individual project administrators by name. Advanced Access provides the ability for that specific administrator to act on behalf of the tester, including ordering upgrades and additional tests, so long as the administrator pays for them, which they often do with project funds.

Looking Back

I have absolutely no regrets about purchasing any of the tests I’ve bought over the years.

I look at it this way – if someone told me that a book about my ancestral line was in a library, and it held the undisputed truth about that one line – I’d spend far more than what I’ve spent on any one DNA test to obtain it. There’s simply no other way to conclusively unravel direct paternal vines, both within a genealogical timeframe, and before.

I want to know everything. Not just since the advent of surnames, but where my ancestors came from before that, and before that, and before that. I want to read about the culture and history of the land where my ancestors lived. What did they survive to travel to the next frontier? And where was that next frontier, and when?

Their own Y-DNA, passed down to their direct male descendants holds those secrets, just waiting to be revealed.

What’s Next?

  • Check your own and any Y-DNA tests that you sponsor or manage to see how they’re doing and what’s new.
  • Check surname projects at FamilyTreeDNA, here, to see if your ancestral surnames are represented any other information, similar to my Moore line.
  • Check your ancestor at WikiTree to see if anyone has entered a haplogroup for that ancestor, which tells you that someone has tested. The haplogroup may not be current, but it gives you a connection and someplace to start.
  • Check your autosomal matches at FamilyTreeDNA and any other vendor to see if you match surnames of interest. If the match is male, reach out and see if they descend from your line, and if they haven’t taken a Y-DNA test, would they be willing. If your match is female, reach out to see if it’s your line, and if so, if they know of males who have tested or would be willing.
  • If you’re a male and have not yet tested your Y-DNA, by all means, order that test now, by clicking here! Then make sure to join your surname project!

Is there something new and wonderful waiting for you?

_____________________________________________________________

Share the Love!

You’re always welcome to forward articles or links to friends and share on social media.

Subscribe!

If you haven’t already subscribed, it’s free. You’ll receive an e-mail whenever I publish by clicking the “follow” button at the top of the main blog page, here.

Help Keep This Blog Free

I receive a small commission when you click a vendor link in my articles and purchase that item. This does NOT increase your price but helps me keep the lights on and this informational blog free for everyone. Please click on the affiliate links in the articles or to the vendors below if you are purchasing products or DNA testing.

Thank you so much.

DNA Purchases and Free Uploads

Genealogy Products and Services

My Books

Genealogy Books

Genealogy Research
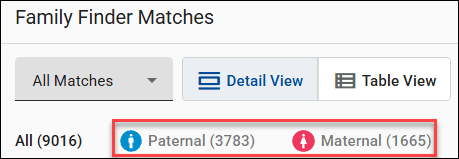
2025 Genetic Genealogy Retrospective: Wow – What a Year!

2025 has been quite a year in genetic genealogy. Genetic genealogy, per se, really isn’t a separate “thing” anymore. DNA testing is now an integral part of genealogy, with the potential to answer questions that nothing else can!

The 76 articles I wrote in 2025 fall into multiple categories and focus on different topics based on what was happening in the industry.

From my perspective, here are the most notable announcements and trends in genetic genealogy, and genealogy more broadly.

#1 for 2025 – Mitochondrial DNA: The Million Mito Project Released the New Mitotree, Updates, and mtDNA Discover

The biggest genealogy news items this year, both industry-wide and genealogy-changing are definitely the release of the new Mitotree, plus two tree updates. But that’s not all.

In addition, full sequence mitochondrial DNA testers received new Mitotree haplogroups, if appropriate, and everyone received a haplotype – a new feature. Along with Mitotree, FamilyTreeDNA introduced mtDNA Discover which provides 13 individual reports based on your haplogroup and matches.

It’s no wonder that mitochondrial DNA articles led the pack with the most views based on the eleven articles about that topic. If you haven’t yet tested your mitochondrial DNA at FamilyTreeDNA, there’s no better time! You never know what you’re going to discover and the more testers, the more matches for everyone.

You don’t know what you don’t know, and you’ll never know if you don’t test. Remember, mitochondrial DNA is for both males and females and tests your mother’s direct matrilineal line (mother to mother to mother, etc.) – reaching beyond known surnames.  Click here to order or upgrade.

#2 – MyHeritage Low Pass Whole Genome Sequence Test Charges into the Future

Another big hitter is the new MyHeritage low-pass whole genome test (WGS) test. It’s new and innovative, but we haven’t seen comparative results yet.

My results from the new low-pass whole genome test just came back, and I haven’t had the opportunity to review them yet, as compared to the earlier tests. That said, I do have roughly the same number of matches, but I need to determine if they are the same matches, and how well they track. I’ll be working on that review soon.

The new whole genome test may be more about future proofing and preparedness than additional current benefit – but we will see. I definately wanted to take the whole genome test so I can receive and benefit from whatever new is coming down the pike.

MyHeritage allows you to maintain multiple DNA tests on your account, so the new whole genome won’t “replace” your older or uploaded test. That way, you can easily compare the results of the whole genome against any DNA test that you curently have at MyHeritage.

Click here to order the new test.

#3 – 23andMe Experiences Problems

On a less positive note, but still quite newsworthy is the bankruptcy of 23andMe and subsequent repurchase of 23andMe by the original founder after setting up a new nonprofit. I have real mixed feelings about this topic. However, 23andMe was really never about genealogy, and now, matching segment information is no longer available. Those searching for unknown parents or family may want to test there if they are unsuccessful elsewhere.

Best Genealogy Tool

The FamilySearch full text search continues to have a HUGE impact for genealogists. This tool is not one-and-done, but provides increasing amounts of rich information as more records are added to the “fully scanned” collection. If you haven’t tried it, please do. It’s a game-changer and continues to improve.

A Cautionary Word About AI – Artificial Intelligence

AI is such a hot topic right now that I feel it needs to be included.

The FamilySearch full text search uses a form of AI. However, you’ll quickly notice that it can’t read everything, gets words and names wrong, and if you actually need to fully depend on it for accuracy, you cannot. (That said, it’s still an amazing tool, and I’m not picking on FamilySearch.)

Aside from FamilySearch, AI in its current form is both wonderful and terrible. I’ll be writing about AI in the new year, but for now, don’t ever rely on AI for anything that you can’t verity. It’s your assistant, not an expert, no matter how insistent it is. Never trust and always verify.

This is ESPECIALLY TRUE WHEN RELATED TO GENETICS and genetic related topics. I can’t even begin to tell you how very wrong it has been, and how much people fall in love with inaccurate results. No, just no – at least for now.

You need to know your AI tool, your skill set, your understanding of AI broadly, the tool’s limitations, and yours, and that’s all before verifying the actual AI results. If you want to educate yourself, and everyone should, treat yourself to anything, anyplace by either Mark Thompson or Steve Little, the dynamic AI duo. They offer YouTube videos and classes in a wide variety of places – but keep in mind that AI tools and technology literally change every few weeks.

AI is, indeed, a specialty all unto itself, much like genetic genealogy. And right now, it’s not soup yet, but it is cooking.
Tried and True Genetic Genealogy Staples – DNAPrint and Genetic Affairs

I haven’t written about either one this year, but I use both DNAPainter and Genetic Affairs regularly.

I consistently paint segments from matches at both MyHeritage, FamilyTreeDNA, and GEDmatch that are newly identified to an ancestor or ancestral couple at DNAPainter.

Unfortunately, neither Ancestry nor 23andMe provide matching cM location information for your matches (chromosome browser), but you may find some people who have tested at those companies at both FamilyTreeDNA and GEDmatch if they have uploaded to either of those vendors. Both vendors provide segment information and a Chromosome Browser, enabling you to paint that information to DNAPainter when you can identify your common ancestor.

MyHeritage also provides a Chromosome Browser, but unfortunately, no longer accepts uploads from any other vendor. You can paint segments from MyHeritage, but no longer upload DNA files to MyHeritage.

Thanks to DNAPainter, I have 90% of my segments identified to specific ancestors – which is actually rather remarkable given that my mother’s grandfather was a Dutch immigrant, and her great-grandparents on her other side were German immigrants, meaning we don’t have many matches on either of those lines.

Genetic Affairs continues to develop new, advanced clustering tools, one of which I’ll be reviewing soon.

Major Vendor Releases

Aside from what’s listed above, most of the major vendors released new features.

MyHeritage released a VERY COOL new tool called Cousin Finder that finds your relatives in the MyHeritage database, whether they match you on a DNA test, or not. They may not have even taken a DNA test. Cousin Finder identifies your common ancestor and shows your relationships. It’s a wonderful way to initiate communications, discuss your common ancestors, and ask about DNA testing.

Of my 378 Cousin Finder matches, only 23 (about 6%) are on my DNA match list, so that leaves 355 people to message, several of whom represent Y-DNA and mtDNA lines I don’t have. You can bet I’ll be offering testing scholarships.

Additionally, MyHeritage released a new ethnicity version.

FamilyTreeDNA, in addition to the new Mitotree, Discover, and associated features, released a new match matrix so you can see if and how selected matches are related to each other in a grid format. In other words, you can create your own cluster.

A new built-in “Share” feature blurs private information to make sharing easier both on the website and in Discover.

Discover improvements include thousands of new Y-DNA and mtDNA tree branches, plus thousands of new Ancient DNA samples. Discover is evergreen, so once you’ve taken that Big Y-700 test or the mitochondrial DNA test, your learning never stops as more content is added.

Tree integration with WikiTree is super-easy and means you don’t have to choose between trees. You can choose to retain your archived tree at FamilyTreeDNA, or move your tree to MyHeritage, PLUS link yourself to your family at WikiTree.

Ancestry released match clustering and a new beta pedigree view of ThruLines, but that’s back in the shop for more work. I’d expect to see it rereleased in 2026.

Conferences

RootsTech is the granddaddy of genealogy conferences, and it’s always fun to attend and write about the experience. Many vendors release new tools or products during the conference.

The ECGGC (East Coast Genetic Genealogy Conference), held in the fall, is the only conference that focuses entirely on genetic genealogy, new tools, how to use existing tools, and more. The 2025 conference was virtual and provided a great deal of focused content. Attendees particularly appreciate the deep dive in a particular topic presented in DNA Academy.

I’ll be at RootsTech in 2026, will write about that soon, and hope to see you there.

Concepts, Techniques and Plain Old Genealogy

In the past, my Concepts series and genealogy “how to” articles have been very popular, so, in 2025, I penned a half-dozen articles focusing on frequently asked questions about relationships and DNA.

For example, how does one go about finding DNA testing candidates? The number of options may surprise you and includes both Cousin Finder and Relatives at RootsTech.

By testing ONE PERSON for either Y-DNA or mitochondrial DNA that represents an ancestor, you actually receive information about that entire lineage of ancestors. So, on my Estes line, by locating an Estes male from my line to test, I received relevant information for every Estes male in my line, back to and beyond the progenitor.

Eventually, we hit a brick wall in every line, and those tools are the perfect way to break through those brick walls.

Other articles discuss things like how to use Discover’s Ancient Connections, and the difference between half and full relationships, both in your tree and genetically. Plus, what does a cousin “once removed” mean anyway? And why do I care?

Another question I receive is how far back, based on the shared amount of DNA, should I look in my matches’ trees for our common ancestor? In other words, how many generations back should I click? That article was fun and produced some unexpected results.

Memorial Articles

Because we are part of a community, I write memorial articles when one of our friends passes on. This year, sadly, Schelly Talalay Dardashti, well-known Jewish genealogist, and another very close friend joined the ancestors, so I’ve recognized the best in both of their lives which constitutes their legacy.

Be the Storyteller

Last, but not least, I wrote about my ancestors in the “52 Ancestors” series, which launched several years ago with Amy Johnson Crow’s challenge to write about one ancestor per week. She hosts this every year, and you can join (free) now.

I’m now on ancestor #467, so yes, it’s addictive, but it’s also AMAZING how many wonderful cousins I’ve met who have information that I did not. Not only that, but after publishing about an ancestor, I’ve discovered that I’m related to people I’ve known for years. We were SOOOooo excited!

I’ve been writing about the lives of my ancestors for several years now, and the articles include attempts to identify Y-DNA and mtDNA testers for each ancestor, where appropriate. There’s so much to learn that can’t be revealed any other way.

Plus, people seem to like the “mystery” and “short story” aspect, and I salt each story with the history of the region and relevant historical events of the timeframe. You might find your ancestors here too, or other helpful information.

Find a way to share about your ancestors!

Do You Have Suggestions for 2026 Topics?

Do you have suggestions or requests for article topics in 2026? If so, please comment on this article and let me know.

Check Out the 2025 List

Here’s the list of the 2025 articles. Did you miss something fun? Enjoy!

  Title Category Date Link
1 Welcome to 2025 – Opportunities and New Genetic Genealogy Articles Welcome, general 1-2-2025 https://dna-explained.com/2025/01/02/welcome-to-2025-opportunities-and-new-genetic-genealogy-articles/
2 Anne Doucet (1713-1791), Oceans, Rivers, and Perseverance – 52 Ancestors #438 52 Ancestors 1-4-2025 https://dna-explained.com/2025/01/04/anne-doucet-1713-1791-oceans-rivers-and-perseverance-52-ancestors-438/
3 Register for RootsTech 2025 Now RootsTech 1-16-2025 https://dna-explained.com/2025/01/16/register-for-rootstech-2025-now/
4 What IS the McNeil Family History, by George Franklin McNeil – 52 Ancestors #439 52 Ancestors 1-19-2025 https://dna-explained.com/2025/01/20/what-is-the-mcneil-family-history-by-george-franklin-mcneil-52-ancestors-439/
5 Jean Garceau dit Tranchemontagne (c1785-1711), Soldier from Saint Marseault – 52 Ancestors #440 52 Ancestors 1-29-2025 https://dna-explained.com/2025/01/29/jean-garceau-dit-tranchemontagne-c1785-1711-soldier-from-saint-marseault-52-ancestors-440/
6 Memories Resurface When the Old Family Home Gets a Facelift Genealogy 2-3-2025 https://dna-explained.com/2025/02/03/memories-resurface-when-the-old-family-home-gets-a-facelift/
7 MyHeritage Introduces Ethnicity v2.5 MyHeritage 2-6-2025 https://dna-explained.com/2025/02/06/myheritage-introduces-ethnicity-v2-5/
8 Relatives at RootsTech Reveals Cousins and Provides DNA Candidates RootsTech, techniques 2-8-2025 https://dna-explained.com/2025/02/08/relatives-at-rootstech-reveals-cousins-and-provides-dna-candidates/
9 FamilyTreeDNA’s New Matrix Shows How Your Matches Are Related to Each Other FamilyTreeDNA 2-12-2025 https://dna-explained.com/2025/02/12/familytreednas-new-matrix-shows-how-your-matches-are-related-to-each-other/
10 René Doucet (c1680-c1731), Lifetime of Incessant Upheaval – 52 Ancestors #441 52 Ancestors 2-15-2024 https://dna-explained.com/2025/02/16/rene-doucet-c1680-c1731-lifetime-of-incessant-upheaval-52-ancestors-441/
11 Lineages Versus Ancestors – How to Find and Leverage Yours Techniques 2-23-2025 https://dna-explained.com/2025/02/23/lineages-versus-ancestors-how-to-find-and-leverage-yours/
12 Mitotree is Born Mitochondrial DNA 2-25-2025 https://dna-explained.com/2025/02/25/mitotree-is-born/
13 RootsTech 2025 – The Year of Discover and the New Mitotree RootsTech, Mitochondrial DNA 3-14-2025 https://dna-explained.com/2025/03/15/rootstech-2025-the-year-of-discover-and-the-new-mitotree/
14 Pierre Doucet (c1621-1713), Walking History Book Lived to Nearly 100 – 52 Ancestors #442 3-16-2025 https://dna-explained.com/2025/03/16/pierre-doucet-c1621-1713-walking-history-book-lived-to-nearly-!100-52-ancestors-442/
15 Welcome to the New FamilyTreeDNA mtDNA Group Mitochondrial DNA 3-17-2025 https://dna-explained.com/2025/03/17/welcome-to-the-new-familytreedna-mtdna-group/
16 23andMe Files for Bankruptcy – What You Need to Know! 23andMe 3-24-2025 https://dna-explained.com/2025/03/25/23andme-files-for-bankruptcy-what-you-need-to-know/
17 New “Share” Features at FamilyTreeDNA Blur Match Information and Make Sharing Easy FamilyTreeDNA 4-1-2025 https://dna-explained.com/2025/04/01/new-share-features-at-familytreedna-blur-match-information-and-make-sharing-easy/
18 The Chauvet Cave: Trip Back in Time with Prehistoric European Humans – Are We Related? History, DNA 4-6-2025 https://dna-explained.com/2025/04/06/the-chauvet-cave-trip-back-in-time-with-prehistoric-european-humans-are-we-related/
19 DNA for Native American Genealogy Webinar & Companion Book Native American 4-8-2025 https://dna-explained.com/2025/04/08/dna-for-native-american-genealogy-webinar-companion-book/
20 Marie Levron (c1686-1727), Tragedy from Cradle to Grave – 52 Ancestors #443 52 Ancestors 4-14-2025 https://dna-explained.com/2025/04/14/marie-levron-c1686-1727-tragedy-from-cradle-to-grave-52-ancestors-443/
21 Mitochondrial DNA: What is a Haplotype Cluster and How Do I Find and Use Mine Mitochondrial DNA 4-14-2025 https://dna-explained.com/2025/04/14/mitochondrial-dna-what-is-a-haplotype-cluster-and-how-do-i-find-and-use-mine/
22 New Mitotree Haplogroups and How to Utilize Them for Genealogy Mitochondrial DNA 4-23-2025 https://dna-explained.com/2025/04/23/new-mitotree-haplogroups-and-how-to-utilize-them-for-genealogy/
23 Sir Francois Levron dit Nantois(c1651-1714), and Acadia’s Pirate – 52 Ancestors #444 52 Ancestors 4-26-2025 https://dna-explained.com/2025/04/27/sir-francois-levron-dit-nantois-c1651-1714-and-acadias-pirate-52-ancestors-444/
24 Catherine Savoie (c1661-c1722/25), Whispered Threads Weave a Tapestry of Life – 52 Ancestors #445 52 Ancestors 5-4-2025 https://dna-explained.com/2025/05/04/catherine-savoie-c1661-c1722-5-whispered-threads-weave-a-tapestry-of-life-52-ancestors-445/
25 Discover’s Ancient Connections – How Are You Related? Discover, Ancient DNA 5-8-2025 https://dna-explained.com/2025/05/08/discovers-ancient-connections-how-are-you-related/
26 Mother’s Day and Legacies 52 Ancestors, Genealogy 5-10-2025 https://dna-explained.com/2025/05/11/mothers-day-and-legacies/
27 The Mystery of the Blue Fugates and Smiths: A Study in Blue Genes and Pedigree Collapse Genetics, Genealogy 5-18-1015 https://dna-explained.com/2025/05/19/the-mystery-of-the-blue-fugates-and-smiths-a-study-in-blue-genes-and-pedigree-collapse/
28 Regeneron Wins Bid for Bankrupt 23andMe – Wedding Planned 23andMe 5-19-2023 https://dna-explained.com/2025/05/19/regeneron-wins-bid-for-bankrupt-23andme-wedding-planned/
29 Francois Savoie’s Homestead Rediscovered – 52 Ancestors #446 52 Ancestors 5-24-2025 https://dna-explained.com/2025/05/24/francois-savoies-homestead-rediscovered-52-ancestors-446/
30 Memorial Day – Some Gave All Memorial 5-25-2025 https://dna-explained.com/2025/05/25/memorial-day-some-gave-all/
31 Mitotree Webinar – What It Is, How We Did It, and What Mitotree Means to You Mitochondrial DNA 6-4-2025 https://dna-explained.com/2025/06/04/mitotree-webinar-what-it-is-how-we-did-it-and-what-mitotree-means-to-you/
32 Catherine LeJeune (c1633-1671/1686), Meet Your Grandchildren – 52 Ancestors #447 52 Ancestors 6-7-2025 https://dna-explained.com/2025/06/07/catherine-lejeune-c1633-1671-1686-meet-your-grandchildren-52-ancestors-447/
33 Mitotree Q&A for Everyone Mitochondrial DNA 6-11-2025 https://dna-explained.com/2025/06/11/mitotree-qa-for-everyone/
34 Father’s Day: Bravery and Love 52 Ancestors, Genealogy 6-14-2025 https://dna-explained.com/2025/06/14/fathers-day-bravery-and-love/
35 Francoise Bourgeois (c1659-1693/1697), High Drama in Beaubassin and Terror at Port Royal – 52 Ancestors #448 52 Ancestors 6-16-2025 https://dna-explained.com/2025/06/16/francoise-bourgeois-c1659-1693-97-high-drama-in-beaubassin-and-terror-at-port-royal-52-ancestors-448/
36 Requesting Suggestions for RootsTech 2026 Topics RootsTech 6-18-2025 https://dna-explained.com/2025/06/18/requesting-suggestions-for-rootstech-2026-topics/
37 FamilyTreeDNA and WikiTree Collaboration – In Two Easy Steps!! FamilyTreeDNA, WikiTree 6-25-2025 https://dna-explained.com/2025/06/25/familytreedna-and-wikitree-collaboration-in-two-easy-steps/
38 Jacques Bourgeois (c1620-c1700), Surgeon of Port Royal – 52 Ancestors #449 52 Ancestors 7-1-2025 https://dna-explained.com/2025/07/01/jacques-bourgeois-c1620-c1700-surgeon-of-port-royal-52-ancestors-449/
39 TTAM, a Nonprofit Formed by 23andMe’s Founder Now Plans to Buy 23andMe 23andMe 7-1-2025 https://dna-explained.com/2025/07/01/ttam-a-nonprofit-formed-by-23andmes-founder-now-plans-to-buy-23andme/
40 Jacques Bourgeois: Complex Acadian, Founder of Beaubassin – 52 Ancestors #450 52 Ancestors 7-6-2025 https://dna-explained.com/2025/07/06/jacques-bourgeois-complex-acadian-founder-of-beaubassin-52-ancestors-450/
41 How to Use Ancestry’s New Match Clusters and What They Mean Ancestry 7-10-2025 https://dna-explained.com/2025/07/10/how-to-use-ancestrys-new-match-clusters-and-what-they-mean/
42 Walk with Your Ancestors: Peace, Light and Healing in an Abandoned Medieval Village History 7-21-2025 https://dna-explained.com/2025/07/21/walk-with-your-ancestors-peace-light-and-healing-in-an-abandoned-medieval-village/
43 Jeanne Trahan (c1629-c1699), Life in Chinon, La Heve, Port Royal, and Beaubassin – 52 Ancestors #451 52 Ancestors 8-2-2025 https://dna-explained.com/2025/07/28/jeanne-trahan-c1629-c1699-life-in-chinon-la-heve-port-royal-and-beaubassin-52-ancestors-451/
44 Wherefore Art Thou, Oh Ancestor – New Generation Tree Chart Suggests Where to Look in Your Matches’ Trees Techniques, Genetics, Genealogy 8-2-2025 https://dna-explained.com/2025/08/02/wherefore-art-thou-oh-ancestor-new-generation-tree-chart-suggests-where-to-look-in-your-matches-trees/
45 Guillaume Trahan (c1601-1625), More Than Meets the Eye – 52 Ancestors #452 52 Ancestors 8-13-2025 https://dna-explained.com/2025/08/13/guillaume-trahan-c1601-c1684-more-than-meets-the-eye-52-ancestor-452/ 
46 The East Coast Genetic Genealogy Conference – ECGGC – Register Now for the Best of the Best ECGGC Conference 8-14-2025 https://dna-explained.com/2025/08/14/the-east-coast-genetic-genealogy-conference-ecggc-register-now-for-the-best-of-the-best/
47 Schelly Talalay Dardashti – May Her Memory Be a Blessing Memorial 8-17-2025 https://dna-explained.com/2025/08/17/schelly-talalay-dardashti-may-her-memory-be-a-blessing/
48 Francoise Corbineau (c1609-c1665), Bride in Chinon, Founder of Acadia – 52 Ancestors #453 52 Ancestors 8-25-2025 https://dna-explained.com/2025/08/23/francoise-corbineau-c1609-c1665-bride-in-chinon-founder-of-acadia-52-ancestors-453/
49 Nicolas Trahan (c1570->1632), Life in the Heart of French Wine Country – 52 Ancestors #454 52 Ancestors 8-31-2015 https://dna-explained.com/2025/08/31/nicolas-trahan-c1570-1632-life-in-the-heart-of-french-wine-country-52-ancestors-454/
50 Mitochondrial DNA A-Z: A Step-by-Step Guide to Matches, Mitotree, and mtDNA Discover Mitochondrial DNA, Discover, Genealogy, Techniques 10-2-2025 https://dna-explained.com/2025/09/02/mitochondrial-dna-a-z-a-step-by-step-guide-to-matches-mitotree-and-mtdna-discover/
51 Renée Desloges (c1570-1627/1632), Fragments of Life in Montreuil-Bellay – 52 Ancestors #454 (this is actually 455) 52 Ancestors 9-6-2025 https://dna-explained.com/2025/09/06/renee-desloges-c1570-1627-1632-fragments-of-life-in-montreuil-bellay-52-ancestors-454/
52 Best Mitochondrial DNA Presentation EVER – You’re Invited to DNA Academy!! Mitochondrial DNA 9-9-2025 https://dna-explained.com/2025/09/09/best-mitochondrial-dna-presentation-ever-youre-invited-to-dna-academy/
53 Unfillable Shoes Memorial – Douglas Rhodenbaugh 9-14-2025 https://dna-explained.com/2025/09/14/unfillable-shoes/
54 Concepts: What Does a Cousin “Once Removed” Mean? Concepts, Genealogy 9-24-2025 https://dna-explained.com/2025/09/24/concepts-what-does-a-cousin-once-removed-mean/
55 Daniel Vannoy (1752-after 1820), “Lived in the Boundary of the Cherokee Indians” – Say What??? 52 Ancestors 9-29-2025 https://dna-explained.com/2025/09/29/daniel-vannoy-1752-after-1820-lived-in-the-boundary-of-the-cherokee-indians-say-what/
56 Daniel Vannoy and the Strange Case of the Two Sarahs – 52 Ancestors #457 52 Ancestors 10-5-2025 https://dna-explained.com/2025/10/06/daniel-vannoy-and-the-strange-case-of-the-two-sarahs-52-ancestors-457/
57 Cousin Finder – MyHeritage’s Innovative New Tool Finds Your Relatives MyHeritage 10-9-2025 https://dna-explained.com/2025/10/09/cousin-finder-myheritages-innovative-new-tool-finds-your-relatives/
58 Sarah Hickerson Vannoy (c1761 – after 1826), Threw More than Shade – 52 Ancestors #458 52 Ancestors https://dna-explained.com/2025/10/13/sarah-hickerson-vannoy-c1761-after-1826-threw-more-than-shade-52-ancestors-458/
59 MyHeritage Introduces a Low-Pass Whole Genome Autosomal DNA Test & Why It Matters MyHeritage 10-14-2025 https://dna-explained.com/2025/10/14/myheritage-introduces-a-low-pass-whole-genome-autosomal-dna-test-why-it-matters/
60 Henriette Pelletret (c1640 – before 1694), Life Death in the Shadow of the Fort – 52 Ancestors #459 52 Ancestors 10-21-2025 https://dna-explained.com/2025/10/21/henriette-pelletret-c1640-before-1694-life-and-death-in-the-shadow-of-the-fort-52-ancestor-459/
61 Cheat Sheet: Mitochondrial Matches, Haplotype Clusters, and Haplogroups Mitochondrial DNA 10-22-2025 https://dna-explained.com/2025/10/22/cheat-sheet-mitochondrial-matches-haplotype-clusters-and-haplogroups/
62 Simon Pelletret (1610-1642/1645): A Walk Through Port Royal – 52 Ancestors #460 52 Ancestors 10-27-2025 https://dna-explained.com/2025/10/27/simon-pelletret-c1610-1642-1645-a-walk-through-port-royal-52-ancestors-460/
63 Perrine Bourg (c1626-1693/1698): Phoenix Rising from the Ashes – 52 Ancestors #461 52 Ancestors 11-2-2025 https://dna-explained.com/2025/11/02/perrine-bourg-c1626-1693-1698-phoenix-rising-from-the-ashes-52-ancestors-461/
64 Concepts: What is a Half Relationships, Life Half First Cousins, Anyway? Concepts, Genealogy 11-4-2025 https://dna-explained.com/2025/11/04/concepts-what-is-a-half-relationship-like-half-first-cousins-anyway/
65 Marie Broussard (1686-after 1752), Life Across the River from Port Royal – 52 Ancestors #462 52 Ancestors 11-10-2025 https://dna-explained.com/2025/11/10/marie-broussard-1686-after-1752-life-across-the-river-from-port-royal-52-ancestors-462/
66 Francois Broussard (1653-1716), Intractable Acadian – 52 Ancestors #463 52 Ancestors 11-22-2025 https://dna-explained.com/2025/11/22/francois-broussard-1653-1716-intractable-acadian-52-ancestors-463/
67 Mitotree Sprouts 12,773 New Branches and Includes Ancient DNA Mitochondrial DNA 11-24-2025 https://dna-explained.com/2025/11/24/mitotree-sprouts-12773-new-branches-and-includes-ancient-dna/
68 Catherine Richard (c1663 – after 1714), Mother of Beausoleil, Acadian Freedom Fighters – 52 Ancestors #464 52 Ancestors 11-29-2025 https://dna-explained.com/2025/11/29/catherine-richard-c1663-after-1714-mother-of-beausoleil-acadian-freedom-fighters-52-ancestors-464/
69 Ancestry’s ThruLines Has a New Pedigree View Ancestry 12-2-2025 https://dna-explained.com/2025/12/03/ancestrys-thrulines-has-a-new-pedigree-view/
70 Ancestry Reverts ThruLines to the Original View Ancestry 12-6-2025 https://dna-explained.com/2025/12/06/ancestry-reverts-thrulines-to-the-original-view/
71 Michel Richard (c1630-1686/1689), Carefree Acadian – 52 Ancestors #465 52 Ancestors 12-7-2025 https://dna-explained.com/2025/12/08/michel-richard-dit-sansoucy-c1630-1686-1689-carefree-acadian-52-ancestors-465/ 
72 Mitochondrial DNA: How Do I Know if I’m a Candidate to Receive a New Haplogroup? Mitochondrial DNA 12-9-2025 https://dna-explained.com/2025/12/09/mitochondrial-dna-how-do-i-know-if-im-a-candidate-to-receive-a-new-haplogroup/
73 Heavens Ablaze: the 1833 Leonid Meteor Storm and Your Ancestors History, Genealogy 12-15-2025 https://dna-explained.com/2025/12/15/heavens-ablaze-the-1833-leonid-meteor-storm-and-your-ancestors/
74 Madelaine Blanchard (c1643 – 1678/1683), Gone Too Soon – 52 Ancestors #466 52 Ancestors 12-20-2025 https://dna-explained.com/2025/12/20/madelaine-blanchard-c1643-1678-1683-gone-too-soon-52-ancestors-466/
75 Soar Inspiration 12-24-2025 https://dna-explained.com/2025/12/24/soar/

_____________________________________________________________

Share the Love!

You’re always welcome to forward articles or links to friends and share on social media.

Subscribe!

If you haven’t already subscribed, it’s free. You’ll receive an e-mail whenever I publish by clicking the “follow” button at the top of the main blog page, here.

Help Keep This Blog Free

I receive a small commission when you click a vendor link in my articles and purchase that item. This does NOT increase your price but helps me keep the lights on and this informational blog free for everyone. Please click on the affiliate links in the articles or to the vendors below if you are purchasing products or DNA testing.

Thank you so much.

DNA Purchases and Free Uploads

Genealogy Products and Services

My Books

Genealogy Books

Genealogy Research