FOCUS: Step 1 – Seven Solutions for DNA Matches with Absent or Shrunken Trees

This is the second article in the FOCUS series.

You can read the first article, FOCUS – A New Series Focused on Breaking Down Brick Walls, here.

DNA matches without trees, or bare-bones shrunken trees, can be a significant roadblock whether you’re looking at autosomal, Y-DNA, or mitochondrial DNA matches. To help resolve that issue, I’ve listed seven ways you can create or expand those trees. Not every methodology works every time, but none will work if you don’t invest the effort to try them.

I’ll probably say this in every article because it bears repeating. Everything we are working with is a hint. Breadcrumbs along the way. Sometimes they lead to the next wonderful breadcrumb. Sometimes to a dead end. Sometimes they look like useful breadcrumbs, but they are red herrings and not relevant. And sometimes they are simply wrong. Do not throw the baby out with the bathwater. Also, do not think every hint is accurate, because they aren’t, and many rely upon other people.

Our goal in the FOCUS series is to accrue evidence from multiple sources, tools and methodologies that leads us to our ancestor. So let’s start with trees.

Trees, Trees, But Not Everywhere

DNA testing relies on trees to identify our common ancestors, at least with matches beyond the closest generation or two.

This is true at all vendors, which is why all of the main vendors, except 23andMe, integrate with or provide trees as part of their platform.

Because we need to work with trees for all types of DNA testing and matching, I’m going to share various ways to overcome partial trees or even no tree at all. I’m intentionally using examples from multiple vendors throughout this series.

23andMe is omitted in this article because they don’t support trees, although testers can include a link to a tree elsewhere.

GEDmatch is omitted in this article because they are not a testing company. They are a DNA upload and matching site, so everyone at GEDmatch has tested elsewhere and probably has a tree there. You can upload a GEDCOM file to GEDmatch, though, so it never hurts to check and see if your match is there too.

Some of these techniques are vendor specific, and others can be applied broadly.

What Is a Shrunken Tree?

A shrunken tree is a small tree in which your DNA match has included only a few people. Small or missing trees tend to frustrate genealogists – a lot. I remind myself that these folks maybe seeking their family or new genealogists, trying to piece their tree together themselves.

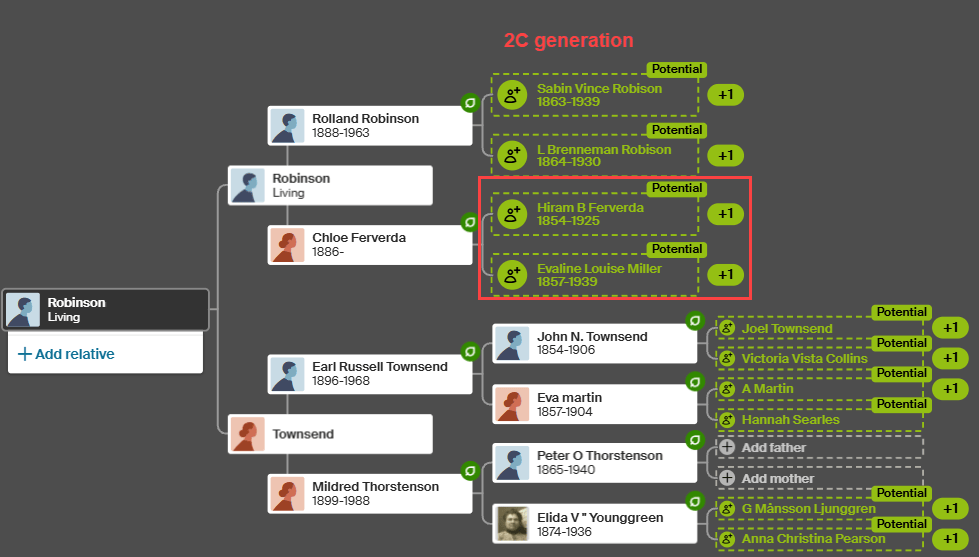
This is a tree provided by one of my matches. Their mother is deceased, but it’s recent enough that I’ve chosen to obfuscate her name as well, and it’s not relevant to the next steps.

There’s not a lot to work with here, but as it turns out, there’s enough.

Based on this tree, we have no idea where in their tree our Most Recent Common Ancestor (MRCA) is found, so let’s look at a few ways to indirectly expand their tree in order to find our common ancestor.

Step 1 – Check Your Own Tree

I know this sounds like a “duh” moment, but always remember to check your own tree to see if you’ve expanded that branch to include your match’a ancestors and completely forgotten about it. I maintain my primary tree on my computer with lots of notes and information that I’m not comfortable uploading to a public space. I maintain smaller public trees with a couple thousand people at both Ancestry and MyHeritage, along with a link to my ancestors at WikiTree.

If your match is a female, they may be using a married surname, so always keep that in mind. I try their complete name first. Then I search for their surname to see if it’s a “married-in” name – and cross my fingers that it’s not Smith. If they have any ancestors in their tree, I try their oldest generation next.

Step 2 – Reach Out to Your Match

Every vendor provides some way of communicating with your matches. You can either message or email, depending on the vendor, and your match may be very willing to share more about their genealogy. They may have a better tree elsewhere that they will share with you, or may know more than is in their tree.

An Ancestry survey showed that about 53% of Americans can’t name all four grandparents, and only 47% can correctly name all four. Only 4% can name all eight great-grandparents. In the Rolland tree, the tester knew more about their mother’s side, and only knew the first name of their paternal grandmother.

So while shrunken trees are exasperating, they are probably more normal that we think, and we all have to start someplace. Your match might well appreciate some help.

Step 3 – Check Other DNA Testing Sites

If your match has a real name (meaning not just initials or something indecipherable), such as Heather Jacobs (made-up name), who is predicted to be your third cousin and shares 100 cM of (unweighted) DNA at one vendor, sign on to your accounts at the other vendors and see if Heather is a match there.

You’re looking for a Heather, or maybe HJacobs or something similar, who’s approximately a 3C with roughly the same amount of shared DNA. The exact relationship prediction may not match, but it should be close, and the amount of shared DNA may not be identical either. If it varies substantially, it may not be the same person, so exercise care.

Every vendor provides the ability to search for matches by name, and if you can’t find them by name, begin paging until you reach matches at the approximate predicted relationship level. In Heather’s case, that’s third cousins. Beyond third cousins, this paging technique quickly becomes too laborious.

At Ancestry

Only one vendor, Ancestry, “downweights” your DNA with your matches, meaning that they may remove some amount of DNA that they consider “too matchy.” In my case, this is often DNA from my Acadian lines, which collectively forms pileup regions. This does NOT mean those aren’t useful, but that’s not relevant for this discussion other than to alert you that you need to check both the assigned amount of DNA and your unweighted shared DNA with a match when you’re trying to verify that the match is the same person at two vendors.

Assuming you find “HeatherJ” at Ancestry, you’ll want to verify that it’s the same person as Heather Jacobs at the other vendor.

Is your amount of shared DNA roughly the same?

Click on the relationship link to view the amount of unweighted DNA. In this case, weighted and unweighted is the same, and Heather Jacobs matches you with 100 cM at the other vendor.

Heather has a public tree here, and it’s the same size. It’s probably the same person, but check anyway.

Heather’s tree at Ancestry is exactly the same as it was at the other vendor, so this confirms it’s the same person.

There’s an important hint here, and let me emphasize the word HINT.

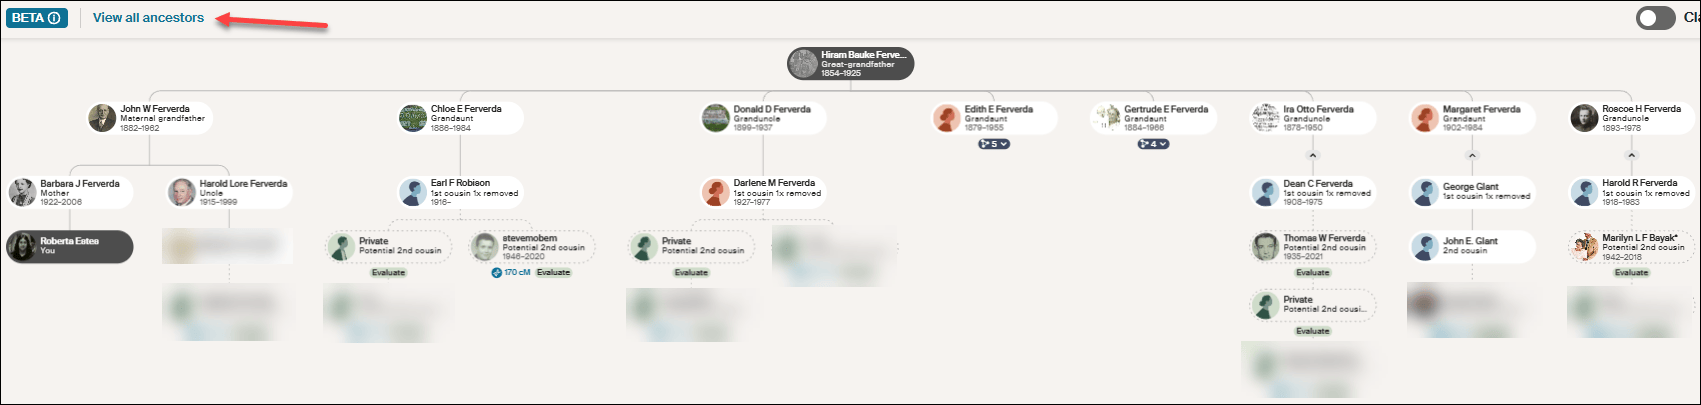
While Heather’s actual 15-person tree does NOT extend to our common ancestor, Ancestry has pieced together other trees that include and extend beyond her ancestors to show my (purported) common ancestor with Heather. Click on Common Ancestor, which takes you to ThruLines.

This new version of ThruLines has now replaced the older version. Unfortunately it does not show Heather’s path back to our common ancestor, Hiram Bauke Ferverda.

Click on “View all ancestors” in the upper left-hand corner.

Click on any image to enlarge

After clicking on “View all ancestors,” click on Hiram Bauke Ferverda to see the DNA matches who descend from him. Despite what Ancestry provided under my “Common ancestor” with Heather, she isn’t shown anyplace here. This could be a bug, given that I later confirmed this common ancestor using other techniques.

Regardless of the problem, this IS a hint, so don’t disregard it entirely. Just keep your “skeptic” hat handy and wear it liberally. You’ll need to use Ancestry searches and hints, including possibly Quick and Dirty Trees, to piece together the possibilities.

Make a note on Heather’s match at Ancestry so that you know what you found this time through. We’re not done with Heather. Move on to another vendor to see if Heather has tested and has a better tree elsewhere. We’re gathering evidence.

At MyHeritage

Heather is not at MyHeritage, so I’ll use a different example.

Let’s look for Cathy, a 3C match who has no tree at another vendor. I found her at MyHeritage with the same first and last name and approximately the same amount of shared DNA, so I’m confident it’s the same person.

Fortunately, at MyHeritage, Cathy has a tree, which is the first step, of course, but no common ancestor is shown in her tree.

MyHeritage has a wonderful feature called Theory of Family Relativity which are often based on “Smart Matches.” Click on “View theory.”

Click to enlarge

MyHeritage has found five possible paths to a common ancestor based on multiple documents and trees. In this case, Surrilda Claxton in my tree is the same person as Surelda Clarkson in Cathy’s tree, and MyHeritage made that connection correctly.

I confirmed this Theory at MyHeritage as accurate, and now I know how Cathy at the other vendor with no tree is related to me. I made a note about Cathy at MyHeritage on my match with Cathy at the other vendor too about our common ancestor AND where Cathy’s tree can be found. Add Cathy to her proper place in your trees.

Step 4 – Sleuth at the Same Vendor

At FamilyTreeDNA, when I find a match with no tree, I do two things.

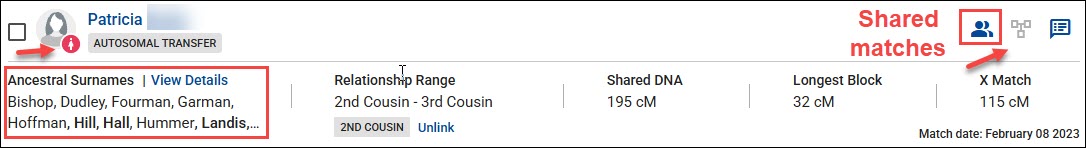
Looking at Patricia’s profile, I immediately see that she has been assigned to the maternal side of my tree. I’ve linked other known matches which allows FamilyTreeDNA to use triangulation to assign Patricia to the proper side.

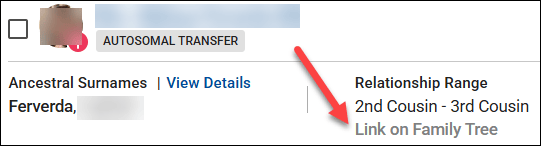
Then, I notice that even though Patricia doesn’t have a tree, she has provided her ancestral surnames.

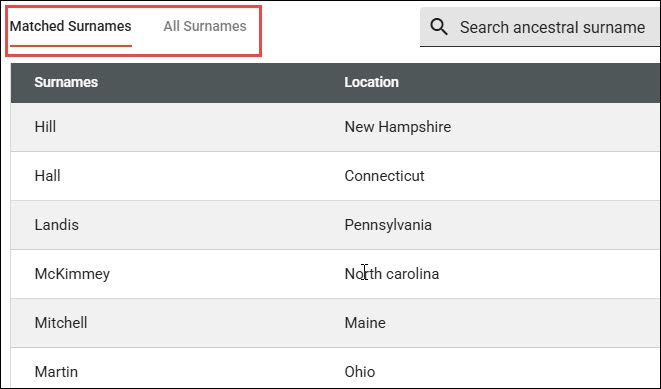
Clicking on “View Details,” I can see if any of them match my surnames, or I can view all of her surnames.

Given that this is my mother’s side, these shared surnames give me an idea of a shared lineage.

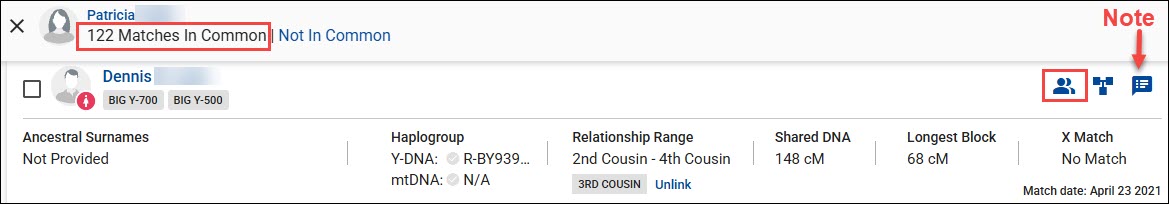
Next, look for your closest shared match WITH a tree. Clicking on the two little people at far right displays your shared matches which are labeled “in common with.”

I share 122 matches in common with with Patricia, and our closest shared match, other than my mother who is not shown here, is Dennis. Dennis happens to be a known relative, which is why he already has a note.

But for purposes of this exercise, let’s say that I haven’t already figured out how Dennis and I are related. Viewing Dennis’s tree, I see that our common ancestors are Anthony (Antoine) Lore and Rachel Levina Hill. Hmmm, Hill is on Patricia’s list of surnames.

Sleuthing at the same vendor is MUCH EASIER when your matches have at least a couple of generations in a small tree. Having no tree is the most difficult situation at every vendor, but there are multiple ways to begin building a tree for your DNA match, or to expand a shrunken tree.

Step 5 – Google Is Your Friend

Google is your friend. Google cannot reach behind paywalled sites, so you won’t find records other than records from free indexes at Ancestry or MyHeritage in Google searches, but you will find information about people from other genealogy sites.

Let’s go back to Rolland Robison who died in 1963 and his wife, Chloe. And let’s also consider that his surname is often spelled RobiNson. We know from our match’s tree that Rolland’s wife’s first name is Chloe.

Look closely at the search box in the image below. By structuring the query as “rolland robison died 1963 wife chloe”, we combine a full name, a specific vital event year, and a spouse’s first name. This gives Google just enough precise detail to hopefully filter out (most) noise.

That’s interesting. It looks like Rolland can be spelled two ways too.

Not only is there an article (yes, I wrote about this previously), BUT there’s also an obituary and estate distribution in a local newspaper that I have never seen before.

Rolland’s wife’s birth surname is given in his obituary, even though her first name is misspelled. This is the link I need to establish our common ancestor, because Chloe is my grandfather’s sister.

Google can provide you with important links to information and articles that are not yet in genealogical databases, such as:

  • Facebook accounts for individuals: Useful for finding the tester, relatives or family connections.
  • Facebook groups and pages: Forums that contain local historical information and shared community memories.
  • LinkedIn & Instagram accounts: Social footprints that often reveal professional histories, geographic locations, and birth surnames.
  • Mentions elsewhere: Local newspaper archives, digital press releases, and published legal notices regarding estate partitions or land records.
  • Obituaries: Printed family notices that explicitly list surviving family names and relationships along with the Legacy.com tribute archives.
  • Public websites & genealogy blogs: Independent sites where genealogists sometimes publish deep-dive ancestral lineages. Always verify.

Google also provides an easy way to find free resources in public databases without having to search each one individually, including:

  • Collaborative family trees: WikiTree, FamilySearch, and Geni trees.
  • Cemetery registries: FindAGrave and BillionGraves.
  • Digital libraries: Internet Archive and Google Books, which hold a vast assortment of historical information like out-of-print town and county histories.
  • Open-Access portals: The Library of Congress (LOC) and the Digital Public Library of America (DPLA), which pulls photos, maps, and civic documents from libraries across the US.
  • Volunteer projects: Regional repositories like GenWeb.
  • Directories: Local alumni directories and digitized historical yearbooks.

Pro Tip: Resurrecting Old RootsWeb and Genealogy.com Breadcrumbs

RootsWeb was a wonderful resource for genealogists until Ancestry began systematically dismantling it in 2023.

While Google is fantastic at finding obscure text, it will occasionally point you to an old, broken RootsWeb link. Because Ancestry has frozen or removed much of the old platform, don’t let that 404 error stop you in your tracks. Copy the dead URL from Google and paste it into the Internet Archive Wayback Machine where you can sometimes resurrect the exact information you need!

The same methodology applies to the old message board, Genealogy.com.

Step 6 – Search Old Emails and Files On Your Own Computer

I know this probably sounds either ridiculous or incredibly obvious, but if you’re a typical genealogist, you probably have a quarter century of emails on your computer, not to mention reams of photos that you saved because someone gave them to you and you “might need them someday.”

I’ve never thought of myself as the family archivist, but I clearly must be, which is another name for the family packrat. Long live the packrats.

I’ve learned that I need to search all of my email folders for the names in someone’s shrunken tree. I’ve been shocked at what I’ve found there.

Don’t just search for full names. For example, Rolland Robison or Chloe Ferverda. Search for the names individually too. So, Rolland, Roland, Robison, Robinson, and Chloe. I didn’t know Chloe was a Ferverda yet when I was initially searching for her identity.

A middle-of-the-night insomnia-induced epiphany struck – “search your emails.” Who needs sleep? It’s overrated! I hopped right up, searched my emails and my computer and found even more.

As it turns out, I attended a Ferverda family reunion in 2010 where I only knew two people. Thankfully, cousin Cheryl thought to invite me, because someone brought an old photo album AND an old Ferverda family Bible. I took photos of everything in the album even though I had no idea who most of those people were and neither did the album’s owner.

Many photos had no surnames at all, or they were recorded as Mr. and Mrs. SoAndSo.

Here are “Chloe and Rolland” as they were named in the photo, with no last name or additional information.

Here are Mr and Mrs. Rolland Vincent Robison. I carelessly saved this one as Rolland RobiNson. My bad.

A search for just “Rolland” found both, which is exactly why you need to search creatively.

Finding those initially still wouldn’t have told me who they were, but I would have at least had some family context, given that a Ferverda descendant brought the album to the Ferverda reunion.

However, this article about Rolland and Chloe’s 50th wedding anniversary from that same album would have provided that missing context.

My emails revealed now-deceased cousin Cheryl referring to Aunt Chloey, but with nothing else to identify her. A search for simply “Chloe” found Cheryl’s emails.

More tidbits of evidence.

I did a very poor job of saving these images with useful names because they weren’t relevant at the time, although I did store them in a “Ferverda Reunion” folder. Now, I’m going to attach them to Chloe and Rolland’s profiles in my tree at both Ancestry and MyHeritage to make sure they don’t disappear forever.

I’m also going to send them to my match with the abbreviated tree. As Rolland and Chloe’s grandchild, if they don’t have these pictures, I’m positive they will want them.

I’m sure you’ve noticed that I got VERY squirreled during this process, but utilizing all of our resources is exactly how we make discoveries – and sometimes that includes chasing squirrels.

This is also why our research journals are important – so we don’t chase the same squirrel over and over.

Step 7 – Quick and Dirty Trees

I used the Robison example in an earlier article discussing how to build a “quick and dirty” tree. I use quick and dirty trees often because it’s the easiest way to keep track of informational tidbits from different places, including multiple vendors, during the research process.

I’ll say it again here. Quick and dirty trees aren’t meant to be public. They aren’t gospel. They are a structure for you to work through the various hints provided and to evaluate them to see if they are of sufficient quality for you to identify a common ancestor with a DNA tester who provided a minimal tree.

You can read about these investigative workbenches in the article, What is a Quick and Dirty Tree, and When Might I Need One?

What’s Next?

Have you decided which of your brick walls you’re going to focus on? Last week’s article discussed some of the criteria you might want to consider and how to prepare.

Select your ancestor, because next week, we’re going to begin using a variety of tools and techniques to track that ancestor. Bit by bit, we’re going to gather evidence that will hopefully lead to a breakthrough.

FOCUS – A New Series Focused on Breaking Down Brick Walls

When I teach about genetic genealogy, people often ask, “What’s next? How can I break down my brick wall?” Sometimes I can reply that a Y-DNA test or mitochondrial DNA will help them under specific circumstances. But more often than not, what they really need is a precise, step-by-step methodology that includes autosomal DNA and utilizes multiple tools and techniques across vendors.

Even after people have taken Y-DNA and/or mitochondrial DNA tests PLUS autosomal tests at the major vendors, we still need a methodology to work with combinations of those results. Often, the answers we need aren’t just sitting there like a pretty rock, waiting to be picked up and admired, but depend on us using the results and matches as tools to help focus our search in the right direction.

It’s more like a scavenger hunt than a single discovery.

Focus

Sometimes I feel like a fish out of water – flip-flopping from ancestor to ancestor, match to match and hint to hint, hoping that the magic bullet will fall into my lap, but that almost never happens.

By this point in my research, I’ve perused all the easy records and many of the not-so-easy ones. If you don’t have a surname, or you don’t have a first name, or worse yet, you don’t have either, how is one supposed to search for records?

The good news is that you still carry at least one record in your own body and/or the bodies of your relatives. The DNA of your ancestors.

This is where we’re going to focus our efforts – hence FOCUS, the name of this new series.

Everyone is going to select their closest, or one of their closest, brick-walled ancestors, and we’re going to use several methods and tools to focus on identifying that ancestor.

Prepare

Before I publish the next article in the series, there are a few things that I’d like you to think about and do in preparation.

  • First, there’s no guarantee that you’ll break through your brick wall during this series. You might, and you also might not. You stand a much better chance of breaking through that brick wall if you focus and follow these steps than if you don’t.

Keep in mind that even negative evidence is evidence, and just because you don’t break through right away doesn’t mean you won’t. New people test everyday and new records become available too. If nothing else, your ancestor will have more meat on their bones, and you’ll have a process to build upon.

  • Second, if your brick wall is very close in time, meaning parents or grandparents, you’ll want the already-written “In Search Of Unknown Family” series, which you can find, here.
  • Third, you’ll need to keep a research journal or log by ancestor, family or location, which will also include your other related ancestors. For example, if you’re looking for Lucy whose surname you don’t know, but you know that she married William Moore, then your research journal will apply to William Moore too, and other people including their children and either spouse’s parents and siblings, whether that was your intention or not. The neighbors are probably relevant as well.

That “it takes a village” saying is particularly relevant here. People didn’t tend to move to the next location alone, and often their community consisted of their cousins and relatives – who are also your relatives, and hold clues to the identity of your ancestor. When I’m extracting records for the Moore surname in Halifax County, VA, for example, I extract everything for that and similarly spelled surnames, not just one particular person, so I don’t have to replow that field.

Tracking and Recording Your Research

If you don’t already have a research journal methodology, I would suggest a spreadsheet.

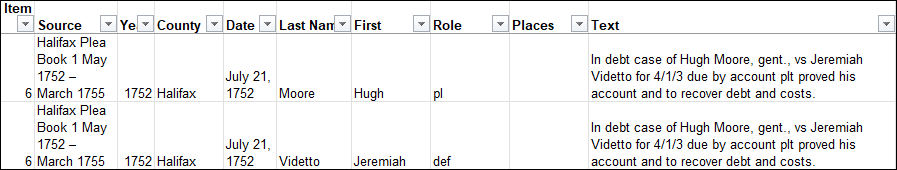
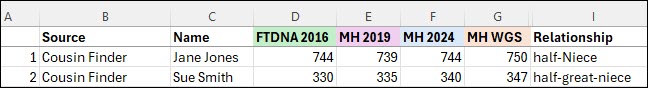
Here’s a screenshot of two rows in my “Halifax County” spreadsheet where I’ve recorded separate rows for each person in every record. Note that I started this spreadsheet years ago and omitted some columns that I later wished I had included, like the access date.

You’ll want to record:

  • Item number beginning with 1. In the example above, the item number is 6, and it’s 6 for every person in that record. Each person in this transaction gets their own separate row, with the same item number. The next record I extracted would be item 7.
  • Access date (date you found and retrieved the record)
  • Last name
  • First name
  • State (add a column for country if multiple countries are relevant for this family)
  • County
  • Town, township or city
  • Geographic places like road or creek names (these can be VERY important)
  • Year, month and day that the record occurred
  • Record repository or source (including a link if applicable – you may want to add a separate column for the link)
  • Record type (deed, will, tax list, etc.)
  • Role of individual (buyer, seller, witness, etc.)
  • Names of additional people in the record (I retain the same item number and other information, changing the name of the person, their role and sometimes an associated comment)
  • Transcribed text of the record itself
  • Comment, which can include things like the name of an image, something about what you were searching for when you found the record, links, or anything else relevant

You will want to be able to sort and filter this spreadsheet when you are finished. Hint – be sure your date fields and formats are sortable in the way you wish. I normally use filters instead of the sort feature.

The goal isn’t just to record your findings, but to make this spreadsheet as useful as possible to make discoveries that are only available by comparing and incorporating multiple records.

For example, let’s say that you’re extracting all of the Moore records in a Halifax County, VA deed book, and you want to know how many times the surname Henderson is found in the Moore deeds or in conjunction with the Moore family. Is there a pattern? You won’t recognize a pattern from any ONE record, but you may eventually wonder if the Henderson’s are related to the Moore family, and if so, how.

You’ll also want to record nonproductive or negative evidence. For example, let’s say you searched the Halifax County Plea Book for William Moore (including More and Mohr) and found no occurrences. That’s important, because otherwise you‘ll eventually search again, so enter that as a record item.

Note that with the full text search feature introduced by FamilySearch a couple of years ago, if you extracted records from a book that did NOT include every-name indexing including property lines, creek names and witnesses – you’ll want to redo that search using the full text feature at FamilySearch. There’s often LOTS of valuable information buried in records that won’t be found if you’re only viewing records indexed by buyer and seller, for example.

Your To-Do List Before the Series Begins

The In Search Of Unknown Family Series introduces important concepts, so reading that series is your first assignment in preparation for the upcoming FOCUS articles.

Test Your DNA With the Major Vendors

It’s important to test with the major vendors. Each vendor has matches and tools that the others don’t, and we need to identify and work with as many relevant matches as possible.

If you have NOT taken an autosomal DNA test at the first three following vendors, order these tests now so you have results to work with.

  1. AncestryDNA
  2. FamilyTreeDNA – Purchase a Family Finder test or upgrade an earlier Family Finder test to the new Family Finder NGS test. You should upgrade if you uploaded your autosomal DNA file from another vendor at any time, or tested at FamilyTreeDNA directly before March of 2026. The upgrade is only $29.
  3. MyHeritage DNA
  4. A fourth vendor, 23andMe, is optional, but testing there certainly won’t hurt.

23andMe Sidebar

I have an issue with 23andMe’s policy of forcing customers to repurchase a DNA test at $199 PLUS a subscription at $149 for the first year, renewable at $69 per year, in order to obtain any of their latest tools. This happened around the time of their data breach and subsequent bankruptcy.

I would feel much better about the situation as a whole if a new owner had taken the wheel, but the original owner resigned from the 23andMe board, formed another corporation, and was allowed to buy 23andMe out of the bankruptcy that occurred on her watch.

Furthermore, 23andMe does not support genealogy trees, nor do they have Y-DNA or mitochondrial DNA testing and matching, or research records.

I have (begrudgingly) ordered an upgrade for my own 23andMe test in order to include accurate information in these articles, but I won’t be focusing on 23andMe specifically aside from any unique feature. You can apply the same concepts and techniques to results at 23andMe where possible.

Test Your Relatives

If you have close upstream relatives, such as parents, grandparents, aunts, uncles, and cousins who also descend from your brick-walled ancestor, please ask them to test too.

I explain what I’m trying to achieve, why their test is important, and offer scholarships to sweeten the pie. I view purchasing their DNA tests in the same way I view purchasing a rare research book that I KNOW includes my ancestors but it not available anyplace else.

Your shared matches are extremely important and may provide that brick-wall-breaker. Perhaps even more importantly, they will have relevant matches that you don’t.

So how do you know who to test? You certainly want to test everyone relevant, without wasting money.

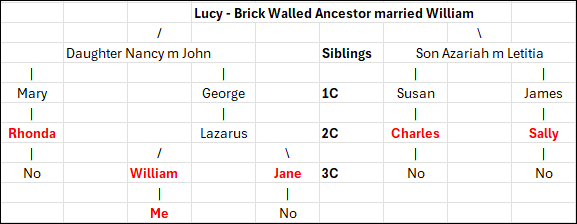
Let’s look at this example where Lucy is the brick-walled ancestor I’m seeking to identify. Her children (labeled siblings) and grandchildren (1C) are all deceased, but second cousins (2C), Rhonda, Charles and Sally are all available to test. Test each of them because they will all have some different segments of DNA from Lucy that the others don’t have.

Lazarus is also a second cousin, but he’s deceased. However, William, my father (in this example, not my real pedigree), and his sister, Jane are both available to test.

You ALWAYS want to test both of your parents and every available grandparent or direct ancestor. In this example, I’ll only inherit some portion of Lucy’s DNA that my father has, but Jane, my aunt, will carry segments of Lucy’s DNA that my father didn’t inherit from Lazarus. Jane’s matches on those segments that neither my father nor I have may be just what we need to identify Lucy.

If Lazarus has other children not shown in this example, we certainly want to test them too.

If the relevant parent has tested, you don’t need to test any of their children. However, if the parent hasn’t tested, absolutely test as many of their children or descendants as possible.

In this case, Rhonda, Jane, Charles and Sally have all tested, so I don’t need to test their children. Their children can only have as much of Lucy’s DNA as their parents had.

However, if any of them had been deceased, then I should test as many of their children as I can to “gather up” as much of Lucy’s DNA as possible.

If any of the people upstream of the bold red people have other children, those children or their descendants would be testing candidates too. Ideally, you want as many descendant testers as possible to increase your chances of identifying that ancestor.

Selecting Your Brick-Wall Ancestor

I want you to be successful, so you’re going to select your closest brick-walled ancestor within certain parameters. If you have multiple brick-walled ancestors at the at the same genealogical distance, you’ll choose one to focus on.

Why your closest brick-walled ancestor? If your brick wall is 5 generations back from you, and they are 5 generations back from your DNA match as well, that means you’re dealing with a 4th cousin match.

This also means that ancestor’s DNA has been divided a total of 10 times – five times on the path of descent to you, and five times on the path of descent to your match.

A 4th cousin match is likely to be in the 35 cM range. You can view the matching ranges for various relationships at DNAPainter, here.

The entire 4th cousin (4C) matching range is 0-139 cM. You won’t match all of your 4th cousins and are likely to match only 50-70% of your 4th cousins.

That said, the average person has between 1,500 and 4,000 4th cousins. At the 4th cousin level, you have 32 ancestors, so only between 46 and125 4th cousins will descend from any given ancestor, and of those, only a few will have taken a DNA test. The more children that ancestor had that lived to marry and have children of their own, the better your chances of more matches.

The Selection Process

I’m going to be stepping through the ancestor selection process with you, discussing who is and isn’t a good candidate, and why. I’m also going to be using this same methodology to (hopefully) identify one of my own mystery ancestors too.

I have no brick walls closer than 4th cousins. If I did, I’d choose the closest brick wall. You should too in order to have the best chance of solving this puzzle. The further back in time, the more difficult the solve will be.

In my tree, I have four mystery ancestors at the 5X great-grandparent level on my father’s side, and one on my mother’s side.

Those will be the four ancestors I consider selecting. And no, before you do it, I don’t recommend working on all four of them at the same time. Remember, the purpose is to FOCUS.

  • Select an ancestor as close generationally as possible, because it’s more likely that both you and other people will carry at least some of their DNA, and the same segment(s) of DNA. Matches closer in time generally carry more total DNA in common, which means better matching and more shared matches.
  • Given that the majority of testers are from the US, and assuming you are from the US too, I don’t recommend selecting an ancestor from another country unless you are very comfortable with that language and working with those records. Generally, there will be fewer people who have tested from other countries. If you are going to work with an ancestor from another country, be sure you are in both the MyHeritage and FamilyTreeDNA databases.

My mother’s entire paternal line is either Dutch or German Brethren, and her Dutch ancestors only immigrated in the mid 1800s, so have few descendants in the databases.

My closest brick wall on her paternal line is Traut Enterlein, a German man who was named in an out-of-wedlock baptism for his daughter in Germany in 1823. He is not found in any other records in that part of Germany, so actually identifying “who he is”, even with a name, would be extremely difficult, and I have nothing to “anchor to” here.  He is eliminated as a candidate because he’s found in a country where I don’t speak the language, where fewer people have taken DNA tests, and we’ve already spent a substantial amount of time trying to identify him in the records.

Brick-walled ancestors on Mom’s maternal side are two generations further back in time. Half are German and the other half are a combination of English and Acadian.

  • Avoid both endogamy and pedigree collapse, if possible. I don’t recommend a line with baked-in challenges that will make DNA more difficult.

Acadians are heavily endogamous and often suffer from pedigree collapse since there were so few founding families in the mid-1600s. The same goes for Brethren families who immigrated in the early 1700s. Those lines are too far back generationally anyway, so they have already been eliminated, but if they weren’t, I’d eliminate them because of heavy endogamy and pedigree collapse, both, not to mention record loss.

My father’s side has much better candidates.

  • Try to select an ancestor where you have some familiarity with the location, the culture, and the records. If you have printed resources at the ready, possibly ones that are not online, that’s a plus.
  • When you’re trying to decide between ancestors, select one whose spouse you are sure of, and who has children you can document. Do you know important things about them like their religion, where they lived during specific times, and who their neighbors were? If not, take some time now to brush up on what you do know about their spouse and children.
  • Check back at all of the records vendors and resources, including Ancestry, MyHeritage, WikiTree, and FamilySearch, to see if anything new is easily available for either your brick-wall candidate or their spouse.
  • I do NOT recommend selecting an ancestral couple, neither of whom you can identify, unless you’re “lucky” enough to have no other brick-walled ancestors to choose from. It’s possible to solve this “double-blind” couple, but it’s substantially more difficult because you have no same-generation anchor.

My Candidates

I’m selecting one of my brick walls and hope to solve it during this process. Let’s run through the decision-making process so you’ll understand some of the considerations and why they weigh as factors. I wish I didn’t have so many choices, and I’d like to solve them all, but my best chance is to work on one at a time.

Most candidates are women because their birth surnames tend to easily become lost after they marry, and with their surname, their parents are lost too. Given how little we know, we have to presume (dangerous word), at least for now, that your missing female ancestor was the mother of all of their husband’s children, unless we know or subsequently prove otherwise.

Let’s review my candidates.

  1. Lucy was born about 1754, probably in Virginia, and died in 1832 in Halifax County, VA. She married William Moore between 1772 and 1774, who may or may not have been a circuit-riding minister at that time. She is found under her own name on the 1830 census, there’s an 1826 chancery suit, and I know who her children and neighbors are, so she might be a good candidate. One vote against selecting Lucy is that I don’t know where she was born, nor do I know where they were married, although there’s a very strong possibility that it took place in Halifax County. The fact that he was a circuit-rider means he could have met her anyplace. If they were married in Halifax County, their families could have been allied before arriving there. William Moore’s family came from Prince Edward County about 1770, and we know who his parents were. One good thing is that Lucy is a fairly uncommon name, but there are multiple William Moores in Halifax County, and there are two other Lucy Moores. One is her daughter, and one is her daughter-in-law. The fact that Lucy and William Moore had 12 known children, with at least 8 who married, means there is a good chance of matching at least some descendants. Unfortunately, I don’t have her mitochondrial DNA, which removes one possible tool unless I can find a tester.
  2. Jane, born about 1760 in an unknown location, but probably Virginia, was the wife of Lazarus Dodson. They moved across multiple frontiers into what would become early Tennessee, an area that sustained substantial record loss. Jane died between 1830 and 1840. There’s a lot of uncertainty about Jane’s life. She probably had at least 8 children, and we know something about six of them. Given that we already have a better candidate with Lucy, I’ll eliminate Jane for now.
  3. William Crumley’s wife, whose name I don’t know, was born around 1765 or 1770, possibly in Virginia. She was married to William Crumley around 1786 or 1787, probably in Frederick County, VA, or nearby. I do have her mitochondrial DNA and we know the family was Quaker which are both benefits. I’ve been working with a cousin who has delved deeply into Quaker records, and I have some records from a trip to the FamilySearch Library in Salt Lake City that I have not yet processed. She and William had at least 10 children who married, and I know quite a bit about them. She would probably be an excellent choice. For lack of another name, I’ve been calling her H2a1, her legacy mitochondrial haplogroup before Mitotree, but she has a much more complete haplogroup now. She would be a good candidate, and I REALLY want to identify her.
  4. Mary, wife of John Harrold (by various spellings), was born about 1750, possibly in Ireland, although it would be unusual for a first-generation Irish immigrant to end up deep in the Appalachian frontier. Mary died in 1826 in Wilkes County, NC. We know nothing about John’s background, other than he served in the Revolutionary War, in Virginia. He may have been living in Botetourt County, although we don’t know for sure, and there are multiple men by that name. Mary had at least 7 children, six of whom were married. We do not have her mitochondrial DNA. Given that we know so little about John, and we have better candidates with both Lucy, William Moore’s wife, and William Crumley’s wife, I’m eliminating Mary for now.
  5. Isabel, the wife of Michael McDowell – another couple from Wilkes County, NC. Their daughter married the son of Mary and John Harrold. Isabel was probably born about 1750, someplace in Virginia. We don’t know where they were married, but it could have been in Franklin County, VA. They lived in Wilkes County for several decades before moving on to Claiborne County, TN. We know very little about Michael’s early life, other than his Revolutionary War service, although I’ve written about him four times as additional information dribbles out. They had at least 8 children, and a deposition after Michael’s death tells us where they moved and settled, which is a very big plus. We know her first name thanks to a 1793 deed. Isabel is a reasonable candidate, but I eliminated her after comparison to the other candidates, in part because of multiple frontier moves with few records and no known point of origin.
  6. Elizabeth, wife of Andrew McKee, was born about 1767, possibly someplace in Virginia. They were in Washington Co., VA by 1789, although we don’t know where either originated. They may have married before they moved to Washington County, where we find several records. They had 14 children. Twelve are known to have married, and the other two probably did as well. We know who their neighbors were. We also have Elizabeth’s mitochondrial DNA. Unfortunately, we know nothing about Andrew McKee’s family or where he was from. However, Elizabeth is a strong candidate because so many records exist in Washington County, they had a large number of children, and many continued to live in Washington County or nearby, making them easier to track.
  7. If I didn’t already have good candidates, there’s one more ancestor I’d consider, even though James Lee Claxton/Clarkson is a generation further back in my tree, born about 1775, and his unknown parents are the brick walls. I know I just told you NOT to do this, so I won’t either, but the reason I might have considered his parents, or more specifically his father, as a strong candidate is because we have several Y-DNA matches, including Big-Y testers, and we know the ancestors of his matches came from NC. We also have many autosomal testers and matches, which would help immensely, and there’s a Clarkson/Claxton DNA Surname Project. A contiguous surname is a HUGE benefit not available with female ancestors, and I just feel that I’m SO CLOSE to solving this mystery. For now, James’s parents are eliminated because they are two generations further back in time than our other candidates, we know nothing about either of them, except Y-DNA results, and we have better candidates for this exercise.

After evaluation, I still have two candidates in the running – Lucy, wife of William Moore, and H2a1, William Crumley’s wife. I haven’t decided for sure yet, but right now, William Crumley’s wife is leading because I have an amazing collaborator along with some unprocessed records that may hold important information. I know there probably aren’t any smoking guns there, but when combined with DNA, we may well ignite that gunpowder.

FOCUS

Are you ready to focus?

Let’s get our ducks in a row.

  • Order any DNA tests you need to order for yourself and relatives now.
  • Select your ancestor.
  • Prepare your research journal by reviewing which records you’ve already researched and record what you have.
  • Refamiliarize yourself. Take a look at those results again with fresh eyes. It helps when reviewing match results to be able to view surnames in your matches trees and recall that you’ve seen that name before, and where.
  • Check to see if any new records or resources are now available.

Who do you want to find?

_____________________________________________________________

Share the Love!

You’re always welcome to forward articles or links to friends and share on social media.

Subscribe!

If you haven’t already subscribed, it’s free. You’ll receive an e-mail whenever I publish by clicking the “follow” button at the top of the main blog page, here.

Help Keep This Blog Free

I receive a small commission when you click a vendor link in my articles and purchase that item. This does NOT increase your price but helps me keep the lights on and this informational blog free for everyone. Please click on the affiliate links in the articles or to the vendors below if you are purchasing products or DNA testing.

Thank you so much.

DNA Purchases and Free Uploads

Genealogy Products and Services

My Books

Genealogy Books

Genealogy Research

The New Family Finder NGS Test Results, Comparison, and Preparation

This article is focused on two things.

  1. Comparison of my new NGS and the earlier Family Finder tests
  2. How to prepare for yours if you’ve ordered the upgrade

I compared my results from my older Family Finder test with my new NGS Family Finder test results. As an early beta tester, I have two separate tests, a strategy that is not recommended because it causes duplicate matches for people within the database. Additionally, multiple kits for one person doubles the results and could skew future ethnicity research for myOrigins.

Therefore, FamilyTreeDNA has announced very attractively priced upgrades at $29 for both:

  • People who have taken Family Finder test directly at FamilyTreeDNA
  • People who have uploaded their DNA files into Family Finder from other companies

After seeing my comparison, you may want to compare your own results when they arrive, so I’ve documented that process. Warning: this took between 4 and five days because I was working with a spreadsheet with more than 15,000 rows, and I had to write scripts to perform multiple functions. It was NOT fun and I do not recommend it.

Personally, had I known then what I know now about how reliable the new NGS test is, I wouldn’t have bothered with the comparison. However, I would have downloaded my original match list for posterity, just in case.

If you purchase an upgrade to the new NGS Family Finder, your new test results will replace your older Family Finder test results, but will preserve important account features such as linked matches, any notes you have taken, and more. That’s another reason to upgrade rather than order a separate new test. They’ve done the heavy lifting, not to mention that you’ll save about $50 when compared to the price of a new test.

Why is the New NGS Family Finder Test Better?

The new NGS test holds immense promise for the future. This includes better matching, beginning now. Essentially, FamilyTreeDNA is skating to where the puck is going to be (hockey analogy) and preparing for future tools. That future is not far away!

An amazing new set of tools is goaled for release around the end of the year. And I do mean amazing. They are being beta-tested internally now.

Dave Vance spoke about the new Family Finder NGS test at the ECGGC conference in late August, which you can view through the end of 2026 if you register for the virtual  conference, here, and watch the recorded sessions. You’re looking for the DNA Academy on Saturday evening. I can’t share specific preview slides with you as they are noted in his presentation as “not for distribution,” so my pen is capped for now.

All I can say is that after seeing what’s in store, people were literally throwing their billfold at the folks at the FamilyTreeDNA booth – and I do mean literally. “Here – take my money, please!” as the billfold went sailing. We all had a good laugh, but he was serious.

One presenter (not me, just in case you are wondering) left her credit card and a list of tests to upgrade while she was presenting.

They ran out of swab kits at the conference shortly after Dave’s presentation about what the future holds.

Additionally, you will also be treated to THE absolute best presentation I’ve ever seen about what NGS testing is, how it works, and how it compares to traditional tests, low-pass whole-genome tests, and medical-grade whole-genome tests.

You’ll be a passenger on the Genome Valley train, so climb aboard!

So, without spilling any beans, what’s so great about the NGS test?

To begin with, the older Family Finder tests won’t be able to provide everything the new NGS test will be able to offer – and those completely new tools are in active development today.

Why?

The NGS test targets over 280 million base pairs, up from the currently available 700,000.

That’s more than 400 TIMES the coverage.

This increases coverage in the human genome from about .02% to about 9%.

To quote FamilyTreeDNA, “This change allows us to deliver more precise autosomal results today while creating a strong foundation for future reports and tools.”

You can read the FamilyTreeDNA FAQ here.

Before we move on to the comparison, let’s talk for a minute about test types and uploads from other vendors.

Tests and Uploads

All new Family Finder tests purchased at FamilyTreeDNA since March 2, 2026 have been tested using Next Generation Sequencing (NGS), so the following matrix does not apply to those tests. Those tests don’t need to be upgraded.

If you sign on to your account, on the Family Ancestry dashboard, and see that your NGS button is grey, then you have not upgraded. Click on that grey button to read more and to upgrade. Right now the upgrade is $29, but I don’t know if that is a promotional price or permanent.

If you tested at FamilyTreeDNA prior to March 2, 2026, or uploaded a DNA file from another vendor, your test will fall into one of the following upgrade path categories.

Tested at FamilyTreeDNA before March 2, 2026 Uploaded and purchased the Unlock Uploaded but did not purchase the Unlock
Upgrade Path Can use sample stored in lab if enough DNA remains* If you purchased any other type of test at FamilyTreeDNA, they will use DNA stored in the lab if enough remains. Otherwise, you will be sent swabs. If you purchased any other type of test at FamilyTreeDNA, they will use DNA stored in the lab if enough remains. Otherwise, you will be sent swabs.
New Swabs* If needed, they will notify you Yes, if needed, will notify or send swabs if you have not taken a direct test at FamilyTreeDNA Yes, if needed, will notify or send swabs if you have not taken a direct test at FamilyTreeDNA
NGS Results Will replace existing results Will replace existing results Will replace existing results

*You will be notified if enough DNA does not remain, and you will be sent new swabs. Be sure your address is current.

One of the reasons the NGS test performs better, even with existing matches from earlier tests, is because less imputation is involved. Let’s talk for a minute about imputation and how it works.

The Concept of Imputation

Most vendors change chips internally from time to time, and FamilyTreeDNA is no different. The difference this time is that the new NGS test covers exponentially more DNA than any earlier test, and all earlier tests combined. This means more than 400 times greater coverage, which in turn means less imputation is needed to compensate for the inevitable no-reads and to be compatible with files that tested different DNA locations.

Imputation is also used when comparing DNA files between vendors who don’t test the same locations.

Click to enlarge any image

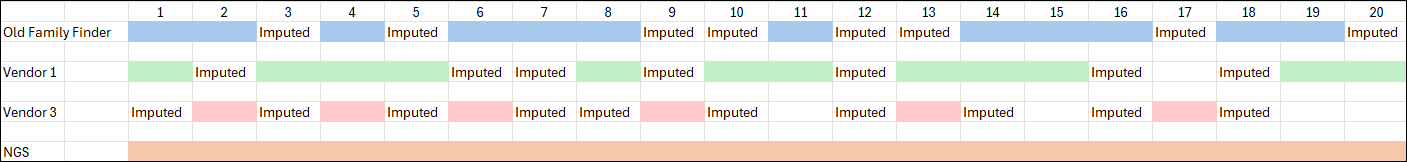
Here’s an illustration of the concept of how imputation works.

All of the FamilyTreeDNA chip versions over the years have included about 700,000 locations, as have most other vendors. But the locations tested are not universally the same.

In our simplified concept example, FamilyTreeDNA’s tested “locations” are shown with blue cells.

The total of 20 squares shows the maximum amount of DNA tested by any of the three vendors shown, combined.

Green Vendor 1 in our illustration tests the same amount of DNA that FamilyTreeDNA tests, 12 squares, but some locations are the same and some are different. Of the 12 colored squares for both vendors, seven are the same locations, and five are not. The locations that are the same can be compared directly, but the locations that are different have to undergo special handling called imputation.

Looking at any location in our DNA, one of four nucleotides, or letters, can be present: T, A, C or G on each strand of our chromosomes, although we are only looking at one strand in our example.

Using a very simplified model of imputation, think of imputation as “filling in the blanks” using clues from surrounding letters – kind of like a crossword puzzle.

When two vendors’ data doesn’t overlap, imputation is used to fill in the blanks, as accurately as possible, for the missing data.

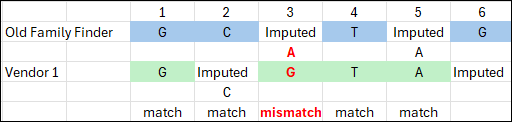
Using a word analogy, for vendors one and two only, we see that blue location three has no Family Finder data, where green Vendor 1 does, and the same with location five. If blue locations two and four are C and T, and three has to make a word, then there are few options. In this case, let’s say it’s cat, and location five is imputed to an A too.

Now moving to green Vendor 1, their locations two and five need to be imputed. Moving away from the word analogy, let’s look to the human genome, and let’s say that most of the time, location two is a C if location one and three are Gs. So green location two is imputed to C.

If there’s not enough quality surrounding data, imputation can’t be performed reliably. Hence, location six is still in limbo here.

You can see that in our scenario, location three is the only mismatch, out of three imputed locations. Does location three mismatch because imputation was wrong? We don’t know. Do locations two and five match because imputation was wrong? We don’t know.

All things considered, imputation is based on the science of probability, and is usually relatively reliable, but it’s still not the same as comparing actual data. The more locations that have to be imputed, and the longer the stretch, the greater the possibility of error. Every vendor implements imputation differently too. Even vendors who don’t and have never accepted uploads still use imputation internally to equalize their own legacy files from earlier test versions.

Stepping back once again to compare the four vendors, you’ll notice that pink Vendor 3 only tested half as much DNA as the blue Family Finder test and green Vendor 1, and again, not all of the same locations. That’s exactly what happened with one of the vendors last December – they dropped the number of DNA locations tested to about 400,000 from about 700,000. In our example, you can see how much would have to be imputed. Locations 11, 15, 19 and 20 can’t be imputed for the pink vendor’s file because there’s no surrounding DNA. Location 17 can’t be imputed for the green vendor for the same reason.

When vendors impute to match multiple versions of other vendors’ uploaded files, it can quickly become messy.

The answer, of course, is a “supertest,” which tests all of the locations that overlap everyone, including that vendor’s own earlier tests.

Welcome to Family Finder NGS, shown in orange at the bottom of our example comparison.

As you can see, the orange NGS test covers all of the locations tested by all of the other tests.

NGS is targeted testing for a specific set of locations that are known to undergo mutations in the human genome and provides extremely high-quality results. Imputation for the NGS file is rarely necessary, although imputation for the other vendors’ and earlier file versions is still required for them to match to each other.

This is exactly why the upgrade is recommended, and why there’s no benefit to retaining your old test. The NGS test tests far more data and provides much more reliable matching.

NGS is the great equalizer.

NGS Test Comparison Process

I took my NGS test during the initial R&D development and testing phase, so my original Family Finder test was not upgraded. This afforded me the opportunity to compare the two results.

I downloaded the match files for both of my tests, the original Family Finder and the new NGS Family Finder test, color-coded the background of the cells, not the text inside the cells, and dropped them into a single combined spreadsheet.

It doesn’t matter what colors you choose, but be sure you can easily see the difference. I used apricot for the original Family Finder test matches and light purple for the new NGS test.

As we walk through these results together, you’ll notice that I continue to refer to them by color. In part, that’s so I can maintain my own sanity as I compare results. When I write these types of articles, I have to check and recheck results.

When the same person showed as a match to both tests (meaning they had both an apricot and purple row), I calculated the difference in matching amounts of DNA (cMs) between the match’s results on both tests. I added several calculation columns, which are not shown above.

I’ll tell you, this was not a trivial exercise. It was painful and I really don’t recommend it.

Let’s take a look at the results.

Total Matches

I have some matches with the new NGS test that I do not have with the legacy Family Finder, and I have some matches on the older test that are no longer present on the NGS test.

  Old Family Finder (apricot) NGS Family Finder (purple) Difference
Total Matches 9014 7719 1,295
Maternal 1665 Not linked
Paternal 3783 Not linked
X-Matches 2198 1849 349

I have not yet linked the same matches in my NGS test, so I can’t compare the number of maternal and paternal matches. Fortunately, when you upgrade an existing test, FamilyTreeDNA preserves your linked matches, so you won’t need to relink.

Relationship Estimates

  Old Family Finder (apricot) NGS Family Finder (purple)
1st-2nd cousins, Great/Half Uncle/Aunt/Niece/Nephew, Great-Grandparent/Grandchild 6 6
1st-3rd cousin 1 1
2nd-3rd cousin 5 4
2nd-4th cousin 127 132
3rd-5th cousin 1937 1900
4th to remote 6938 5676
Total 9014 7719

The closest relationships remained the same. One 2nd-3rd cousin moved to the 2nd-4th cousin range by losing 10 cM, 194 cM to 184 cM, but they were apparently on the threshold anyway. That match is actually my second cousin, so both ranges are accurate. It was also a transfer kit, so they did not test at FamilyTreeDNA. This revised match is probably the difference between actual reads and imputed reads in some regions, meaning the match is now more accurate.

275 matches had a predicted relationship change, but not uniformly in one direction, and no one moved more than one category in either direction. This all makes sense.

Match Differences

  Number
Matches found in both the apricot and purple spreadsheets 7,352
Unique (comparable) matches in both spreadsheets 7,174
Matches in original Family Finder apricot only 1,681
Matches in NGS purple only 400

A total of 7,352 matches appear in both spreadsheets, meaning the apricot and purple names matched exactly.

Unfortunately, some people had multiple tests, so I couldn’t always compare apples to apples because they appear three times or more on the combined spreadsheet, and I don’t know which of their kits are which.

If someone with the same exact name had more than one match for either or both tests, I did not compare them because their matching amounts were different, and I didn’t know which one(s) my old test matched, versus which one(s) my new test matched. Usually, one was an upload and one was a test at FamilyTreeDNA, but not always. I excluded those 178 match rows from the analysis.

Therefore, 7,174 matches could be directly compared.

There were 1,681 people who match ONLY on the old Family Finder test, and 400 that match only on the new NGS test. And yes, I downloaded the match files at the same time on the same day, so this comparison was controlled for any time difference.

cM Differences

  Number
Largest apricot match not in purple (NGS) list 26.3 cM
Largest purple (NGS) match not in apricot list 27.63 cM
Largest difference 69.86 cM NGS kit more
NGS detected greater over 10 cMs 19
NGS detected less over 10 cM 7
Total NGS greater 2,924
Total NGS less 3,040
No change 1,090

The largest value difference where a match appeared in the original apricot Family Finder test, and not in the purple NGS test, was 26.3 cMs.

The largest value difference where a match appeared in the NGS purple Family Finder test, and not in the apricot original Family Finder test was 27.63 cMs.

The largest difference between the two tests was 69.86 cMs larger detected by the NGS test. This match was a known second cousin whose matching cMs went from 373.06 to 442.92, but the longest block only increased a negligible amount from 87.47 to 87.69.

The next largest difference was with a 1C1R with a 41.56 cMs difference, also with the NGS-detected value being larger.

In all cases where the number of differing cMs was 16 or greater, the NGS had detected more.

There were very few tests that differed more than 10 cMs. In 19 cases, the NGS test detected a greater difference of 10 cMs or higher, meaning if the original test value was 100 cMs, in the NGS test, it was 110 cMs or greater.

In 7 cases the NGS test detected a smaller difference of 10 cMs or more, meaning that if the original test value was 100 cMs, in the NGS test, it was 90 cMs or smaller.

Out of the 7,174 tests being compared, 19 tests with greater than a 10 cM variation isn’t very many, around 0.26%.

In total, 1,090 matches had no change at all, while 2,924 NGS matches had more matching DNA detected, and 3,160 matches had less.

All but 287 of those differences were less than 5 cMs, and 6778 were less than 1 cM. In other words, literally not worth counting.

myOrigins Ethnicity

We all know to expect changes in our ethnicity from time to time at all vendors. The NGS test is exciting because it covers a much larger portion of our genome. As more people test, the reference library also becomes larger, which means that the ethnicity predictions can and will become more refined too

myOrigins Old Family Finder (apricot) NGS Family Finder (purple)
Central Europe 57% 52%
England, Wales, Scotland 28% 33%
Ireland 15% 14%
Magyar <1% <2%
AmerIndian Andes and Caribbean <1 (see below) N/A
AmerIndian North America <1% (chr 1 & 13) <1 (chr 1 & 2)
Anatolia, Armenia, Mesopotamia, North Africa <1 (chr 13) <1% (chr 10)

None of my major categories changed, but the amounts attributed to each category changed somewhat.

Trace regions, which are less than 1%, shifted some as well, as did their chromosome locations.

For me, this is particularly interesting, because I paint my ethnicity segments at DNAPainter in order to overlay my Native American segments over the matches with whom I’ve identified common ancestors.

Those segments, matches, and ancestors, taken together, help identify the source of the Native American segments.

My Native segment on chromosome one stayed essentially the same, but the Native segment on chromosome 13 is not present on the new NGS test. However, a new Native American segment is now shown on chromosome 2 in the same location that 23andMe also shows a Native American segment.

Chromosome one has already been proven to a Native American ancestor on my mother’s side, but I have hit a brick wall on the chromosome 13 segment. Now, I’ve painted the Native Segment on chromosome 2 and it aligns with the same ancestral line as my Native American segment on chromosome 1.

My Middle Eastern/North African segment still exists, but the location has changed. This segment was adjacent to my Native American segment on chromosome 13 before, on my father’s side, which suggested a history of enslavement. I thought I knew which ancestral line they both descend from, but now I need to review my matches and reconsider.

Unfortunately, my parents are both deceased and there’s no DNA available, so I cannot upgrade their tests or purchase new ones for them. No aunts or uncles are available either. In this case, cousin matches and their associated genealogy on those segments become critically important.

Native American and African American segments are often the best, and sometimes the only hints we have to find and identify those ancestors.

Preparing for Your NGS Results

To be very clear, you don’t necessarily need to compare or prepare, BUT, if you order an upgrade to an existing test, your old match list will be replaced with the new one. Your old match list will not be preserved unless you do it.

What may change?

  • Your ethnicity results will probably change somewhat
  • You will have matches you did not have before
  • Some existing matches, especially at low matching levels, will no longer be there
  • The amount of DNA you share with some people will change

Important: Any notes you have recorded on your matches and any matches that you have linked will be preserved and carried over to your new results when your new test is complete.

If you want to preserve your matches from your earlier test, or your myOrigins results, you’ll need to download your match list, and either download or take screenshots of your ethnicity information.

Ability to Download Tested at FamilyTreeDNA before March 2, 2026 Uploaded and purchased the Unlock Uploaded but did not purchase the Unlock
myOrigins Can download Can download Cannot download
Chromosome Painter (ethnicity) Can download Can download Cannot download
Match list with segment and other information Can download Can download Cannot download
Raw data file Can download Cannot download* Cannot download*

*On tests you uploaded, you don’t need to download the raw data file because you already have it from the originating vendor.

What information is included in your Match List download file?

  • Match name
  • Relationship Range
  • Shared Data cMs
  • Longest Block cMs
  • Linked Relationship (if you linked them in your tree) – this feature is what allows FamilyTreeDNA to assign your matches maternally, paternally or to both sides using triangulation
  • Ancestral Surnames that they’ve entered
  • Y-DNA Haplogroup if applicable
  • mtDNA Haplogroup if applicable
  • Notes
  • Paternal/Maternal or Both side(s) match (if you’ve linked people and this match can be assigned using triangulation. (This is why it’s important to link as many people as possible to their place in your tree.)
  • X-Match cMs
  • Autosomal Transfer yes/no

If you match the same person on the NGS test, this information is preserved for that match.

Where to Download

You must have 2FA (Two-Factor Authentication) enabled for all downloads.

The files you may want to download are found on your dashboard in two locations.

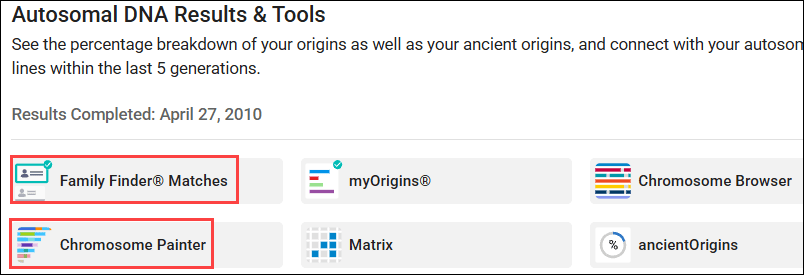
  • Family Finder Matches
  • Chromosome Painter (ethnicity)

Family Finder Matches Download

To download your list of matches with their complete information, click on Family Finder Matches on the dashboard, then on “Export CSV.”

This download provides all the fields mentioned above, whereas the Chromosome Browser segment download provides only your matching segment data, without the additional information.

Download MyOrigins Ethnicity Segment Data

To download your myOrigins ethnicity segments, click on Chromosome Painter on your dashboard, then on “Download Segments.” You can also view or copy those segments by viewing the Detailed Segments tab.

I paint these segments at DNAPainter so that I can correlate my ethnicity regions with my ancestors’ segments.

To assign segments accurately, it helps immensely to have at least one parent’s DNA results too, and preferably both.

You may also want to take a screenshot of your myOrigins map. Note the left-side scroll bar when you’re taking screenshots.

What’s Next?

What else can you do at FamilyTreeDNA to benefit your genealogy?

  • If you haven’t already, upload a GEDCOM file or create a tree at MyHeritage, and link your Family Finder test to your results.
  • Link your individual matches to their place in your tree. This allows FamilyTreeDNA to use segments triangulated with linked matches to assign other matches to either the maternal or paternal side of your tree, or both.
  • Add your line to WikiTree. It’s easy. Begin with yourself and add ancestors until you connect with someone who is already in WikiTree. For me, it was the grandparent level.
  • Add your WikiTree link to your FamilyTreeDNA account under the gear in the upper right-hand corner, then Genealogy, then Family Tree. This gives your matches an easy way to identify common ancestors by using WikiTree’s Find Relationships feature, and provides two types of tree resources for you and your matches – MyHeritage and WikiTree.
  • Make sure your Earliest Known Ancestor information is correct and up-to-date with your most recent research, including a specific map location. You’ll find that under the gear too, then Genealogy, then Earliest Known Ancestors.
  • Add your surname list to your profile under the gear, Genealogy, Surnames tab.
  • Use the Matrix tool at FamilyTreeDNA to see how much DNA your shared matches share with each other.
  • Y-DNA – If you’re a male, test your Y-DNA, which is your father’s direct paternal line. The Big Y-700 test provides you with matches and the most detailed information possible.
  • mtDNA – Everyone can take a mitochondrial DNA test, which shows matches and provides information about your mother’s direct matrilineal line.
  • Use Advanced Matching, found under Additional Tests and Tools on your dashboard page, near the bottom, which allows you to select from multiple tests to see who matches you on both types of tests. For example, those who match you on both your full sequence mtDNA test and your Family Finder test.
  • Join projects relevant to your family surname, geography or broader interests. You’ll find Group Projects in the top banner of your dashboard page after signing in.
  • Utilize the Discover tools for both Y-DNA and mitochondrial DNA results.

Check your matches often to see who is new and what might have changed as people upgrade to the new NGS test and more people test.

_____________________________________________________________

Share the Love!

You’re always welcome to forward articles or links to friends and share on social media.

Subscribe!

If you haven’t already subscribed, it’s free. You’ll receive an e-mail whenever I publish by clicking the “follow” button at the top of the main blog page, here.

Help Keep This Blog Free

I receive a small commission when you click a vendor link in my articles and purchase that item. This does NOT increase your price but helps me keep the lights on and this informational blog free for everyone. Please click on the affiliate links in the articles or to the vendors below if you are purchasing products or DNA testing.

Thank you so much.

DNA Purchases and Free Uploads

Genealogy Products and Services

My Books

Genealogy Books

Genealogy Research

What is a Quick-and-Dirty Tree, and When Might I Need One?

You may have heard genealogists talk about creating a quick-and-dirty tree.

What is that, exactly? When and why would you want one?

Good questions.

Matches and Trees

DNA matches don’t always have useful trees.

They might have:

  • No tree
  • A partial tree with only a few people in the closest generation or two
  • A tree with some lines built out, but others not so much

What’s a genealogist to do? After all, it’s your match’s tree, not your tree, and you have no way to expand their tree.

Except, you do.

It’s called a quick-and-dirty tree.

Quick-and-Dirty Trees

A quick-and-dirty tree is essentially a “throw-away” tree that you construct at Ancestry with the express purpose of obtaining hints, including potential parents, in order to quickly build your matches tree backwards in time until you (hopefully) reach a common ancestor.

And yes, of course trees, hints and suggestions of any kind can be wrong – but that doesn’t mean they’re always wrong, and you’re not adding anything from your quick-and-dirty tree to your tree – or even displaying it publicly.

You’re simply trying to find a common ancestor by using what your match has provided in their tree. Think of a quick-and-dirty tree as a scratch pad of sorts.

Let’s work through an example.

Initial Analysis

In this example, Ancestry has already told me that this match is most probably my half-second-cousin (half 2C) or second-cousin-once-removed (2C1R) based on the amount of DNA that we share, although the full relationship range includes several more options.

Ancestry also tells me that this match is on my maternal side. There’s no information provided about whether this match is on their maternal or paternal side, or even both.

A second-cousin (2C) relationship means that we share great-grandparents, and once removed means that one of us is one step further down the tree than the other person.

In other words, I’m 2C with my match’s parents, or my match is 2C with my mother. I wrote about this in the article, Concepts: What Does a Cousin “Once Removed” Mean?

I see that my match has a public linked tree with 7 people, which probably isn’t going to be terribly helpful.

Of course, the first thing to do is to review my match’s tree and see if I recognize either their surname or the names in their tree.

This tree only reaches back two generations, and our common ancestor, based on the relationships predicted by shared DNA, would be another generation, or two, further removed.

I don’t recognize any of these names, although I’ll review each person for a location to see if I can narrow the scope to the couple most likely to lead to our common ancestor.

On my mother’s side, one of her parents is from northern Indiana, and one is from southern Indiana, but not everyone enters locations in their trees, and they aren’t necessarily accurate.

The list of “all people” in my match’s tree, under “Find in tree”, at far right, provides additional information. Unfortunately, this tree shows Earl Townsend’s wife’s name as Mildred Ideal Thorstenson Townsend Smith here and in her profile, but the name order differs. To begin, I’ll enter Thorstenson Smith, not her married name of Townsend, in the quick-and-dirty tree I’m building. You can refine this shortly.

In this case, it looks like the Townsend line is most promising to find a common ancestor, given that Fulton County is in northern Indiana, but we’ll find out that this isn’t the case when we construct our quick-and-dirty tree.

Building the Quick-and-Dirty Tree

You need to build a new tree, NOT add to your “real” tree.

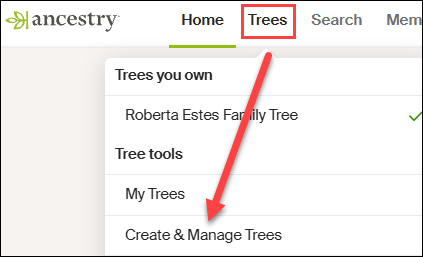
At Ancestry, go to Trees in the top banner, then click on “Create and Manage Trees.”

You’ll see the list of trees that you own. This is where all of the trees that you create live.

At the far bottom, you’ll see the prompt to create a new tree. Click there.

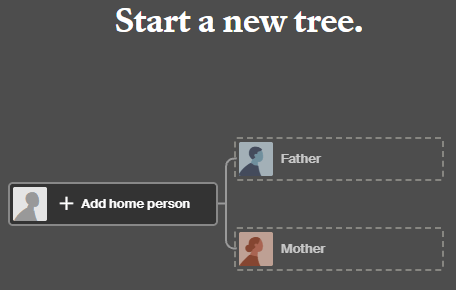
Next, you’ll see a blank tree.

For the home person, you can enter your match’s name, but be sure to list them as living so you’re not revealing private information.

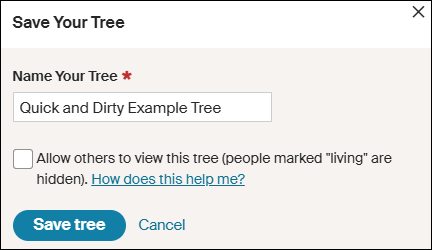
After adding one parent, you’ll be prompted to save and name the tree. Both the tester, who is designated as male by the Ancestry icon, and his father are either both living, or private, so I’m simply entering the surname of Robinson based on the grandfather’s surname. That could be incorrect of course, but it’s all I have to go on – yet.

Ironically, their grandfather’s surname was spelled Robison, without the “n”, not Robinson, but I accidentally entered Robinson and still got where I needed to go.

Clearly, I’m not going to allow this tree to be viewed by others, aka public, so I’m not checking that box. If it’s checked by default, uncheck it.

I don’t make my quick-and-dirty trees public because they are entirely unproven and unverified. I’m literally quickly searching for hints with every intention of abandoning the tree when I’m finished. If you want to clean the tree up later, you have the option to change the tree’s privacy settings.

Information in Your Match’s Tree Might Be Wrong

Complete the tree to be the same as your match’s tree. After saving your tree, click on the individuals you’ve added to view their hints.

Let’s start with Earl Townsend who appears to be our best candidate based on location.

Earl Russell Townsend has 13 hints, including a marriage license that confirms his birth date and location and provides the names of his parents, plus his wife’s name as Mildred Thorstenson. Based on what we know already, this is probably the correct Earl Townsend.

Of course, the wife’s surname could be incorrect. It could be her first or second marriage, or she could have been a widow when they married, so this surname might not be her birth surname.

Look for additional records in Earl’s hints.

Russell’s death certificate confirms that information, as do the birth and death certificates of their children.

Accept those hints.

If you determine that the original information in your match’s tree is incorrect, you’ll want to correct it in your quick-and-dirty tree. Remember, this is a scratch pad – you can’t hurt this tree.

Let’s change Mildred’s name to reflect her birth surname.

I refined Earl’s wife’s name to Mildred Thorstenson, which then produced 12 hints for her, including her marriage and Social Security record, with her birth and death dates, and her parents’ names. Her name in my match’s tree of Mildred Ideal Thorstenson Townsend Smith had produced zero hints.

Additionally, census records showed Mildred with her parents.

These seem to align, so accept those hints.

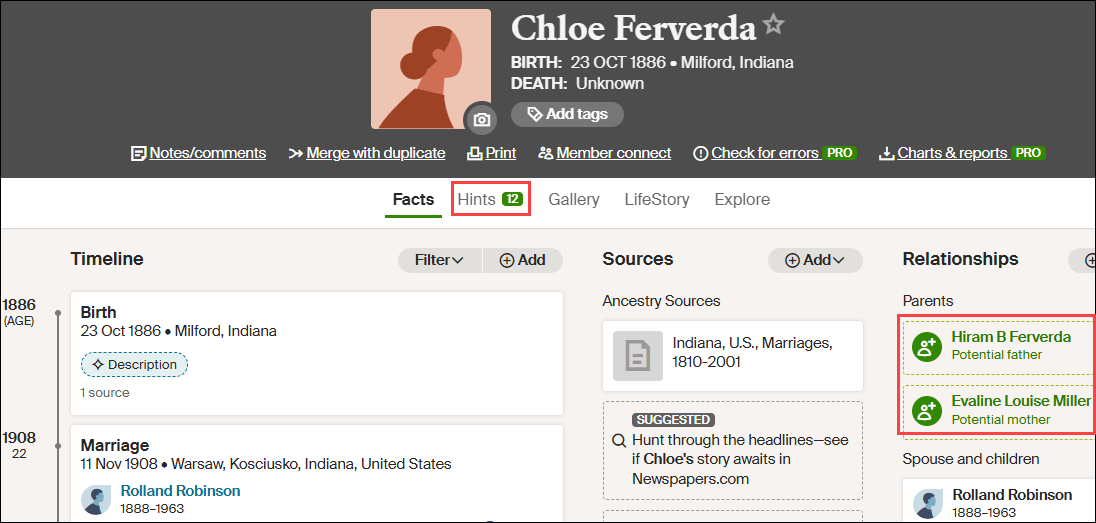
Looking at the pedigree view of my quick-and-dirty tree, we now see that both Russell and Mildred’s parents identified in the records are suggested as their potential parents.

Review each suggestion. If they look accurate based on the records identified, accept those potential parents in order to view the next generation.

Based on these names and census information, I can eliminate the Thorstenson line. It’s Swedish, not German or Dutch, which comprise my mother’s northern Indiana lines, My mother has no known Swedish ancestors, and we have proven her Indiana lineage in this timeframe.

Accepting the hints for the parents of both Earl Townsend and Mildred Thorstenson, parent hints appear for John Townsend and Eva Martin.

Now we’re viewing the next group of hints, which would be the great-great-grandparent generation. If these are our common ancestor, that would mean that I’m third cousins with my match, which is beyond the predicted relationship range. Third cousins is not impossible, but it’s beyond the probable match level based on the amount of shared DNA. furthermore, I don’t recognize any surnames.

So, let’s move to the Robison (incorrectly spelled Robinson) line and step through the same process. We can always come back and work with more parental hints on the Townsend/Martin line if we need to.

Rolland Robison only has a death year in my match’s tree, and that combined with the misspelled surname meant he had no hints on Ancestry, so I clicked on “Search” in my quick-and-dirty tree.

I’m searching for a man by this name, with a wife whose first name is Chloe.

AHA!

There it is! Note that Ancestry found Rolland Robison, not Robinson, married to Chloe.

Chloe was a Ferverda. My mother’s father was John Ferverda, and the location is correct for this family.

I saved this record to Rolland Robinson and added Ferverda as Chloe’s surname in our quick-and-dirty tree. This provided Rolland with 12 hints.

Adding Ferverda as Chloe’s surname provides her with a dozen hints too, including potential parents, Hiram B. Ferverda and Evaline Louise Miller – my great-great-grandparents who are indeed the 2C generation.

These common ancestors fall within the expected amount of shared DNA for second cousins, so this aligns well.

My quick-and-dirty tree has revealed at least one pair of common ancestors. Could there be more common lineages? Yes. I would continue building out this quick-and-dirty tree for (at least) another couple of generations on the other lines just to be sure.

What Next?

That depends on what you want to accomplish and your genealogy goals.

I used a DNA match at Ancestry in this example, but your match might be at a different vendor. Regardless, you’ll still want to use Ancestry to build your quick-and-dirty tree based on how they present hints and potential ancestors.

Now that you know how your DNA match connects:

  • Minimally, make a note on the match that indicates the most recent common ancestor(s) identified. I include a link to the quick-and-dirty tree I’ve created.
  • You can add your match and their ancestral path to your common ancestor into your own tree at whichever vendor where the match occurs.
  • If you match at either FamilyTreeDNA or MyHeritage, both of whom provide segment information, I suggest painting your matching segments to DNAPainter.

Painting your segments identifies your matching segments as descending from those ancestors and makes it easier to identify the shared ancestral lineage of anyone else who shares that segment on the same side of your tree (maternal or paternal).

Word of caution here: You can potentially share multiple ancestral paths with any match, so different segments with one match can descend from different ancestors.

  • If your match is at FamilyTreeDNA, you’ll want to link your match to their place in your tree.

Using triangulation, FamilyTreeDNA utilizes linked matches to assign matches who share the same segments to the maternal or paternal side of your tree (or both) using triangulation.

  • You may be trying to break through a brick wall by identifying common ancestors BETWEEN your shared matches that aren’t in your own tree.

This approach is obviously easier the closer your brick wall is in time to the present. Great-grandparents, at the second-cousin level, and great-great-grandparents at the third-cousin level are much easier than 5th- or 6th-generation ancestors who lived before birth and death certificates and detailed census records existed.

Furthermore, the further back in time, the more likely that you may encounter:

  • Pedigree collapse, where the same ancestors appear more than once in your tree
  • Or you share multiple common ancestors with your matches

Of course, there’s always the possibility of endogamy too, where you descend from a historically heavily-intermarried population, such as Ashkenazi Jews or the Amish, for example, which means you may share segments passed down within the population from distant common ancestors you won’t be able to identify. While endogamy in your lineages may increase the amount of shared DNA, which in turn can skew relationship estimates, it won’t prevent you from using quick-and-dirty trees to locate common ancestors.

And finally, unexpected parentage or issues like record destruction may impede your progress, but you’ll never know if you don’t try, which brings us back to the purpose of quick-and-dirty trees.

Building a quick-and-dirty tree is the easiest way to grow your matches’ trees to reveal your common ancestors.

_____________________________________________________________

Share the Love!

You’re always welcome to forward articles or links to friends and share on social media.

Subscribe!

If you haven’t already subscribed, it’s free. You’ll receive an e-mail whenever I publish by clicking the “follow” button at the top of the main blog page, here.

Help Keep This Blog Free

I receive a small commission when you click a vendor link in my articles and purchase that item. This does NOT increase your price but helps me keep the lights on and this informational blog free for everyone. Please click on the affiliate links in the articles or to the vendors below if you are purchasing products or DNA testing.

Thank you so much.

DNA Purchases and Free Uploads

Genealogy Products and Services

My Books

Genealogy Books

Genealogy Research

ECGGC 2026: East Coast Genetic Genealogy Conference – Both In-Person and Virtual

I hope you’ll join me and a whole trove of other wonderful speakers at the East Coast Genetic Genealogy Conference August 21-23 in Boston. The in-person conference is being held at the Embassy Suites at the Boston Logan Airport, so you don’t need to worry about transportation into Boston after arrival.

The great news is that you don’t have to be present to participate, and you don’t have to worry about missing sessions you wanted to attend.

All sessions, except for the Sunday morning ISOGG meeting, are either livestreamed, then available to watch later, or are available on-demand on their scheduled day.

I love this conference because it focuses strictly on genetic genealogy and how to apply it successfully to genealogy. Not to mention, it’s like a family reunion! I can hardly wait to see everyone!

Keynotes

  • Steve Little and Mark Thompson – Friday evening: The AI Frontier in Genetic Genealogy: Where We Are and Where We’re Going
  • Jennifer Zinck – Saturday morning: It Takes a Village
  • Kevin Borland – Sunday Morning: Mining A Chromosome 22 Pile-Up: Clustering Through a Documented Colonial Lineage

Speakers

In alphabetical order, speakers include:

  • Kelli Bergheimer – Understanding Your DNA Health Reports, and, Finding an Ohio Pioneer Family Using Mitochondrial DNA
  • Katherine Borges – DNA and DAR, and, Sunday morning: ISOGG Meeting
  • Kevin Borland – Mining A Chromosome 22 Pile-Up: Clustering Through a Documented Colonial Lineage (keynote)
  • Greg Clarke – Welcome and Introduction
  • Janine Cloud – Turning a Brick Wall into a Community: Using Documents and DNA Together, and, with Roberta Estes: Between the Records and the Results: Tracing Ancestors in Mixed Lines
  • Roberta Estes – Mitochondrial DNA-Z: My Results are Back, Now What?, and, at DNA Academy: Using Ancient Connections to Unlock Genealogy, and, with Janine Cloud:  Between the Records and the Results: Tracing Ancestors in Mixed Lines
  • Mags Gaulden – The DNA of a Revolution
  • Kate Penney Howard – When the Story Isn’t True: DNA and the Family Legend Problem, and, Gerald Hawley and the Silence: What Erased Ancestors Teach Us About DNA Research
  • Daniel Horowitz – MyHeritage DNA Basic Level, and, MyHeritageDNA Advanced Level
  • Peggy Jude – Your DNA Toolkit: Expanding Your Research with Third-Party Tools, and, Step Up to the Plate: Winning Strategies for Connecting with Your DNA Matches
  • Dawn Kosmakos – Unraveling the Identity of Arthur Burton
  • Steve Little – Solving a Paternity Puzzle: AI-Assisted Match List Analysis in Endogamous Appalachia, and, keynote with Mark Thompson: The AI Frontier in Genetic Genealogy: Where We Are and Where We’re Going
  • Melanie McComb – Using DNA to Identify Ancestral Origins
  • Adina Newman – Navigating Your Jewish DNA Results, and, Introduction to DNA Painter: Strategies to Enhance Your Genealogical Research
  • Jonny Perl – Understanding the What are the Odds Tool at DNA Painter
  • Rhonda Roederer – The Power of DNA – Making Life-Changing Connections
  • Diahan Southard – I Did Everything Right. So Where’s My Ancestor?, and, There’s Always a Next Step
  • Jerome Spears – Our Genetic Explorer’s Journey
  • Mark Thompson – Applied Artificial Intelligence for Genetic Genealogists, and, keynote with Steve Little: The AI Frontier in Genetic Genealogy: Where We Are and Where We’re Going
  • David Vance – At DNA Academy: NGS Testing for Autosomal DNA
  • Rob Warthen – Common Ancestors at DNAGedcom – Building Trees
  • Jennifer Zinck – It Takes a Village (keynote), and, Unleash the Power of DNA

You can view the schedule and session information here.

For people attending in Boston, additional activities are being held at the American Ancestors office and library on Thursday.

DNA Academy

Saturday evening, the ECGGC hosts DNA Academy. Each year, this fun, interactive, advanced learning session is hosted by Mags Gaulden and includes a panel Q&A session, and speakers.

From the ECGGC agenda:

Join Mags Gaulden, Dave Vance, Roberta Estes, Rob Warthen, Katherine Borges, and Jennifer Zinck for a Q & A panel with special guests to start, then sit back and enjoy a presentation on NGS testing for autosomal DNA, by Dave Vance, and “Using Ancient Connections to Unlock Genealogy”, by Roberta Estes.

Exhibit and Vendor Hall

There are both in-person and virtual vendor exhibit halls, so visit both if attending in person. Vendors who sponsor this indispensable conference are the ones who keep it affordable for the rest of us, so be sure to stop by their booths.

Register

The conference starts in just a month, but there’s still time to register, here. In-person costs $295 and virtual is $175. Both are great values. I already have my plan in place for which sessions I’m attending in person, and I’ll watch the rest after the conference.

Hope to see you there. Please be sure to say hello.

_____________________________________________________________

Share the Love!

You’re always welcome to forward articles or links to friends and share on social media.

Subscribe!

If you haven’t already subscribed, it’s free. You’ll receive an e-mail whenever I publish by clicking the “follow” button at the top of the main blog page, here.

Help Keep This Blog Free

I receive a small commission when you click a vendor link in my articles and purchase that item. This does NOT increase your price but helps me keep the lights on and this informational blog free for everyone. Please click on the affiliate links in the articles or to the vendors below if you are purchasing products or DNA testing.

Thank you so much.

DNA Purchases and Free Uploads

Genealogy Products and Services

My Books

Genealogy Books

Genealogy Research

Mitotree: First, the Tree – Now the Paper

It’s definitely a red-letter day.

Dr. Paul Maier, the lead author on the new paper Mitotree: The Universal Human Mitochondrial Reference Phylogeny at 10x the Resolution has uploaded the paper to the bioRxiv preprint server, here.

I want to congratulate all of the authors, most of whom are members of the FamilyTreeDNA R&D team as either employees or contractors. I’m a contractor and have had the honor of working with these amazing colleagues on this project since 2020.

About Mitotree

Mitotree was officially “born” on February 25, 2025, and the tree has been updated several times since. About 75% of FamilyTreeDNA’s customers who have taken the full-sequence mitochondrial DNA test received a more refined haplogroup with the release of Mitotree or subsequent updates. Those haplogroups are, on average, 2000 years newer than the person’s legacy Phylotree haplogroup, and some are much more recent.

This means that the tree branches have gotten much, much bushier close to the tips. In other words, lots more twigs and leaves!

Unfortunately, about 25% of testers did not receive a new haplogroup because they do not have any qualifying mutations:

  • Either because they have no additional mutations
  • Or because they have mutations, but they are unstable
  • Or because they have mutations, but no other testers have yet tested that match them to split a branch

The good news is that with the addition of haplotype clusters, everyone benefits from new matching and grouping tools. Testers are grouped into clusters on their matches page, and on the Match Time Tree in Discover, which is much more useful for genealogy.

I know this paper has been a long time coming, but it’s well worth the wait.

Mitotree was a massive undertaking. We began with PhyloTree v17 which had 5,438 hand-curated branches constructed from 24,275 full and partial mitochondrial sequences. Phylotree was last updated in 2016 before subsequently being abandoned.

The Million Mito Team developed Mitotree, a robust phylogeny with more than 54,000 branches formed from over 330,000 complete mitochondrial sequences, of which 177,196 are unique sequences.

Let’s Look Under the Hood

There are three critical pieces of information in those statements.

First, the PhyloTree curation and maintenance was not automated, and a paper detailing their build process, what mutations were included or excluded, and under what circumstances was never published.

Approximately once a year, a new PhyloTree was published where newer samples were individually evaluated and new haplogroups were hand-grafted onto an existing backbone tree.

This methodology did not allow for deep splits to become apparent, because the tree itself was never recalculated. This is exactly how haplogroup L7 went undetected until the Million Mito Team recalculated the tree, including the backbone, in 2022, and published this paper about L7’s discovery.

In other words, while PhyloTree was publicly available, there was no recipe for how it was created or maintained.

Clearly, the tree-building process had to be automated, as hand-curation was unsustainable. There were no academic programs in existence capable of handling the number of samples involved. Not even in 2016 for fewer than 25,000 samples, let alone today.

To maintain haplogroup naming consistency, the first thing our team had to do was write software to phylogenetically reverse engineer PhyloTree v17 to establish a common foundation on which to build. This step was essential for consistency and maintaining the established haplogroup naming pattern.

That software also had to be capable of scaling up exponentially. The first versions took weeks to run, which clearly wasn’t an acceptable long-term solution. Still, being able to establish a foundational backbone to build on programmatically was a victory in and of itself.

Second, PhyloTree used partial sequences, meaning HVR1 and HVR2 samples. Early academic researchers did not perform full sequence testing, so the curators of PhyloTree used what was available to the best of their ability.

With over 330,000 full-sequence samples available today, we no longer include partial samples.

Third, 177,196 of the 331,221 full sequence samples used were unique. Before launching the program to construct the tree, identical samples from known immediate relatives are deduped, when possible, in order to reduce unnecessary clutter and processing time.

This means two things. The actual number of testers is greater than 331,000. But more importantly, anyone who thinks that mitochondrial DNA isn’t interesting should take another look. More than half of the sequences used for tree-building are unique, which handily dispels the myth that mitochondrial DNA doesn’t mutate often enough to be useful for genealogy.

The Mitotree initiative has been both scientifically and genealogically successful beyond anything we could have imagined. The base tree includes approximately 180 branches that are older than 30,000 years, including the discovery of haplogroup L7 at 100,000 years old. These branches both expand and more firmly root the oldest portions of the tree.

Amazingly, haplogroup L7 has living descendants whose earliest known family members are found in Turkey, Saudi Arabia, Yemen, the UAE, Palestinian Territory, Ethiopia, Sudan, and South Africa.

Another fun discovery involved Otzi, the Iceman, a mummy found frozen in the Italian Alps who lived more than 5,000 years ago. He was thought to carry an extinct haplogroup, K1ö, named in his honor, but as it turns out, he’s actually a member of haplogroup K1f, a clade with living descendants in Algeria. Additionally, Otzi now matches four ancient burials too, so he does have cousins.

We couldn’t have made these discoveries without the right people testing, so please encourage everyone and dispel the discouraging myth that mitochondrial DNA isn’t useful or interesting. It absolutely IS, and the success stories keep rolling in!

Why Build a Phylogenetic Tree?

Simply put, the history of our ancestors, both recently and reaching back into ancient history, is revealed in the tree – and there’s absolutely no other avenue to reach this information. Ironically, it’s readily available to everyone because everyone has mitochondrial DNA and can easily take the test.

Mitochondrial DNA is different than Y-DNA, which has its own phylogenetic tree based on SNP mutations, and autosomal DNA, which has no tree.

The reason that both Y-DNA and mitochondrial DNA can have phylogenetic trees is that they are inherited from the appropriate parent with only occasional mutations, while autosomal DNA is roughly halved in each generation.

Y-DNA is inherited by males only from their fathers, with no admixture from their mother, while mitochondrial DNA is inherited by everyone from only their mothers, with no admixture from their father.

Autosomal DNA is inherited through random recombination, with half coming from each parent, except for the X chromosome which has its own inheritance pattern. X-DNA is often confused with mitochondrial DNA, but they are entirely different types of DNA. I wrote about that here.

No tree is possible for autosomal DNA, because it gets diced and riced in each generation.

The mutations that occur occasionally and randomly in both Y and mitochondrial DNA form a trail of breadcrumbs leading backward in time, or in our case, they form both the trunk and branches on the tree.

Those unique mutations, once they occur, are inherited by subsequent generations, forming a path back in time.

In current generations, those mutations provide testers with the ability to identify our closest cousins who inherited those same mutations and who have taken either a Big Y-700 test, in males, or a mitochondrial DNA full sequence test for everyone.

In this conceptual example, you can see that Ancestor 1 carries mutation A, as do the next two generations who inherited it from their parent. However, Ancestor 4 now has additional mutation B, so that person carries mutations A+B. This inheritance pattern continues through the apricol lineage as mutations C and D are added in subsequent generations, until “You” are born with A+B+C+D.

Your cousin’s ancestor, on the other hand, was also born to Ancestor 4 and carries both A+B, as seen in the green column. Three generations later, that line added mutation F. Your  ancestor 7 added mutation C, so now the apricot and green lineages can easily be genetically distinguished from each other.

When a living person tests, we immediately know, based on the combination of their mutations, if and where they fit in this lineage, because both the apricot and green branches have accumulated unique mutations that the original blue Ancestor 4 and earlier ancestors did not have.

Using our knowledge of the tree branches, when and where they occurred, provides valuable genealogical information, along with fascinating Ancient Connections, both since and prior to the adoption of surnames.

Both Y-DNA and mitochondrial DNA can reach much further back in time than autosomal DNA because they are not diluted with DNA from the other parent in each generation.

So mitochondrial DNA is both broad, meaning many leaves, and deep, meaning it helps us look straight back in time like a laser sight, all the way to the common ancestor of all humanity, Mitochondrial Eve, who lived about 140,000 years ago in Africa.

Mitochondrial DNA Presents Unique Challenges

Mitochondrial DNA presents challenges not found in Y-DNA tree building.

For example, mitochondrial DNA only has 16,569 locations available to utilize, while Y-DNA currently uses roughly 22 million “gold standard” locations on the Y chromosome.

Of those 16,569 mitochondrial locations, some are not reliable enough for tree-building.

Unreliable mutations include:

  • Insertions, where extra copies of a particular nucleotide (Thymine, Adenine, Cytosine and Guanine) have been inserted at a specific location. Those are indicated by designations such as 309.1C where 309 indicates the marker location, .1 indicates the number of insertions at that location, and C (for Cytosine in this example) indicates the nucleotide inserted.
  • Heteroplasmies occur when multiple nucleotides are detected at a specific location. They are reported by a different letter than T, A, C or G, depending on which of multiple nucleotides are found. Heteroplasmies tend to “come and go” based on detection and threshold levels, so they can’t be used the same way as more stable mutations for tree building – and are often, but not always, unreliable for genealogy. I wrote about this in the article, What is a Heteroplasmy and Why Do I Care?.

Those locations and types of mutations have been excluded from forming tree branches, or downweighted, because they are too prone to mutating back and forth. However, they *might* be useful for genealogical purposes. Less-than-reliable mutations are now used to create haplotype clusters, even though they aren’t used to create new branches on the Mitotree.

I wrote about how haplogroups and haplotype clusters are formed in these articles:

Weighting and Confidence Factors

Mitotree formation would have been a lot easier if delineations, meaning inclusions and exclusions, were clear, either yes or no, but they aren’t.

Some were obvious from the get-go, such as insertions at location 309 and elsewhere, but other situations were much less obvious.

For example, sometimes there’s a specific location that seems prone to reversion, mutating back and forth, meaning that it mutates, then returns to its original state, then repeats the process.

Reversions are a natural phenomenon that occurs frequently in mitochondrial DNA, but is rarely, if ever, found in Y-DNA.

Let’s look at an example.

Courtesy Dr. Paul Maier

How many reversions at the same location are too many, especially if they are close in the tree?

In the above example, the mutation from A to G occurs just below the first arrow, forming haplogroup L1, a branch of L. The red areas all carry that mutation, subsequently forming eight new branches.

However, one step downstream from that mutation, just above the second arrow, location 7055 back-mutates, or reverts to A from G, which is indicated by the “!”. That reverse mutation forms haplogroup L1c3.

If location 7055 continues to flip back and forth between A and G, at what point do we have less confidence in that location, and at what point should a location be excluded from the tree and prevented from creating or dividing a branch?

The answer is that “it depends,” sometimes on the branch, sometimes on the “group” of other mutations it’s found with, and other factors. Some locations are stable in some parts of the tree, but unstable in others. We certainly never expected to see that!

This means the team had to design and build a weighting methodology so that relevant mutations, such as reversions, are not summarily excluded from tree building but instead carry different confidence weighting levels, depending on the circumstances.

Some samples, such as ancient DNA, were down-weighted in general due to their propensity to contain artifacts resulting from deterioration. Ancient samples can still influence branching, just not as much as a high-quality modern sample.

Furthermore, especially when utilizing academic samples, results with a high number of heteroplasmies are excluded, along with those with ambiguous reads and missing upstream mutations, which were previously inferred with PhyloTree. Academic samples vary in quality and age, and we have no way of knowing which quality criteria were used by that lab at that time.

These types of variances made constructing and updating the Mitotree more challenging than the Y-DNA tree, which is not subject to weighting, resulting from phylogenetic tug-of-war between mutations.

In some situations, the addition of just one test can make the difference between a new branch, or no branch, in a subsequent run of the tree. Due to this type of scenario, and fine-tuning the algorithm, some people’s new haplogroups have reverted to an earlier haplogroup in subsequent Mitotree updates.

The paper and supplemental materials provide details about the exclusion process, types of exclusions, and a list of excluded marker locations.

You can view the confidence of any haplogroup in the Classic Mitotree view in Discover.

My haplogroup, J1c2f, is formed by the mutation G9055A, and you can see that the confidence rank is 7.5 out of 10.

Mousing over the little up-arrow tree icon beside the star explains changes in nearby branches, which can affect the haplogroup’s confidence ranking.

Branches are not renamed for convenience, and only when phylogenetically warranted. Existing haplogroup names used either on PhyloTree, in academic literature, or previously on the Y-Full tree are either maintained or avoided to eliminate potential confusion. No one wants two different haplogroup names depending on which tree is being viewed.

Previously obsoleted names remain permanently obsoleted and are not reused.

The paper explains further about technical corrections and tie-breaker situations. In some cases, potential branches with equal or near-equal weighting are flagged for team review.

Amazing Discoveries

I encourage everyone to read the section in the paper beginning with “Notable discoveries.” These aren’t people, as in Discover’s Notable Connections, but scientific accomplishments achieved with the new Mitotree.

Our knowledge of human migration within and out of Africa has been greatly refined, as well as the ancestral path into and across Eurasia, Asia, and into the Pacific Rim. If you have unusual mitochondrial haplogroups such as L, M, N, P, Q, R or S, you’ll absolutely want to read this.

Of course, in time these haplogroups branch and become Paleolithic haplogroups, then the Gravettian-Mesolithic followed by the Hunter-Gatherers found throughout Europe that we are familiar with. We’ve learned a great deal from rare ancient DNA samples that anchor more modern haplogroups in a place and time, and inform us of migration patterns as well as how now-extinct ghost populations gave rise to current ones.

The earliest humans, whom Mitotree has more firmly anchored, formed a trickle out of Africa that became a bifurcated stream, eventually flowing across the rest of the world. What recorded and even archaeological history cannot tell us can be and is revealed through the patterns held in our DNA today – and Mitotree is our map to read them. Common ancestors are found where our mutations as haplogroups converge, joining as we travel backward in time, piercing an otherwise impenetrable veil.

For those with Native American ancestry, Mitotree expands the two-wave theory, refining it into five or six probable migration surges, depending on how you count, based on a combination of haplogroup ages and distribution.

Summarizing from the paper:

The first wave of haplogroups A2, B2, C1b, C1c, C1d, D1, and D4h3a arrived from Asia, across Beringia or along the Pacific Corridor, about 17,000 to 18,500 years ago, and expanded along the Pacific coast. D4h3a is found almost exclusively in the Pacific region.

This was followed by haplogroup C4c about 15,800 years ago and X2a about 10,000 years ago, which expanded into the interior through the ice-free corridor east of the Rockies after the ice melted.

Next were the Paleo-Eskimo and Na-Dene speakers in haplogroups A2a, D2a, D2b, D2c/D3, and D4b1a2a1a2, who, between 3000 and 7000 years ago, made their way from Alaska, across the polar regions of Canada, into Greenland.

Na-Dene speakers, Apache and Navajo, in haplogroups A2a and B2a made their way southwest between 1300 and 1500 CE, or between 500 and 700 years ago.

Last, the present-day Inuit-Yupik expanded from Beringia to Greenland about 1000 CE.

For additional information, please see the Native American lineages section of the paper.

Mitotree has also clarified the ancestors of the Ainu/Jomon people from Hokkaido, Japan, and their ancient Paleolithic northwest Asian and Siberian relatives. The ancestors of this group and Native Americans share even earlier Asian ancestors.

The history of the Jewish people has been significantly refined as well, expanding on earlier works, and is found in the Counting the newest Jewish founders section of the paper.

  • 43% of Ashkenazi Jewish testers fell into 5 founding lineages where they had no subclades before, but they do now.
  • Two clades of haplogroup K have now been split 4000 to 5000 years ago in Romania.
  • There’s new information about the crypto-Jewish community in Portugal, Mountain Jews from Persia and the Caucasus, plus Jewish groups in India, Georgia, Azerbaijan, Israel and Libya.
  • Additionally, haplogroup M33c9b tells the story of Ashkenazi Silk Road merchants who traveled between China and Europe.

The paper reports the isolation of Sardinian-specific haplogroups and provides substantially greater structural definition for the Saami people, increasing from 22 subclades to more than 300.

The Notable discoveries section is chock full of information.

Genealogy Jump-Start

Today’s tree is ten times larger than the 2016 tree, and will continue to grow as more people take a full sequence mitochondrial DNA test, available at FamilyTreeDNA.

The greatly improved tree alone is not the only facilitator of genealogical success. A dozen reports, including Haplotype Clusters and the Match Time Tree are provided for all full-sequence testers in Discover. I wrote about how to effectively use your matches and Discover to break through genealogy brick walls, here.

There are a couple of things you need to do to increase your opportunities for success and to help Discover and Mitotree.

Genealogy is a team sport, and you can increase everyone’s success rate by completing (and updating) your Earliest Known Ancestor (EKA) and location information, found under “Account Settings” beneath your name in the upper right hand corner when signed on, then “Genealogy”, then “Earliest Known Ancestor”, and by providing a family tree or a link to WikiTree.

Identifying common ancestors is what testing is all about, and these are all important success factors. Everyone wants to identify previously unknown ancestors.

Mitotree is More Than Genealogy

Of course, as genealogists, we’re focused on how to use the new Mitotree information, paired with Discover, to identify brick-walled ancestors and learn more about them. I’ve written specifically about how to do that in these two articles:

Mitotree isn’t just an explosion for genealogy, though – it’s an incredible scientific achievement. Instead of genealogy benefiting from other specialties, now they can benefit from what genealogy has wrought.

Mitotree presents opportunities to rethink and potentially recalculate dating and information in other fields, such as archaeology, medical genetics, forensics, and history.

We know vastly more than ever before, but this is only the beginning.

With each new tester and every ancient genome added to the growing body of evidence, our understanding becomes more refined, revealing insights about our ancestors, and weaving our thread into the broader tapestry of human history.

_____________________________________________________________

Share the Love!

You’re always welcome to forward articles or links to friends and share on social media.

Subscribe!

If you haven’t already subscribed, it’s free. You’ll receive an e-mail whenever I publish by clicking the “follow” button at the top of the main blog page, here.

Help Keep This Blog Free

I receive a small commission when you click a vendor link in my articles and purchase that item. This does NOT increase your price but helps me keep the lights on and this informational blog free for everyone. Please click on the affiliate links in the articles or to the vendors below if you are purchasing products or DNA testing.

Thank you so much.

DNA Purchases and Free Uploads

Genealogy Products and Services

My Books

Genealogy Books

Genealogy Research

Ancient Connections: Where Archaeology Meets Your Ancestors

Ancient Connections, a report found on FamilyTreeDNA’s Discover platform for both Y-DNA and mitochondrial DNA (mtDNA), can be used in multiple ways to enhance your genealogy and unlock secrets.

It’s exciting to examine ancient burials linked to our ancestors and understand how we connect to them. Ancient Connections offer a wealth of information, providing clues that can help unravel long-standing mysteries.

Today, there are more than 12,960 Y-DNA Ancient Connections in Discover, along with more than 25,310 mitochondrial Ancient Connections, and that number increases weekly.

Why the disparity, you ask? Remember, everyone has mitochondrial DNA, but only males have Y-DNA.

In addition to matches, your DNA results hold something even more powerful – evidence of where your ancestors and their cousins lived in the distant past, when they lived, and the cultural context surrounding them. These essential insights are unavailable through any other means. Ancient Connections help us answer the age-old question, “Where did I come from?”

Could These People Be My Ancestors?

I’ll show you how to answer another question, too. Which of these Ancient Connections could potentially be your ancestors, and which ones are your “haplo-cousins”?

Regardless, they all help us understand our ancestors’ past, and that of their descendants.

Discover is for Everyone

FamilyTreeDNA provides a free version of Discover that everyone can use. There’s also an enriched version with additional information for their customers who have purchased Y-DNA and mitochondrial DNA tests.

Discover has something to offer for everyone.

Mitochondrial DNA is passed from mothers to all of their children of both sexes – unmixed with the DNA of the father.
Everyone has their mother’s mitochondrial DNA, which is passed intact, except for an occasional mutation, directly down through generations of mothers. It’s not admixed like autosomal DNA, so we don’t lose some portion in each generation. This is exactly why we can track mitochondrial DNA infinitely far back in time and why it’s so crucial for understanding the origins of your mother’s specific line.

Y-DNA is passed from fathers only to their sons, which is what makes males male. Like mitochondrial DNA, Y-DNA is not admixed with any DNA from the mother, so we get a laser line-of-sight view of the direct patrilineal line back in time. The Y-DNA direct paternal line is the male’s surname line in cultures where males carry their father’s surname.

If you’ve tested at or upgraded to either the Big Y-700 level or the mtFull, full mitochondrial sequence test, you will receive the most granular haplogroup possible, meaning the closest in time and most informative. You’ll also match with other testers who have taken the less-refined lower-level tests.

The most informative and precise results occur when both people have taken the premium tests. As more people test and science advances, you may receive a new haplogroup from time to time when you and another tester share a rare mutation – so these tests are evergreen.

Both Y-DNA and mitochondrial DNA testers at any level have access to Discover on their dashboard for those products, although the results of lower-level tests provide less information.

The Free Version of Discover Compared to the Premium Version for Testers

Here’s a comparison of lower-level Y-DNA tests and the Big Y-700.

Click any image to enlarge

Y-DNA testers who have only taken the 12-111 STR panel tests receive a predicted haplogroup, and when clicking through to Discover, receive up to 10 Ancient Connections.

For example, If your Y-DNA haplogroup is predicted as R-M269, the most common male lineage in Europe that arose some 6450 years ago, your Ancient Connections begin with the closest genetic match to R-M269. Viewing Ancient Connections that are 6500 years ago will certainly be interesting, so please do look, but probably not terribly useful for genealogy.

However, if that same person were to upgrade to the Big Y-700, they would receive a much more recent haplogroup, and along with it, up to 30 Ancient Connections within their major haplogroup lineage, R in this case, plus the oldest sample in the database. For some haplogroups, there may not yet be 30 Ancient Connections, although new ancient samples are added weekly for both Y-DNA and mitochondrial DNA.

All Ancient Connections begin with the matches who are genetically closest to the haplogroup requested.

The same scenario holds true for mitochondrial DNA testers who previously tested at the HVR1/HVR2 level, but not at the full sequence level, which is the only test available today.

This article focuses on testers at the higher levels, meaning the Big Y-700 and the mtFull tests, and how to utilize their 30 closest Ancient Connections. We’ll walk through step-by-step examples using both.

However, before we begin evaluating our Ancient Connections, we need to cover two fundamental concepts.

BCE, CE and Converting to “Years Ago”

It’s helpful to understand date structures and how they are used.

It’s easy to get confused when seeing the dates of CE, current era, and BCE, before current era, which means we misinterpret the information.

For example, the year 100 CE is the year 100 that occurred roughly 1900 years ago. We round 2026 to 2000 for these types of calculations. The year 100 BCE, before current era, occurred approximately 2100 years ago. I often prefer to work in “years ago”, because it equalizes the numbers, meaning you’re less likely to get confused about how long ago someone lived or something happened.

To do the calculations from BCE dates to “years ago,” add 2000, so 2250 BCE equals 4250 years ago.

For CE dates, subtract from 2000. The date 500 CE occurred 1500 years ago.

This can be especially confusing when you’re dealing with the same number on either side of the current era, which began in the year 1. There is no year zero. For example, we need to be vigilant not to confuse 500 BCE, which was 2500 years ago, and 500 CE, which was 1500 years ago.

Now, on to our second concept.

Haplogroup Age and Burial Age Are Not the Same

When viewing Ancient Connections, the genetic age of the haplogroup, meaning when it was formed, and age of the burial are two different things.

Haplogroup R-ZP18 is about 4250 years old, and this Late Iron Age, pre-Roman burial which is also R-ZP18, occurred about between 2337 and 2043 years ago.

Haplogroup ages and the date they emerged, which show on the Timeline, sometimes mature and are refined with additional testers and branching.

Burials are dated using various techniques, and sometimes the ages provided in the academic papers are earlier than the genetic age of the haplogroup, shown on the Timeline at the bottom of the Connections page.

Discover makes no attempt to “fix” this situation, because it’s unclear which age should be changed. It’s not unusual to be unable to fully analyze ancient remains. For example, let’s say a sample is determined to have the SNP for R-ZP18, but simultaneously lacks downstream SNPs and some upstream SNPs, and the burial was dated from surrounding soil or artifacts. In that case, it would be impossible to know what is precisely “accurate”, but the sample is accurate enough to be included in Ancient Connections. This is also why some samples aren’t included in Globetrekker™ calculations. Some low-quality samples are excluded entirely.

Every ancient sample is individually analyzed by R&D team members before being included in the phylogenetic tree and Ancient Connections. Sometimes, the scientists at FamilyTreeDNA can assign a more specific haplogroup than was available to the paper authors at the time of publication because the tree has since branched.

As you receive new Ancient Connections, your older ones, except your final or oldest connection, will roll off of your list.

That’s one reason I devised a process for analyzing and recording my Ancient Connections, and for determining which ones might be actual ancestors – or at least aren’t precluded from it.

First Peek at Ancient Connections

Sign in to your FamilyTreeDNA account and click on the Discover link on the dashboard for the type of test you wish to view.

In the Y-DNA example, I’m using my male Estes cousins. As a female, I can’t test for the Estes Y chromosome, so I recruited others to represent my line. You can see the results in the Estes DNA project.

After signing in, click on Discover, then on Ancient Connections.

Y-DNA Ancient Connections 

It’s a bonanza!

Your Ancient Connections are displayed at the top of the page, ordered from genetically closest to most distant. These are archaeological samples whose data has been extracted from academic papers and analyzed before being include in Discover.

You’ll see a description of the first sample, or any sample you click on. The Timeline for that sample, along with your haplogroup and your common ancestor’s haplogroup, is displayed at the bottom of the page.

The first, meaning closest, Ancient Connection is highlighted, so let’s take a look.

  • “You” are shown in the dark purple frame (with purple arrows) at right, with your haplogroup, in this case R-ZS3700, which is placed on the Timeline at the bottom of the page in the appropriate location.
  • The Ancient Connection named “North Berwick 16499”, whose name was taken from the academic paper in which it was found, is shown in a red frame and placed on the timeline based on information provided in the paper.

“North Berwick” has been assigned to haplogroup R-ZP18, either in the paper, or by the FamilyTreeDNA R&D team if a more refined haplogroup can be determined, and is this tester’s closest Ancient Connection based on its position on the list.

Note that you may have other Ancient Connections who are genetically equivalent in age, meaning they too would be R-ZP18. In our case, only one sample is assigned to that haplogroup.

  • Your Shared Ancestor, in the green frame, is the first man who carried R-ZP18, which emerged about 2250 BCE, or 4250 years ago.

Notice that I said, “the first man.” That man’s sons, grandsons and so forth were also haplogroup R-ZP18. Some went on to develop new downstream haplogroups, but apparently, North Berwick, by the time he lived, had not. Either that, or a downstream haplogroup cannot yet be determined due to a lack of other testers in that lineage.

Men with downstream SNPs (mutations), meaning downstream haplogroups, also descended from R-ZP18. Those SNP mutations become downstream haplogroups when two or more men who carry the same SNP mutation match each other. For example, our Estes ancestor who carries haplogroup R-ZS3700 descends from R-ZP18 through a distinct series of downstream SNPs (mutations). While we carry R-ZP18 in our lineage, it’s not our most refined haplogroup.

However, for North Berwick, haplogroup R-ZP18 is his most refined haplogroup.

Because of this, we know for sure that North Berwick and the Estes men both descend from the original R-ZP18 man who lived about 4250 years ago, but we can’t tell when they shared a common ancestor between 4250 years ago and 3750 years ago when the next downstream haplogroup R-BY342, was formed in the Estes lineage.

Because North Berwick does not belong to a different downstream haplogroup, it’s genetically possible that the Estes men could descend from him during that 500-year timeframe. There’s nothing to exclude that possibility based on his haplogroup alone, but looking at when North Berwick lived is another matter.

North Berwick lived between 2337 and 2043 years ago, which is 1400 years LATER than when the first downstream haplogroup, R-BY342 was formed, about 3750 year ago, in the Estes lineage. This precludes North Berwick from being our direct ancestor. Instead, he’s our “haplocousin.” We share a common upstream ancestor.

What we absolutely CAN confirm, though, is that between 500 and 1300 years earlier than North Berwick lived, between when haplogroups R-BY342 and R-ZP18 were formed, both North Berwick and our Estes ancestor descended from the same man.

This kind of information is like waving a red flag in a genealogist’s face. We immediately need to know more.

This is just the beginning, and we have so many questions!

Revealing More Information

Did our common ancestor live in or near North Berwick, or someplace else? What do we know about the history of North Berwick?

What can we discern about North Berwick?

  • When did this man live, and where?
  • What do we know about him?
  • Who was he?
  • Did he live close to where my earliest known ancestor in this line is found?
  • What can I tell about his culture?
  • Were there grave goods that provide at least a peek into his life?

So many questions!

Discover tells us that he lived between 337 and 43 BCE, so between 2337 and 2043 years ago, during the Late Iron Age, and is associated with the Iron Age Britain cultural group.

The Ancient Connections “Reference” provides information about the paper where the North Berwick sample was found. No links are provided because sometimes the paper is behind a paywall, and you can’t access it without paying, and sometimes it’s a preprint and will appear later elsewhere. Sometimes one paper actually uses data from an earlier paper, and it gets complicated.

The first thing I do is Google the paper – Patterson et al. 2022. Google provides two links – one that’s free, and one that isn’t. Many times, the sample data is found in the supplementary material, which may also be behind a paywall, even if the paper isn’t.

I know you’re going to think it’s a pain, but I strongly encourage you to read every paper, though sometimes they can be challenging to understand, so read them when you’re fresh, not tired, and can concentrate. If nothing else, at least read the abstract. There’s so much great information buried in academic papers, including nice maps and discussions of the burial site. You can also learn more sometimes by Googling the burial site itself.

Let me give you an example from this paper’s abstract. I’ve added the brackets [ ] for clarity, from the body of the paper:

Between 1000 and 875 BC[E], EEF [Early European Farmer] ancestry increased in southern Britain [England and Wales] but not northern Britain [Scotland] due to incorporation of migrants who arrived at this time and over previous centuries, and who were genetically most similar to ancient individuals from France. These migrants contributed about half the ancestry of people of England and Wales from the Iron Age, thereby creating a plausible vector for the spread of early Celtic languages into Britain.

How does this information align with our North Berwick man? He lived between 2337 and 2043 years ago, and the EEF ancestry increased in southern Britain between 3000 and 2875 years ago. The authors do add “over previous centuries” which probably accounts for the 500-year gap and gets closer to when R-ZP18 lived. North Berwick is found in Scotland, not England or Wales, so not part of the group of people most closely aligned with the ancient French migrants from this timeframe. Maps in the paper confirm this as well.

Googling the paper and sample name provided additional sourced information. This paper incorporates samples from earlier papers and performed a different type of analysis.

Ironically, I wrote about this in detail in 2022, here, before Discover was introduced, so I had absolutely no idea that North Berwick 16499, discovered on Law Road in North Berwick, was related to my ancestors, and therefore, to me.

In that article, I researched and mapped the samples. North Berwick 16499 is located on the coast, along the harbour, not far from Edinburgh.

The burial was excavated in the cemetery of the original St. Andrew’s Church in North Berwick, originally built in the 1100s, but now in ruins.

This paper’s supplementary material explains that:

Excavation of a substantial square cist at Law Road, North Berwick, uncovered the remains of four inhumations of Late Iron Age date (Richardson et al. 2005). Two adult males 3603 (Skeletons C46 and C51) and a female around 16–18 years of age at death (Skeleton C50) appeared to have been displaced for the burial of an adult female (Skeleton C47), wearing an iron brooch. One of the males (C46) had been buried with a bone-handled iron knife.

What I wouldn’t give to see that iron brooch and bone-handled knife.

C51 is North Berwick 16499, “our” skeleton. A cist grave is a small, stone-lined burial box, and this one was preserved beneath medieval deposits.

That reference gave the even more precise location of Law Road and St. Andrews Street and informs us that the remains are held by National Museums Scotland. Checking their collections confirms that they hold these items, plus the bones. However, there are no photos shown. Contacting them for images might yield results.

What the paper did not say is that little was known prior to these excavations about early North Berwick.

By Stefan Schäfer, Lich – Own work, CC BY-SA 3.0, https://commons.wikimedia.org/w/index.php?curid=19450589

North Berwick was known to exist as a ferry landing from the 7th century, but an archaeological survey of Berwick Law, a hill that overlooks the town, revealed much earlier information:

The earliest features on North Berwick Law comprise a pair of newly discovered cup-marked rocks and the scanty remains of a prehistoric hilltop fort discovered by RCAHMS (1957, xv), whose outworks appear to be more limited than suggested by previous authorities (Feachem 1963, 119; OS 1975). The lower SW flank of the Law is dotted with the remains of a prehistoric settlement comprising at least 12 hut circles or house platforms and fragments of an associated field system of small cairns and banks.

Unfortunately, the perimeters of Berwick Law have been settled and farmed since, and the hilltop has served recently in the same capacity as it probably served initially – as a lookout across the firth. The residents would have been watching from this highest point for invaders arriving by sea.

It’s about half a mile from the foot of the hill to the burial cist.

The survey also mentioned that they found “stray bronze age finds” that had likely been disrupted by subsequent settlement. The bronze age in Northern Scotland began about 4200 years ago, about the time that R-ZP18 lived, until about 2800 years ago. Whoever North Berwick 16499 was, the man who was buried here some 2400 years ago, he was probably associated with this hilltop fort, perhaps farming at the base, probably living in one of those huts or nearby. His body wouldn’t have been taken far for burial.

We are left to wonder how long his family had lived here, and how they had arrived. Was his cist burial a sign of status? Was he sent to commend the fort, or had his family settled here centuries earlier? Did our ancestor descend from this location, too?

After our analysis, we know that our ancestor did not descend from North Berwick 16499 himself, but North Berwick definitely descended from our ancestor.

If you’re thinking this is a rabbit hole, it definitely is – but what a rabbit hole! There is so much to be gleaned from these Connections.

The Evaluation Process

I needed a process to keep track of these Ancient Connections, my findings, and how they relate to my Estes ancestors. Who begat, or might have begat whom, and where?

I created a spreadsheet as I read and analyzed each Ancient Connection relative to my ancestral line. I include what I know about it, and what I THINK I know about it. Those can be two vastly different things. I follow this same process for every ancestral line where I can find a representative Y-DNA or mitochondrial DNA tester.

For example, there’s a persistent rumor that the Estes family line descends from the d’Este family of Italy. That rumor was spun up long before we had genetic proof that our line was found in Kent, England, in records dating back to about 1495. Fortunately, church records, for the most part, and some civil records still exist.

The first known record is the will of our Nycholas Ewstas written on January 1, 1533/1534 in Deal, Kent, England. We confirmed that this is our Estes line by testing the Y-DNA of his descendant who still lives a few miles up the road, compared with the descendants of Abraham Estes (1647-1720), the man who immigrated to Virginia in 1673. We believed that Abraham Estes, who married in 1672, then immigrated 14 months later, was one and the same person.

Based on the details of the d’Este rumor, the Estes line was supposed to descend from one Francesco d’Este (Esteuse), an illegitimate royal son, exiled to France about 1471 after the death of his father, Azzo VI of Este, by a jealous half-brother, complete with a royal allowance. There are mentions of him in the Dutch and French courts, then nothing. Silence.

Apparently, various Estes lines in England liked the idea that he crossed the English Channel and settled in the fishing village of Deal, with his descendants carrying the surname Estes, a derivative of d’Este. King James apparently believed there was a connection and made that suggestion himself in one instance, although it’s unclear if that Estes man was from our Estes line.

It’s difficult to prove a negative, so we need to rely on the evidence we do have, much of which has been discovered and accumulated in more recent years, since the genesis of that rumor which was widely believed.

To begin with, it makes no sense that between 1471 and 1495, the family suddenly went from being a wealthy exiled royal circulating at court in France and the Netherlands, to peasant fishermen on the coast across the channel.

There is a legitimate royal lineage that does descend from the d’Este family in Italy, but until and unless someone who is a descendant of the direct male line of the House of Hanover, which reaches back to the Azzo line of Ferrara, takes the Y-DNA test, there’s no proof positive. Either their Y-DNA would match the Estes line, or not. I’d wager that it does not, but I’d love to find out for sure.

I’m hopeful that some nugget in Ancient Connections might add weight to either side of the argument.

Creating a Spreadsheet

First, I’ll show you the Ancient Connections spreadsheet built for the Estes line, then I’ll demonstrate how to build it.

Here’s the finished spreadsheet. Every haplogroup’s spreadsheet will be different.

I placed the four confirmed Estes haplogroups at the bottom because that’s the base from which the Ancient Connections are built, beginning with the closest Connection first.

“My” haplogroup, meaning for my ancestor’s Estes male line, is R-ZS3700, but there’s one additional downstream haplogroup, which I’ve included for completeness.

Let me alert you now that you WILL receive new Ancient Connections, which means that for every new Connection you receive, one more distant Connection rolls off the end because it’s outside of your 30 genetically closest Connections threshold. I’ve received new Ancient Connections in the past three months, between the time I originally began gathering this information and when I published this article.

The underlying message, in addition to maintaining your spreadsheet, is to set a calendar alert to check your Ancient Connections regularly. One rolled off that was more distant genetically, but was located only 10 miles away from where my Estes ancestors originated in Deal, England.

We’ll build the spreadsheet so you can easily expand it as new Connections are added.

Also, note that you may receive multiple matches from the same archaeological excavation site, which, of course, is highly suggestive of a family. If the multiple burials are in the same exact location and from roughly the same timeframe, I only record them on the spreadsheet once to reduce clutter, but I add a note that there are multiples.

The Build Process

Referencing the image above, haplogroups in the column directly above the originating haplogroup, R-BY154784, then R-ZS3700, colored apricot, are parent haplogroups – meaning that these haplogroups descend from the haplogroups above them. Look at R-ZP18, North Berwick, above R-BY482 as an example. This means two things.

  1. It’s possible that my ancestors could descend from these individuals in this column. However, all things considered, it’s more likely that they are a “cousin” of my ancestor who lived at that time and carried that haplogroup before a new mutation happened and branched into a new downstream haplogroup. That’s exactly what we proved about North Berwick based on when he lived and our downstream haplogroup formation date.
  2. Every man who shares that haplogroup, R-ZP18, absolutely DOES descend from the original man who carried that haplogroup-defining mutation that arose about 2250 BCE or about 4250 years ago. That one man in whom R-ZP18 occurred is noted above North Berwick, in red, indicating that both North Berwick and the Estes men descend from the man whose name is now R-ZP18.

On my spreadsheet, I’ve colored the cells of the haplogroups that I do descend from, and the burials I might descend from, apricot. The common haplogroups that burials and contemporary testers downstream descend from are in bold red text (R-ZP18 and R-DF49).

Burials who carry a different branching haplogroup, meaning they aren’t R-ZP18, but branch FROM from R-ZP18, are shown with their branches in blue. My ancestors cannot descend from blue haplogroups because we are on different branches of R-ZP18. Our branch is apricot.

Let’s add the next Ancient Connection.

Here’s the Time Tree Timeline of the second Ancient Connection, named Mount Pleasant 746, found at All Saints, Cambridgeshire, England, who lived between 940 and 1365 CE.

This shows two things.

  • My R-ZS3700 ancestor cannot descend from the Mount Pleasant burial, since R-ZS3700 doesn’t carry the mutation for R-BY173525, found in the Mount Pleasant burial.
  • However, since R-BY173525 branched from R-ZP18, we DO SHARE a common ancestor who lived about 4250 years ago. This means that between 4250 years ago and 940-1385 CE, the man found in Cambridgeshire, and my ancestor found in Kent around 1495 CE, both migrated in different directions from where their common ancestor, R-ZP18, lived, wherever that was.

The next closest Ancient Connection is Vor Frue Kirkegård 336, buried in the yard of a former monastic church in Vor Frue Kirkegård, Aalborg, Denmark, which dates from the 12th century. This man lived between 1536 and 1806 CE.

Again, my Estes ancestor who carries R-ZS3700 can’t descend directly from this man. Three things preclude Vor Frue Kirkegård 336 from being our ancestor:

  • The fact that Vor Frue Kirkegard 336 carries R-BY203953, but the Estes line does not.
  • Vor Frue Kirkegard 336 does not carry, R-BY342, the next downstream SNP for the Estes line.
  • Vor Frue Kirkegard 336 lived between 1536 and 1806 CE, which is contemporary with or after the earliest documented Estes ancestor was living in Kent, England circa 1495.

In this case, the locations are not in close proximity, over 500 miles apart by a combination of land and water. This distance would be less compelling as an elimination factor if the men were further separated by time.

In this case, any one of the first three pieces of evidence, alone, would preclude Vor Frue Kirkegard from being our ancestor.

Once again, R-ZS3700 shares the common ancestor of R-ZP18 with Vor Frue Kirkegård 336, along with Mount Pleasant 746 and North Berwick 16499. All of those men shared one common ancestor 4250 years ago.

Now, we have the bottom portion of our tree built out – meaning everyone who either carries haplogroup R-ZP18 as their primary haplogroup, or descends from that man.

Moving up the tree in the apricot column, you’ll notice that I’ve left spaces that leave room for the branching haplogroups in blue on the right. You won’t know how many spaces you need or the configuration until you start building the tree in your spreadsheet.

I listed both “5 haplogroups” and “3 haplogroups,” in the apricot column. You can spell those haplogroups out if you wish, but for my Ancient Connections, they didn’t matter. They may matter in the future, though, if you have an Ancient Connection who descends from or branches from one of them.

If you need an easy way to determine your ancestral lineage, the Ancestral Path is just the thing for you and will help build your spreadsheet.

Your Ancestral Path

It’s easy to view which haplogroups are in your direct ancestral line. Just click on the “Ancestral Path” link in Discover’s sidebar.

Your haplogroup is shown at the top, with the parent haplogroups in order beneath. I’ve boxed the “5 haplogroups” between R-BY482 and R-ZP18 here, and then the “3 haplogroups” between R-ZP18 and R-DF49, which is where we find the next closest Ancient Connections.

One bonus of the Ancestral Path display is that you can see how many Ancient Connections are in the database for each haplogroup, at far right.

As I continue to build out my spreadsheet, the next four burials are all R-DF49, a haplogroup that was formed about 4400 years ago. Three of those burials are in England, and the fourth is in the Orkney Islands. They are all apricot, meaning:

  • They don’t carry any downstream haplogroups
  • They all descend from R-DF49
  • Based on haplogroups alone, nothing precludes the Estes line from descending from any of those men

Evaluating each Ancient Connection in the same way we did for North Berwick, when they lived, as compared to our Estes men, and where, may eliminate some of these burials as possible direct ancestors.

The balance of the Ancient Connections descend from R-DF49 through different branches and are colored blue, removing them as possible ancestors of R-ZS3700.

Regardless, we all share an ancestor, R-DF49, about 4400 years ago, just shortly before R-ZP18 lived some 4250 years ago. It would make sense that R-DF49 and R-ZP18 lived in relatively close proximity, given that they only lived about 200 years apart.

What else can we learn about these Ancient Connections?

Migration Map

To view all of your Ancient Connections on a map, just click on “Migration Map” in Discover’s sidebar.

The haplogroup whose path you are viewing, in this case, R-DF13, is the red dot on the bar at the top and is shown on the map with a red circle, but is mostly obscured here by the blue and red circles with numbers in the British Isles.

That haplogroup’s migration map, and your Ancient Connections, are displayed together. Individual burials not in close proximity to others are shown with individual trowels, and multiple burials are shown with blue and red circles, with the number indicating how many burials are found at that location.

Expanding the map shows more detail. I placed a red star to indicate the Estes lineage in Deal, at the bottom right.

Many of the blue and red circles have expanded, too.

By clicking on the blue circle, you can see which samples are found there. In this case, these 7 matching samples were all found in the same archaeological dig.

By clicking on any sample, you’ll see additional information.

One of my original questions was whether or not there was any indication whatsoever, even a smidgen of possibility that the d’Este rumor might be true. Some Estes researchers are not convinced by other arguments.

Given that our closest Ancient Connection lived about 2000 years ago in the British Isles, as do most, but not all, of the other Ancient Connections, it’s exceptionally unlikely that the progenitor of the Estes lineage was living in Italy in the 1400s, just a generation before our Estes ancestors are found in the records in Deal, and some 2000 years after the parent haplogroups of R-ZS3700 were already well-established in the British Isles.

There’s another place to check for additional information.

Notable Connections

Sometimes Notable Connections includes people who are either “ancient” themselves, and whose haplogroups have been identified through their descendants, or are from burials, or a combination of both. The difference is that their identity is not entirely a mystery.

When evaluating Notable Connections for genealogy, focus on:

  • Their haplogroup
  • Your shared haplogroup
  • When and where they lived
  • Any precluding factors like we found when analyzing North Berwick

Notable Connections are all interesting, but only a few may be relevant to your genealogy or your ancestors’ journey to where you first found them.

Speaking of their journey, Globetrekker™ shows you the most likely path of your ancestor’s haplogroup over time.

Globetrekker™

Globetrekker™ is currently only available for Y-DNA, and only for those who have taken the Big Y test.

Clicking on Globetrekker™ through my cousin’s account shows the path of his haplogroup, through Europe, in this case, into England and, if I enable them, includes relevant Ancient Connections. One Ancient Connection, Mount Pleasant 746, at Cambridgeshire, is found on the estimated genetic haplogroup path.

We’ve already determined that the Estes line cannot descend from Mount Pleasant 746, but the locations of the descendants of our common ancestor, R-ZP18 can still provide substantial clues about where our common ancestor might have lived, and his culture.

I’ve also enabled Globetrekker™’s “Sibling Lines” which indicate haplogroup siblings with the thinner lines. These display options are easy to toggle on and off.

Note that this is an estimated genetic path. In other words, it’s not exact. Especially, paths of the newer haplogroups can and will change over time as more testers test, and earliest known ancestors (EKAs) are added. I wrote about how to add EKAs in the article, “Earliest Known Ancestors” at FamilyTreeDNA in 3 Easy Steps. Please add yours, along with their location.

Sometimes the most refined haplogroup did not emerge in England, R-ZS3700 in this case, but in America. However, since the descendants have noted their EKA correctly as originating in England, that’s where the most refined haplogroup is also shown.

Furthermore, other than for Native Americans who are indigenous to the Americas, Globetrekker™ and the Migration Map both stop at the originating land mass for both Y-DNA and mitochondrial DNA.

You can read more about Globetrekker™, here.

What About the d’Este Family Story?

Now, about that d’Este family story.

Globetrekker™ utilizes the “least cost” migration methodology, which means the easiest, least risky, route of passage from place to place for our ancestors. The Strait of Dover is the closest link to the European mainland, and was shallower at that time as well.

There’s absolutely no genetic evidence that points to Italy or anyplace south for the Estes ancestral line. In fact, haplogroup R-S552 emerged about 4650 years ago, and appeared about the time that this lineage crossed from continental Europe into what is today England. There’s no evidence that this line back-migrated to the continent, to then remigrate back to the British Isles after 1471.

Ancient Connections show us that there’s evidence of the Estes ancestral haplogroups in many locations across the British Isles, long before Frencesco d’Este was being exiled from Italy. Multiple Estes family members appear in the earliest records in the Deal area, so it’s certain that they were well established and probably fishing on those same shores hundreds, if not thousands, of years earlier, based on Ancient Connections these various migration maps.

These provide one more very large nail in the coffin of that much-loved but extremely unlikely family story.

The final piece of evidence would be if a proven male descendant of the d’Este line tested and did or didn’t match. I’m not holding my breath.

Mitochondrial DNA

The methodology for building your Ancient Connections spreadsheet is exactly the same for mitochondrial DNA, with one exception.

You immediately know that you cannot descend from any male burial, because men don’t pass their mitochondrial DNA on to their children of either sex. You could, however, potentially be descended from his mother, or sister, or cousin, etc. Otherwise, the guidelines are the same.

Sometimes, Ancient Connections can resolve long-standing conflicts.

The Conflict Surrounding Radegonde Lambert

For a very long time, it was believed that Radegonde Lambert, an early Acadian woman born around 1621, was Native American because there were no known people, other than her, with that surname in Acadia. Based on the birth years of her children, she married Jean Blanchard, a French man, around 1642.

It doesn’t help any that French soldiers arrived in 1632, family settlement began about 1636, but there are virtually no records until the 1671 census, nearly 40 years later. Lots of people perished during that 40 year window.

Radegonde could have married before her arrival in Acadia, and Lambert may not be spelled accurately. We are fortunate that French women are referenced by their birth surnames, not their married surnames, so she is listed as Radegonde Lambert, the wife of Jean Blanchard on the 1671, 1678 and 1686 censuses.

Based on the conflict swirling around her presumed Native American ancestry, plus early mitochondrial DNA HVR1/HVR2 results that pointed to haplogroup “X”, which has both Native American and European branches, Radegonde began to be reported as “DNA confirmed Native”. However, that was incorrect, and she was NOT DNA confirmed as Native. Haplogroup X2a and subclades are Native American, while other haplogroup X AND X2 subclades are European, as can be viewed in the Acadian AmerIndian DNA Project.

By the time full mitochondrial sequence testing became available, that incorrect “confirmation” was firmly entrenched in family trees and among researchers, leading me to pen the article, Haplogroup X2b4 is European, Not Native American.

While ho-hum with a yawn today, it was radical at the time and greeted with quite the kerfluffle. After all, Radegonde was proven Native and HOW DARE ME! 😊

Prior to Mitotree, Radegonde’s haplogroup was X2b4, but now it’s been extended to X2b4t2, which arose about the year 500, or around 1500 years ago.

X2b4 and subclades are quite rare, with only 353 descendants today, including subclades.

X2b4t2 only has 65 members.

Clicking on the “Other Countries” link takes you to the Country Frequency report.

Click on “Table View.”

Note that the 36 “Other Countries” includes people who have listed “Unknown Origin,” who are counted individually. People listing United States often mean they are brick walled here. Some people interpret this as Native American, but there is a separate United States Native American category. Not everyone selects the correct category.

These locations are user-reported in the Earliest Known Ancestor (EKA) information, which is critical for Discover reports. I wrote about how to complete that information in 3 easy steps, here. Please add yours, including location!

One person has reported that Radegonde Lambert is “United States Native American.” She’s not Native, and she never lived in the United States either. During her lifetime, Acadians lived in Nova Scotia, where three censuses accurately reflect her residence.  Perhaps that incorrect information was entered by someone years ago, and never changed. Most people don’t think to update their EKA information.

Unfortunately, when misinformation is provided, or not corrected after we learn more, new testers view that as nuggets of evidence, and the misinformation cycle continues.

One of the benefits of Ancient Connections is that they are NOT based on trees, historical records, or genealogy of any sort. Ancient Connections are based on archaeological digs, and the location of the excavation is not subject to question.

So, let’s take a quick look at Radegonde Lambert’s Ancient Connections and see what we find.

A Quick Sneak Preview

Because I’m interested primarily in a quick view of locations, I’m skipping right to the Migration Map where all of the Ancient Connections are shown.

Radegonde’s Ancient Connections are scattered all over Europe, but there’s absolutely nothing in the Americas.

Given that Native burial excavations are culturally frowned upon in many locations, we might not see any in the US, but we also wouldn’t see any recent burials in Europe, given that the Native people have been in the Americas for well over 10,000 years.

Generally, even when Ancient Connections are missing in the US, we still find some contemporary testers with proven genealogy who carry that haplogroup, and at least a few ancient burials in Canada, Mexico, Central and South America.

The first seven Ancient Connection matches carry haplogroup X2b4, and the rest are European subgroups of X2b4. There are no closer matches as of today, but that doesn’t mean there won’t be eventually.

X2b4 emerged sometime before 5200 years ago, clearly someplace in Europe, possibly central Europe.

Radegonde’s X2b4 match locations are:

  • Malá Ohrada site in Prague – the individual lived 5800-5400 years ago
  • Hetty Peglers Tump, Gloucestershire, England – lived 5639-5383 years ago
  • Sorsum, Hildesheim, Lower Saxony, Germany – lived 5350-5100 years ago
  • Passage Tomb, Carrowkeel, Cairn K, Sligo, Ireland – lived 5100-4600 years ago
  • Kolín I-7b, Bohemia, Czech Republic – lived 4835-4485 years ago
  • De Tuithoorn, Oostwoud, Netherlands – lived 4579-4421 years ago

It’s unquestionable that X2b4 was found across Europe, not in the Americas, 5000 years ago.

This image is NOT from Radegonde Lambert’s Ancient Connections. I’ve included it to illustrate a Native American branch of haplogroup X2.

The descendants of Native American haplogroup X2a, shown above, match Kennewick Man, who is also X2a, as their closest Ancient Connection. He lived between 9250 and 8390 years ago along the river in present-day Kennewick, Washington. Their second-closest Ancient Connection is with an X2a1 burial found in Windsor, Ontario, who lived between 1223 and 1384 CE.

Neither of these unquestionably Native burials are found in the Ancient Connections of Radegonde Lambert’s descendants.

It’s worth noting here that when evaluating rare haplogroups, their Ancient Connections may reach far back in time. For example, if a Native American haplogroup only has a few Ancient Connections within the Americas, the rest of their Ancient Connections, if any, will be found on another continent. Failing to read the results thoroughly and thoughtfully could lead to an inappropriate and incorrect conclusion.

For example, haplogroup X is found in Eurasia prior to the migrated of people across Beringia, the now-submerged landmass connecting Asia with Alaska, to become the indigenous people of the Americas. Therefore, if there are less than 30 closer X2a Ancient Connections, one would expect to find Ancient Connections reflecting that continental Asian, or even Eurasian, heritage far back in time.

Notable Connections

One final tip for both Y-DNA and mitochondrial DNA is to check Notable Connections and selectively add them to your spreadsheet, if appropriate. Sometimes you’ll find people there that are both Notable and Ancient.

Not that we need more evidence about whether Radegonde Lambert’s matrilineal ancestors were Native or European, but Notable Connections provides us with one more corroborating piece of evidence.

Cangrande della Scala was an Italian nobleman who lived around 1300. He and Radegonde share a haplogroup X2b1″79 ancestor in Europe around 9000 years ago, which was after the Native people had crossed Siberia and Beringia to begin settling Canada and the Americas.

If there was any question left about Radegonde Lambert’s origins, Ancient Connections resolved it, with a backup volley from Notable Connections.

Radegonde Lambert was my ancestor, so I’m going to build her Ancient Connections spreadsheet and savor every discovery, but if I were simply seeking confirmation of or the answer to the question of whether Radegonde Lambert was Native American or European, I need look no further.

Mitochondrial DNA Case Study

In the article, Mitochondrial DNA A-Z: A Step-by-Step Guide to Matches, Mitotree and mtDNA Discover, I wrote in detail about utilizing mitochondrial DNA to break through genealogy brick walls.

My goal was to detremine if Catherine LeJeune, Edmee LeJeune and Jeanne LeJeune dit Briard were sisters or at least matrilineal relatives. Fortunately, we had several testers.

As it turned out, Catherine and Edmee were European sisters, but Jeanne did not share a matrilineal ancestor with Catherine and Edmee. Jeanne was Native American.

Next, we wanted to discover as much information about the LeJeune sisters as possible.

I created an Ancient Connections spreadsheet for the LeJeune sisters and included those results in my analysis, so please take a look. Their Ancient Connections were unexpected and simply astounding.

You literally never know who is waiting for you, nor the message they hold, just waiting to be delivered.

Ancient Connections are clues from your ancestors.

_____________________________________________________________

Share the Love!

You’re always welcome to forward articles or links to friends and share on social media.

Subscribe!

If you haven’t already subscribed, it’s free. You’ll receive an e-mail whenever I publish by clicking the “follow” button at the top of the main blog page, here.

Help Keep This Blog Free

I receive a small commission when you click a vendor link in my articles and purchase that item. This does NOT increase your price but helps me keep the lights on and this informational blog free for everyone. Please click on the affiliate links in the articles or to the vendors below if you are purchasing products or DNA testing.

Thank you so much.

DNA Purchases and Free Uploads

Genealogy Products and Services

My Books

Genealogy Books

Genealogy Research

RootsTech 2026 – The Wind Beneath Our Wings

I started writing this article on Sunday evening, the day after RootsTech ended, and I’m basking in the afterglow. Also, my back and feet may never forgive me.

As a tongue-in-cheek comment, I think someone coined the word “exhausterwhelmulated” and defined it as being exhausted, overwhelmed, and overstimulated all at once. Yep, that’s me.

However, I need to add another couple of words to this – gratitude and joy.

Gratitude and Joy

I’m going to try to express this without sounding too sappy.

Do you recall the joy you used to feel when you spotted a relative you loved dearly but didn’t get to see often? Think of the unbridled joy as you piled out of your parents’ car and spotted your grandmother coming out of the door because she saw the car pull up. You ran as fast as your little legs could carry you directly into her arms, and got hugged so tightly it nearly squeezed the breath out of you.

I don’t know what the word for that would be, but it’s similar to how RootsTech feels.

Let me explain. Continue reading →

MyHeritage Whole Genome Sequencing (WGS) Results and Comparison

I’m excited to receive my low-pass whole-genome sequencing test results from MyHeritage. When MyHeritage initially introduced their new test, I wrote about what that means in the article, MyHeritage Introduces a Low-Pass Whole Genome Autosomal DNA Test and Why It Matters.

In that article, I said I was ordering a WGS test and would publish a comparison of the new test with the two tests I’ve previously taken with MyHeritage, plus a test I uploaded to MyHeritage from FamilyTreeDNA in 2016.

Before I review these comparative results with you, I want to properly set expectations.

What To Expect from the MyHeritage Whole Genome Sequence (WGS) Test

From Ran Snir, Vice President of Product Management for MyHeritage DNA:

  1. Those who take a MyHeritage DNA test now are all sequenced with WGS and will receive the same access to features and results as those who have taken a MyHeritage DNA test and were genotyped with an old chip in the past. In fact, all samples processed by the lab in December were already processed with WGS.
  2. The transition to WGS does not introduce new features and capabilities immediately.
  3. The new WGS technology has minor implications when it comes to the ethnicity estimate results and DNA Matches, but people should not expect to get “something completely different”.
  4. The transition to WGS and having more people processed with it opens the door for deeper research and more insights. It will allow MyHeritage to drastically improve its phasing, imputation and matching algorithms. This will take time as MyHeritage needs to amass a lot of data first. In the long run, MyHeritage plans to improve the product, build new features and introduce new capabilities which will be based on learnings from WGS.

Thank you, Ran.

In this article, I am not focusing on ethnicity, but on DNA matches, which I depend on to help me unravel those pesky genealogy puzzles.

Also, please note, some features I’m discussing here are free with the purchase of a DNA test, and others require a subscription at some level. I have a subscription, and I use it nearly every day.

Coupon Code for a $20 DNA Test

That said, if you already know you want to order the WGS test, or you’re a new tester, use this special coupon code at checkout to reduce the test to $20 through the end of February 2026. That’s a great value!

Coupon Code: RobertaFeb26

Now, let’s look at my results when comparing the WGS test to the results of my other three tests at MyHeritage.

How does the new WGS test fare?

My Results

Before ordering my WGS test from MyHeritage, I already had three tests at MyHeritage to choose from.

MyHeritage allows you to select between different tests, including uploads and tests you’ve taken at MyHeritage at different times. There’s absolutely no need to delete older tests there, and in fact, I recommend that you don’t. This article illustrates why.

My four tests include:

  • FamilyTreeDNA (FTDNA) test uploaded to MyHeritage in 2016
  • MyHeritage health test taken in 2019
  • MyHeritage test taken in June 2024
  • MyHeritage low-pass whole genome test (WGS) taken in December 2025
FTDNA 2016 MH Health 2019 MH 2024 MH WGS
Total Matches 19,722 17,179 17,767 17,676
TOFR 128 111 108 Not ready

This chart shows the total number of matches and Theories of Family Relativity for each test in January 2026.

What Are Theories of Family Relativity (TOFR)?

I have several very useful Theories of Family Relativity (TOFR) where MyHeritage uses trees and other documentation, such as census records, to connect you and your DNA matches to common ancestors. TOFR is one of MyHeritage’s most beneficial tools.

In this example, my match only provided their father’s name, but that name was linked to our common ancestors by connecting through a FamilySearch tree. Often, multiple potential relationships and paths are shown. Like with any other tool, each theory needs to be reviewed for accuracy.

Please note that TOFR is only run periodically and has not yet been calculated for the WGS test results. I’m sure that will happen soon.

Evaluating Matches

I wanted to know if (and how) the same people matched me on the different tests, including the new low-pass whole genome (WGS).

  • Are there differences?
  • Are the differences slight or pronounced?
  • Do some people match me on some tests, and not others?
  • Do some people match me on earlier tests, but not the WGS?
  • Do some people match me on the WGS, but not earlier tests?
  • What is the takeaway from all of this?

To compare the results of all four tests, I created a side-by-side comparison spreadsheet.

The Spreadsheet

I created a spreadsheet where I recorded 434 individual matches by entering information in the following columns:

  • A – Match number that I assigned
  • B – Match source (more about this in a minute)
  • C – FTDNA 2016 test matching number of cMs
  • D – MH 2019 matching number of cMs
  • E – MH 2024 Health matching number of cMs
  • F – MH Low Pass Whole Genome Sequencing (WGS) matching number of cMs
  • G – Relationship if known
  • H – Common Ancestor if known

I included several other columns in my spreadsheet for my own genealogical research purposes that show my matches’ tree size, and the actual lineage from them to our common ancestor couple. However, for comparing matches and accuracy, I’ve utilized the columns indicated above.

Match Sources

I wanted to compare different types of matches, meaning not just the closest or the most distant, or only the matches I can identify. These are the sources of the matches I compared.

  • Cousin Finder – I actually started a spreadsheet back in October 2025 when I was using Cousin Finder to find cousins, meaning people with common ancestors identified by MyHeritage. Twenty-eight of the 378 people that MyHeritage identified as cousins are DNA matches, so those were the first matches I entered into this comparison spreadsheet, along with our most recent common ancestors.
  • TOFR – All Theories of Family Relativity begin with DNA matches, then connect you and your matches together using trees and/or documents, when possible. Because matches vary with each of the tests, so do the TOFRs. WGS theories aren’t yet calculated, but the matches are, so I’ve included TOFR matches here.
  • Family Kits – These 15 matches are family members’ tests that I manage and match, so I clearly know how we’re related.
  • Top 100/150 – The first group of matches, other than the above categories, were the top 100 matches using the FamilyTreeDNA 2016 kit, which was my first test at MyHeritage. All tests continue to accumulate matches over time, so it just made sense to start here.

However, after I finished transcribing each of those 100 matches into the spreadsheet and started transcribing the top 100 matches for the MyHeritage 2019 test, I quickly realized that the top 100 matches were not the same between tests. Therefore, I used the top 100 matches from all 4 tests. For every name included from any test in the top 100, I included the matching cM amount from all four tests. This means that in total, there are more than 100 in the “Top 100”, so now it’s called the Top 100/150, but all of the top 100 matches from each of the four tests are included in the spreadsheet. In total, there are about 220 in that category.

  • Bottom 100 – Last, I included the bottom 100 matches on the FTDNA 2016 kit, meaning I listed those and searched for them on the other tests. If I had included the bottom 100 from all four tests, it would have been more like the bottom 350.

When I finished listing all of these matches, I had 434 to work with for this comparison. .

Minimum Matching

The minimum MyHeritage reported match is 8 cM, and at that level, a surprising number of tests don’t match either parent, although some clearly match with close relatives on that parent’s side, which means that either:

  • Those tests (either mine or the match’s, or both) were uploaded and imputed
  • Some portion of the parents’ test did not read
  • These are not valid matches, meaning they are identical by chance, not by descent.

About Imputation

Imputation is a widely used technology among vendors to bridge small sections of unread DNA. This is useful when comparing files from different vendors for matching.

Vendors use imputation internally too.

For example, vendors often use different DNA chips in the lab. They sometimes change chips internally, as well, for a variety of reasons. Regardless of why, the same locations aren’t always read, or aren’t read successfully. Imputation levels the playing field, allowing backwards compatibility, and compatibility for matching across platforms. Imputation fills in the blanks to equalize those files, allowing them to be compared for matching.

Let me give you an example. Let’s say you have the letters c_t, where the middle letter between c and t is missing. In English, there are a limited number of letters that can be. To begin with, it must be a vowel. In this case, it has to be either a, o or u. Next, looking at context, if the surrounding words are “the c_t chased a mouse,” the missing word is not cut or cot. It’s almost certainly cat, so the “a” is filled in using imputation.

Imputation usually works well, but occasionally it can extend matching areas improperly. This has always been true, and it’s still true with the new low-pass WGS test. The new WGS test only scans the genome twice to keep the test affordable. Any “no read” area must be imputed. I wrote about imputation here.

Ok, back to the MyHeritage comparison!

Test Comparison Methodology

If you’re recreating this process with your own results:

  • Color-code the column headers for the various tests
  • Label them clearly so you can easily differentiate between tests
  • Freeze your top row

Select the test you want to search for matches, and record the people you want to cross-check. I began the process with my FTDNA test that I uploaded to MyHeritage in 2016.

I entered the matches on my spreadsheet, recording the matching cM amount. Then I selected the other tests, one by one, and searched for the same match name.

In this case, I started with the FTDNA 2016 test. Jane Jones (not her real name) matched me at 744 cM.

Then I selected the MyHeritage 2019 test, searched for Jane’s name, and recorded the match amount – 739 cM. I did the same with the 2024 test, and last, the WGS test.

When searching by surname at MyHeritage, don’t always expect the person to be at the top of the list where you might expect. Be sure to scroll down a bit, even to page two, especially with common names. MyHeritage also displays people with the same surname in their trees.

Match Analysis

As we work through these match results, keep in mind that the comparison percentage numbers only pertain to the 434 people that I’ve selected to compare across all four tests. This is NOT the total amount in any category for all of my matches. There’s no way to make that determination without manually comparing every single match for all four tests – which is why I selected what I felt was a representative sample.

You’ll quickly discover that many people DON’T MATCH you on all the DNA tests. You’ll notice as I give examples that I’ve colored coded some cells for my own use in both interpreting matches as well as sorting them. For example, People who don’t match on that test were labeled “none” and colored bright blue. Eventually, I simply entered “0” instead of the word “none” so I could perform math functions on those cells. I retained the blue so I could filter by cell color. You get the idea.

Using the new WGS test, 16 people (3.7% of 434) match me ONLY on the WGS test, but do NOT match me on any of the other tests.

Interestingly enough, they are all in the Top 100/150 category for the WGS test. Those match results range from 45 cMs to 53 cMs.

That’s NOT a trivial amount of DNA. It’s rather confusing how someone could match at that level on the WGS test, but not at all on the others.

Equally as interesting is that two of those 16 WGS matches don’t match either of my parents.

So, let’s say this another way to be clear – I only see these matches on the WGS test, and none of the other tests.

How Many People Match Me on Only One Test?

Ok, so how many people match me on ONLY one test?

FTDNA 2016 Only Matches MH 2019 Only Matches MH 2024 Only Matches MH WGS Only Matches
44 (10.1%) 3 (0.7%) 3 (0.7%) 16 (3.7%)
  • 44 people match me ONLY on the FamilyTreeDNA 2016 uploaded test.
  • 3 people match me ONLY on the MyHeritage 2019 and 2024 tests, respectively, but not the same three people
  • 16 people match me ONLY on the MyHeritage WGS test

Extrapolating these percentages to the rest of my matches suggests the following number of people would match ONLY on this test in the entire match list for each test.

FTDNA 2016 MH Health 2019 MH 2024 MH WGS
Total Matches 19,722 17,179 17,767 17,676
Extrapolated Matches on Only This Test 10.1% or 1992 matches 0.7% or 120 matches 0.7% or 124 matches 3.7% or 654 matches

 How Many People DON’T Match Me on a Specific Test?

Now, how many people DON’T match me on a specific test?

No FTDNA Match No MH 2019 Match No MH 2024 Match No MH WGS Match
36 (8.3%) 117 (27%) 126 (30%) 96 (22%)
  • 36 people don’t match me on the FamilyTreeDNA test, but do match me on at least one other test at MyHeritage
  • 117 people don’t match on the 2019 MyHeritage test, but do match on at least one other test at MyHeritage
  • 126 people don’t match on the 2024 MyHeritage test, but do match on at least one other test at MyHeritage
  • 96 people don’t match me on the WGS test, but do match me on at least one other test at MyHeritage

Extrapolating these percentages provides an extrapolated number of matches that I don’t match on any specific test, but that I do match on at least one other test.

FTDNA 2016 MH Health 2019 MH 2024 MH WGS
Total Matches 19,722 17,179 17,767 17,676
Extrapolated # That Don’t Match on This Test 8.3% or 1637 matches 27% or 4638 matches 39% or 5330 matches 22% or 3,889 matches

How Many Match Me On All Tests

  • 195 matches, or 44.9%, nearly half of my matches, match on all four tests at some level.
  • Out of those, 68, or 15.7% of the total number of matches match me at exactly the same cM level across all 4 tests. That’s pretty remarkable.

The Largest Differences Between Tests

Another question might be how large the difference is between the various matches.

I calculated the largest differences between the highest and lowest match values between the four tests, and placed that value in column G. This means that I subtracted the lowest value of the four tests on this particular match, from the highest value.

In the first row, that means I subtracted 0, the MH 2019 test value, from 75, the WGS test value. The difference between the lowest and highest values is 75 cMs.

Next, I sorted, highest to lowest in column G, so the largest difference is displayed at the top.

I was VERY surprised to see a difference as high as 75 cM, so let’s evaluate the results where the difference is 50 cM or greater. Thirteen matches fall into this category.

  • Entry 168 – The largest difference at 75 cM. This person matches me at 70, 74 and 75 cM, but not at all on the 2019 test, which caused me to go back and check again. Did I spell the name correctly? Yes, I did. We don’t know why I don’t match this person on the 2019 test, but the other matching cM values are very close so they look to be correct.
  • Entry 183 – I match this person on both the FamilyTreeDNA uploaded test at 71 cMs, and the WGS test at 35 cMs, around half as much on the WGS test as the FamilyTreeDNA test. I don’t match them at all on either the MyHeritage 2019 or 2024 kits. I have no explanation.
  • Entry 186 – Like entry 168, we match on three of four tests at 62, 63 and 67 cMs, with the non-matching test being the 2019 test. I would presume that this match is accurate as well.
  • Entry 191 – This one is interesting because I match this person on the FamilyTreeDNA uploaded test at 64 cMs, but none of the other tests.
  • Entry 192 – We match at 57 cMs on both the WGS and the 2024 tests, but not the 2019 test, where we don’t match at all. The match on the FamilyTreeDNA test is 11 cMs lower, at 46 cMs.
  • Entry 228 – This person is my half 1C1R, and I match them on all the tests, of course. However, there’s a 53 cM difference between the WGS and the FamilyTreeDNA uploaded test. In a relationship this close, 53 cM is a small percentage and won’t affect matching, but it’s not an insignificant amount of DNA.
  • Entries 233, 247, 248 and 283 – I match these people ONLY on the WGS test at 50, 52 and 53 cMs, so if I hadn’t taken the WGS test, I wouldn’t match them at all. Without additional research, we can’t tell if this is a legitimate match or not, but 50-53 cM would be a lot to be imputed or to be identical by chance. These people also match one of my parents’ tests, which eliminates the identical by chance possibility, meaning some of the DNA matches my mother and some matches my father – at least on my end. We can’t determine if this match is identical by chance on their side. I’ve never seen a 50+ cM segment (or even close) that is identical by chance, though.
  • Entry 249 – Matches on the FamilyTreeDNA test at 15 cM, and the MyHeritage 2024 test at 52 cM, but not the others.
  • Entry 250 – Matches at 51 cM on the FamilyTreeDNA test, but not on any of the MyHeritage tests.
  • Entry 279 – Matches only on the MyHeritage 2019 test at 50 cM.

Difference Range

Next, let’s review the entire range of differences, meaning the largest matching difference for any one person across all four tests, by group. I’m including all 434 here so you can judge for yourself.

  • 50-75 cM difference – 13 matches analyzed above

  • 45-49 cM difference – 22 matches

  • 40-44 cM difference – 11 matches

  • 35-39 cM difference – 9 matches

  • 30-34 cM difference – 10 matches

  • 25-29 cM difference – 12 matches

  • 20-24 cM difference – 26 matches

  • 16-19 cM difference – 28 matches

  • 13-15 cM difference – 29 matches

  • 9-12 cM difference – 29 matches

  • 8 cM difference – 78 matches

The 8 cM difference has the most of any value or category because this is the lowest level of matching at MyHeritage. Many tests have a minimum level match on a test or tests, and no others.

  • 6-7 cM match difference – 41 matches

The match differences at 5 cM and below are inconsequential. 57 matches fall into this category.

Commentary

One of the indicators of a valid match is if a parent has tested and also matches,

Of these 434 matches, 35 match neither parent, and most of those are at the smallest match level, meaning 8 cM. Of all the match amounts, that would be the least reliable, and most likely to be a false positive match, or identical by chance.

However, that’s not universally the case. Some WGS results match people at significantly higher levels, but don’t match parents. Two WGS matches match people at 47 and 49 cMs, respectively, and not on any of the other tests. Those two WGS matches don’t match either parent.

After reviewing all 434 selected matches, it appears that both the FamilyTreeDNA 2016 test, and the WGS test produce the most consistent and reliable results of the four tests.

44 people, or 10%, match on BOTH the WGS and the FTDNA tests, but neither of the other two tests. A total of 13.8% match EITHER the FTDNA test OR the WGS test, but not the others.

Conclusions

I think we can draw several conclusions from this comparison.

First, let’s evaluate the number of matches. Looking at the differences between the total number of matches between the various tests, especially the three MyHeritage tests, over time, isn’t that great. That’s exactly why you can’t depend on these numbers as an accurate comparison.

FTDNA 2016 MH Health 2019 MH 2024 MH WGS
Total Matches 19,722 17,179 17,767 17,676

There are only a few hundred differences between the three MyHeritage tests, and about 2000 between the FamilyTreeDNA test uploaded in 2016 and the various MyHeritage tests. That’s a substantial difference.

The difference number of matches between tests may seem irrelevant, especially the MyHeritage tests, until you realize that those who match AREN’T ALL THE SAME PEOPLE. In other words, comparing the MyHeritage 2024 test with the WGS test only shows a difference of 91 matches. This DOES NOT mean that the MyHeritage 2024 test and the WGS test have 17,676 of the same people who match both tests, and that the 2024 test simply has 91 more matches than the WGS test.

As we’ve seen, many people who appear on any one match list don’t appear on other match lists.

Our analysis showed that 44.9% of my 434 matches compared appear on all match lists, which means that more than half of my matches appear on one or more match lists, and not the others. Therefore, just comparing the number of matches isn’t really relevant. You need to compare the people included on all the different tests, which is why I created my spreadsheet and included people from a wide variety of sources.

3.7% of my matches on the WGS test were not on any other test, which extrapolates to approximately 654 of my total WGS matches that I wouldn’t receive any other way.

I care a great deal about those matches, especially since at least some appear to be high value.

Yes, I absolutely, positively want those matches, especially when you consider that some of the matching differences are as high as 75 cM. A 75 cM match can be in the second, third or fourth cousin range.

Realistically, they may or may not be valid or useful matches – but if I don’t have the opportunity to compare them, I’ll never know.

Should You Purchase the WGS Test If You’ve Already Tested?

So, now for the question you’re surely asking yourself.

Truthfully, when I ordered my test back in December, I was ambivalent. I only ordered it to do this comparison for my blog readers – and I really dislike spending money on something that I don’t think will benefit me.

Note the words “don’t think.”

I’ve changed my mind, for several reasons, and I’m glad I ordered the test.

The thing that changed my mind was that I received a nontrivial amount of matches on the WGS test that I didn’t receive on any of the others – even if some of them turn out to be identical by chance.

Since we can’t go back in time and take the earlier tests, and MyHeritage no longer accepts uploads from other vendors, our decision now is whether or not we should take the new WGS test, or not, especially if we already have a DNA test at MyHeritage.

If you’re a new tester, by all means, test at all four of the main vendors. DNA matching is the best thing since sliced bread.

However, the people I’m really speaking to here are those who already have a test of some sort at MyHeritage.

Here’s the bottom line:

  • You will receive WGS matches that you didn’t receive on your other test – and vice versa, so don’t delete your older test at MyHeritage
  • Some of those new WGS matches may well be high-value matches – as was illustrated in the “differences” I discovered.
  • Given the differences in who is included in the match list, your TOFR will be different too – perhaps leading to a brick wall breakthrough. I have two that I’m just itching to solve.
  • Use matches, shared matches and TOFR from ALL of your tests at MyHeritage.

My Biggest Regret

As Ran Snir said, new features and developments at MyHeritage will be based on the WGS test. We don’t know what those developments might be, or when they will become available. But it’s very clear that while testers on the older testing platforms will receive as much as MyHeritage can give them, the MyHeritage DNA future is being build on the WGS platform. I want to be there and benefit from new discoveries.

My biggest regret is that my parents aren’t around to take the new WGS test – and neither are several other family members.

Of the 15 family members whose tests I manage at MyHeritage, 9 are deceased, and I think that four more are as well. Two others are now quite elderly and are no longer able to consent or retest.

Your closest family members are your DNA anchors, identifying lineages and pointing you in specific directions, guiding your research.

The very best thing you can do for your genetic genealogy is to test your grandparents if they are living, and your parents. If they aren’t available, test your closest relatives such as grandparents, siblings, aunts, uncles and first cousins.

Preparing for the Future

So, here’s my advice:

  • Take the WGS test yourself in order to glean as much information as possible and to benefit from future developments.
  • Retest any relatives whose tests you manage on the WGS platform, if possible.
  • Test your close family members and anyone you know whose DNA test could help you identify ancestral lineages.

Why is testing your relatives important?

Close relatives will carry some of the DNA from your mutual ancestors that you don’t.

Having the known DNA of your ancestors means that you can evaluate and analyze the trees of the entire group of people who match those identified DNA segments to see if you can break down an upstream brick wall.

I’ve been successful doing this for some time – and am in the process again by combining DNA matches and traditional records research.

Coupon Code for $20 DNA Test

MyHeritage has been kind enough to provide a limited-time coupon code (RobertaFeb26) for my readers which DROPS YOUR PRICE for the DNA test to $20 through February 28th at midnight.

This is the absolute lowest price I’ve ever seen for a DNA test.

You’ll receive the following features that are included with every test:

  • Ethnicity and ethnicity map
  • DNA matches and the ability to contact them
  • Shared ancestral surnames
  • Chromosome browser
  • cM Explainer

In addition, with this code you’ll receive both Shared DNA Matches and Shared Ancestral Places that usually require a subscription.

Normally, a subscription is required to access:

  • Trees of DNA matches
  • Shared DNA Matches (free now with the coupon code)
  • Shared ancestral places (free now with the coupon code)
  • AutoClusters
  • Theory of Family Relativity (TOFR)

If you’re interested in trying a subscription, click here to purchase a MyHeritage subscription with a free trial.

Here’s the link to purchase the DNA test, and here’s the coupon code to enter at checkout: RobertaFeb26

And yes, absolutely feel free to share the coupon code with your family, friends, and anyone else who might benefit.

Let me know how your results compare when you receive them.

_____________________________________________________________

Share the Love!

You’re always welcome to forward articles or links to friends and share on social media.

Subscribe!

If you haven’t already subscribed, it’s free. You’ll receive an e-mail whenever I publish by clicking the “follow” button at the top of the main blog page, here.

Help Keep This Blog Free

I receive a small commission when you click a vendor link in my articles and purchase that item. This does NOT increase your price but helps me keep the lights on and this informational blog free for everyone. Please click on the affiliate links in the articles or to the vendors below if you are purchasing products or DNA testing.

Thank you so much.

DNA Purchases and Free Uploads

Genealogy Products and Services

My Books

Genealogy Books

Genealogy Research

2025 Genetic Genealogy Retrospective: Wow – What a Year!

2025 has been quite a year in genetic genealogy. Genetic genealogy, per se, really isn’t a separate “thing” anymore. DNA testing is now an integral part of genealogy, with the potential to answer questions that nothing else can!

The 76 articles I wrote in 2025 fall into multiple categories and focus on different topics based on what was happening in the industry.

From my perspective, here are the most notable announcements and trends in genetic genealogy, and genealogy more broadly.

#1 for 2025 – Mitochondrial DNA: The Million Mito Project Released the New Mitotree, Updates, and mtDNA Discover

The biggest genealogy news items this year, both industry-wide and genealogy-changing are definitely the release of the new Mitotree, plus two tree updates. But that’s not all.

In addition, full sequence mitochondrial DNA testers received new Mitotree haplogroups, if appropriate, and everyone received a haplotype – a new feature. Along with Mitotree, FamilyTreeDNA introduced mtDNA Discover which provides 13 individual reports based on your haplogroup and matches.

It’s no wonder that mitochondrial DNA articles led the pack with the most views based on the eleven articles about that topic. If you haven’t yet tested your mitochondrial DNA at FamilyTreeDNA, there’s no better time! You never know what you’re going to discover and the more testers, the more matches for everyone.

You don’t know what you don’t know, and you’ll never know if you don’t test. Remember, mitochondrial DNA is for both males and females and tests your mother’s direct matrilineal line (mother to mother to mother, etc.) – reaching beyond known surnames.  Click here to order or upgrade.

#2 – MyHeritage Low Pass Whole Genome Sequence Test Charges into the Future

Another big hitter is the new MyHeritage low-pass whole genome test (WGS) test. It’s new and innovative, but we haven’t seen comparative results yet.

My results from the new low-pass whole genome test just came back, and I haven’t had the opportunity to review them yet, as compared to the earlier tests. That said, I do have roughly the same number of matches, but I need to determine if they are the same matches, and how well they track. I’ll be working on that review soon.

The new whole genome test may be more about future proofing and preparedness than additional current benefit – but we will see. I definately wanted to take the whole genome test so I can receive and benefit from whatever new is coming down the pike.

MyHeritage allows you to maintain multiple DNA tests on your account, so the new whole genome won’t “replace” your older or uploaded test. That way, you can easily compare the results of the whole genome against any DNA test that you curently have at MyHeritage.

Click here to order the new test.

#3 – 23andMe Experiences Problems

On a less positive note, but still quite newsworthy is the bankruptcy of 23andMe and subsequent repurchase of 23andMe by the original founder after setting up a new nonprofit. I have real mixed feelings about this topic. However, 23andMe was really never about genealogy, and now, matching segment information is no longer available. Those searching for unknown parents or family may want to test there if they are unsuccessful elsewhere.

Best Genealogy Tool

The FamilySearch full text search continues to have a HUGE impact for genealogists. This tool is not one-and-done, but provides increasing amounts of rich information as more records are added to the “fully scanned” collection. If you haven’t tried it, please do. It’s a game-changer and continues to improve.
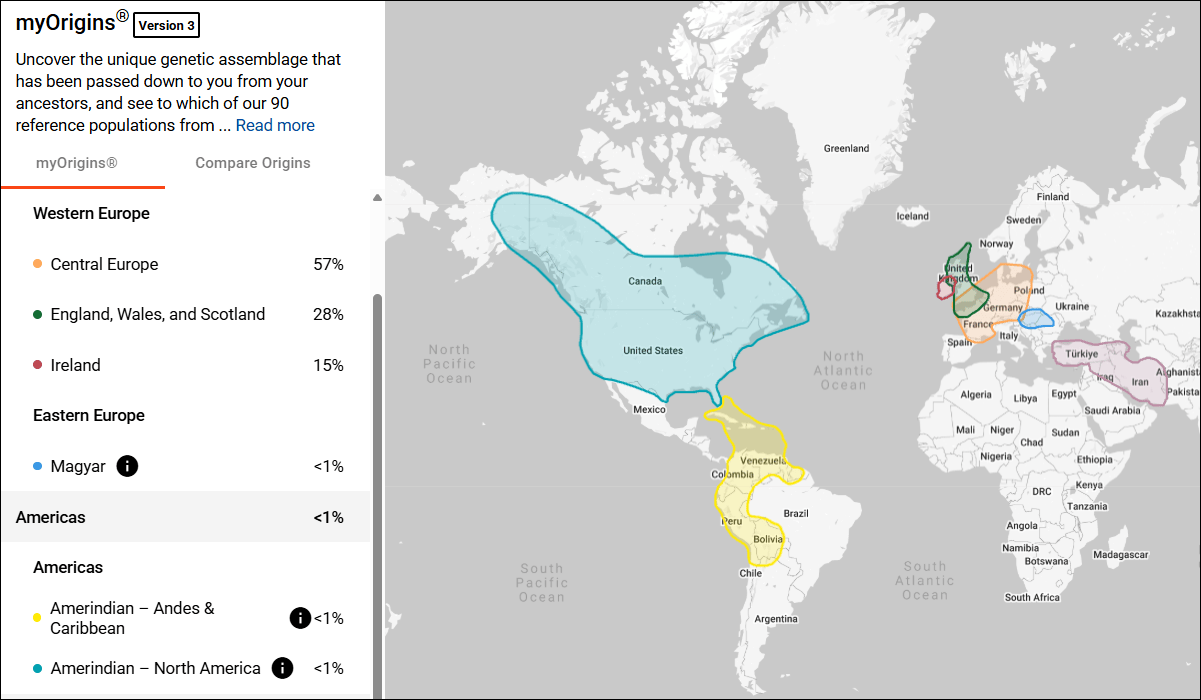
A Cautionary Word About AI – Artificial Intelligence

AI is such a hot topic right now that I feel it needs to be included.

The FamilySearch full text search uses a form of AI. However, you’ll quickly notice that it can’t read everything, gets words and names wrong, and if you actually need to fully depend on it for accuracy, you cannot. (That said, it’s still an amazing tool, and I’m not picking on FamilySearch.)

Aside from FamilySearch, AI in its current form is both wonderful and terrible. I’ll be writing about AI in the new year, but for now, don’t ever rely on AI for anything that you can’t verity. It’s your assistant, not an expert, no matter how insistent it is. Never trust and always verify.

This is ESPECIALLY TRUE WHEN RELATED TO GENETICS and genetic related topics. I can’t even begin to tell you how very wrong it has been, and how much people fall in love with inaccurate results. No, just no – at least for now.

You need to know your AI tool, your skill set, your understanding of AI broadly, the tool’s limitations, and yours, and that’s all before verifying the actual AI results. If you want to educate yourself, and everyone should, treat yourself to anything, anyplace by either Mark Thompson or Steve Little, the dynamic AI duo. They offer YouTube videos and classes in a wide variety of places – but keep in mind that AI tools and technology literally change every few weeks.

AI is, indeed, a specialty all unto itself, much like genetic genealogy. And right now, it’s not soup yet, but it is cooking.

Tried and True Genetic Genealogy Staples – DNAPrint and Genetic Affairs

I haven’t written about either one this year, but I use both DNAPainter and Genetic Affairs regularly.

I consistently paint segments from matches at both MyHeritage, FamilyTreeDNA, and GEDmatch that are newly identified to an ancestor or ancestral couple at DNAPainter.

Unfortunately, neither Ancestry nor 23andMe provide matching cM location information for your matches (chromosome browser), but you may find some people who have tested at those companies at both FamilyTreeDNA and GEDmatch if they have uploaded to either of those vendors. Both vendors provide segment information and a Chromosome Browser, enabling you to paint that information to DNAPainter when you can identify your common ancestor.

MyHeritage also provides a Chromosome Browser, but unfortunately, no longer accepts uploads from any other vendor. You can paint segments from MyHeritage, but no longer upload DNA files to MyHeritage.

Thanks to DNAPainter, I have 90% of my segments identified to specific ancestors – which is actually rather remarkable given that my mother’s grandfather was a Dutch immigrant, and her great-grandparents on her other side were German immigrants, meaning we don’t have many matches on either of those lines.

Genetic Affairs continues to develop new, advanced clustering tools, one of which I’ll be reviewing soon.

Major Vendor Releases

Aside from what’s listed above, most of the major vendors released new features.

MyHeritage released a VERY COOL new tool called Cousin Finder that finds your relatives in the MyHeritage database, whether they match you on a DNA test, or not. They may not have even taken a DNA test. Cousin Finder identifies your common ancestor and shows your relationships. It’s a wonderful way to initiate communications, discuss your common ancestors, and ask about DNA testing.

Of my 378 Cousin Finder matches, only 23 (about 6%) are on my DNA match list, so that leaves 355 people to message, several of whom represent Y-DNA and mtDNA lines I don’t have. You can bet I’ll be offering testing scholarships.

Additionally, MyHeritage released a new ethnicity version.

FamilyTreeDNA, in addition to the new Mitotree, Discover, and associated features, released a new match matrix so you can see if and how selected matches are related to each other in a grid format. In other words, you can create your own cluster.

A new built-in “Share” feature blurs private information to make sharing easier both on the website and in Discover.

Discover improvements include thousands of new Y-DNA and mtDNA tree branches, plus thousands of new Ancient DNA samples. Discover is evergreen, so once you’ve taken that Big Y-700 test or the mitochondrial DNA test, your learning never stops as more content is added.

Tree integration with WikiTree is super-easy and means you don’t have to choose between trees. You can choose to retain your archived tree at FamilyTreeDNA, or move your tree to MyHeritage, PLUS link yourself to your family at WikiTree.

Ancestry released match clustering and a new beta pedigree view of ThruLines, but that’s back in the shop for more work. I’d expect to see it rereleased in 2026.

Conferences

RootsTech is the granddaddy of genealogy conferences, and it’s always fun to attend and write about the experience. Many vendors release new tools or products during the conference.

The ECGGC (East Coast Genetic Genealogy Conference), held in the fall, is the only conference that focuses entirely on genetic genealogy, new tools, how to use existing tools, and more. The 2025 conference was virtual and provided a great deal of focused content. Attendees particularly appreciate the deep dive in a particular topic presented in DNA Academy.

I’ll be at RootsTech in 2026, will write about that soon, and hope to see you there.

Concepts, Techniques and Plain Old Genealogy

In the past, my Concepts series and genealogy “how to” articles have been very popular, so, in 2025, I penned a half-dozen articles focusing on frequently asked questions about relationships and DNA.

For example, how does one go about finding DNA testing candidates? The number of options may surprise you and includes both Cousin Finder and Relatives at RootsTech.

By testing ONE PERSON for either Y-DNA or mitochondrial DNA that represents an ancestor, you actually receive information about that entire lineage of ancestors. So, on my Estes line, by locating an Estes male from my line to test, I received relevant information for every Estes male in my line, back to and beyond the progenitor.

Eventually, we hit a brick wall in every line, and those tools are the perfect way to break through those brick walls.

Other articles discuss things like how to use Discover’s Ancient Connections, and the difference between half and full relationships, both in your tree and genetically. Plus, what does a cousin “once removed” mean anyway? And why do I care?

Another question I receive is how far back, based on the shared amount of DNA, should I look in my matches’ trees for our common ancestor? In other words, how many generations back should I click? That article was fun and produced some unexpected results.

Memorial Articles

Because we are part of a community, I write memorial articles when one of our friends passes on. This year, sadly, Schelly Talalay Dardashti, well-known Jewish genealogist, and another very close friend joined the ancestors, so I’ve recognized the best in both of their lives which constitutes their legacy.

Be the Storyteller

Last, but not least, I wrote about my ancestors in the “52 Ancestors” series, which launched several years ago with Amy Johnson Crow’s challenge to write about one ancestor per week. She hosts this every year, and you can join (free) now.

I’m now on ancestor #467, so yes, it’s addictive, but it’s also AMAZING how many wonderful cousins I’ve met who have information that I did not. Not only that, but after publishing about an ancestor, I’ve discovered that I’m related to people I’ve known for years. We were SOOOooo excited!

I’ve been writing about the lives of my ancestors for several years now, and the articles include attempts to identify Y-DNA and mtDNA testers for each ancestor, where appropriate. There’s so much to learn that can’t be revealed any other way.

Plus, people seem to like the “mystery” and “short story” aspect, and I salt each story with the history of the region and relevant historical events of the timeframe. You might find your ancestors here too, or other helpful information.

Find a way to share about your ancestors!

Do You Have Suggestions for 2026 Topics?

Do you have suggestions or requests for article topics in 2026? If so, please comment on this article and let me know.

Check Out the 2025 List

Here’s the list of the 2025 articles. Did you miss something fun? Enjoy!

  Title Category Date Link
1 Welcome to 2025 – Opportunities and New Genetic Genealogy Articles Welcome, general 1-2-2025 https://dna-explained.com/2025/01/02/welcome-to-2025-opportunities-and-new-genetic-genealogy-articles/
2 Anne Doucet (1713-1791), Oceans, Rivers, and Perseverance – 52 Ancestors #438 52 Ancestors 1-4-2025 https://dna-explained.com/2025/01/04/anne-doucet-1713-1791-oceans-rivers-and-perseverance-52-ancestors-438/
3 Register for RootsTech 2025 Now RootsTech 1-16-2025 https://dna-explained.com/2025/01/16/register-for-rootstech-2025-now/
4 What IS the McNeil Family History, by George Franklin McNeil – 52 Ancestors #439 52 Ancestors 1-19-2025 https://dna-explained.com/2025/01/20/what-is-the-mcneil-family-history-by-george-franklin-mcneil-52-ancestors-439/
5 Jean Garceau dit Tranchemontagne (c1785-1711), Soldier from Saint Marseault – 52 Ancestors #440 52 Ancestors 1-29-2025 https://dna-explained.com/2025/01/29/jean-garceau-dit-tranchemontagne-c1785-1711-soldier-from-saint-marseault-52-ancestors-440/
6 Memories Resurface When the Old Family Home Gets a Facelift Genealogy 2-3-2025 https://dna-explained.com/2025/02/03/memories-resurface-when-the-old-family-home-gets-a-facelift/
7 MyHeritage Introduces Ethnicity v2.5 MyHeritage 2-6-2025 https://dna-explained.com/2025/02/06/myheritage-introduces-ethnicity-v2-5/
8 Relatives at RootsTech Reveals Cousins and Provides DNA Candidates RootsTech, techniques 2-8-2025 https://dna-explained.com/2025/02/08/relatives-at-rootstech-reveals-cousins-and-provides-dna-candidates/
9 FamilyTreeDNA’s New Matrix Shows How Your Matches Are Related to Each Other FamilyTreeDNA 2-12-2025 https://dna-explained.com/2025/02/12/familytreednas-new-matrix-shows-how-your-matches-are-related-to-each-other/
10 René Doucet (c1680-c1731), Lifetime of Incessant Upheaval – 52 Ancestors #441 52 Ancestors 2-15-2024 https://dna-explained.com/2025/02/16/rene-doucet-c1680-c1731-lifetime-of-incessant-upheaval-52-ancestors-441/
11 Lineages Versus Ancestors – How to Find and Leverage Yours Techniques 2-23-2025 https://dna-explained.com/2025/02/23/lineages-versus-ancestors-how-to-find-and-leverage-yours/
12 Mitotree is Born Mitochondrial DNA 2-25-2025 https://dna-explained.com/2025/02/25/mitotree-is-born/
13 RootsTech 2025 – The Year of Discover and the New Mitotree RootsTech, Mitochondrial DNA 3-14-2025 https://dna-explained.com/2025/03/15/rootstech-2025-the-year-of-discover-and-the-new-mitotree/
14 Pierre Doucet (c1621-1713), Walking History Book Lived to Nearly 100 – 52 Ancestors #442 3-16-2025 https://dna-explained.com/2025/03/16/pierre-doucet-c1621-1713-walking-history-book-lived-to-nearly-!100-52-ancestors-442/
15 Welcome to the New FamilyTreeDNA mtDNA Group Mitochondrial DNA 3-17-2025 https://dna-explained.com/2025/03/17/welcome-to-the-new-familytreedna-mtdna-group/
16 23andMe Files for Bankruptcy – What You Need to Know! 23andMe 3-24-2025 https://dna-explained.com/2025/03/25/23andme-files-for-bankruptcy-what-you-need-to-know/
17 New “Share” Features at FamilyTreeDNA Blur Match Information and Make Sharing Easy FamilyTreeDNA 4-1-2025 https://dna-explained.com/2025/04/01/new-share-features-at-familytreedna-blur-match-information-and-make-sharing-easy/
18 The Chauvet Cave: Trip Back in Time with Prehistoric European Humans – Are We Related? History, DNA 4-6-2025 https://dna-explained.com/2025/04/06/the-chauvet-cave-trip-back-in-time-with-prehistoric-european-humans-are-we-related/
19 DNA for Native American Genealogy Webinar & Companion Book Native American 4-8-2025 https://dna-explained.com/2025/04/08/dna-for-native-american-genealogy-webinar-companion-book/
20 Marie Levron (c1686-1727), Tragedy from Cradle to Grave – 52 Ancestors #443 52 Ancestors 4-14-2025 https://dna-explained.com/2025/04/14/marie-levron-c1686-1727-tragedy-from-cradle-to-grave-52-ancestors-443/
21 Mitochondrial DNA: What is a Haplotype Cluster and How Do I Find and Use Mine Mitochondrial DNA 4-14-2025 https://dna-explained.com/2025/04/14/mitochondrial-dna-what-is-a-haplotype-cluster-and-how-do-i-find-and-use-mine/
22 New Mitotree Haplogroups and How to Utilize Them for Genealogy Mitochondrial DNA 4-23-2025 https://dna-explained.com/2025/04/23/new-mitotree-haplogroups-and-how-to-utilize-them-for-genealogy/
23 Sir Francois Levron dit Nantois(c1651-1714), and Acadia’s Pirate – 52 Ancestors #444 52 Ancestors 4-26-2025 https://dna-explained.com/2025/04/27/sir-francois-levron-dit-nantois-c1651-1714-and-acadias-pirate-52-ancestors-444/
24 Catherine Savoie (c1661-c1722/25), Whispered Threads Weave a Tapestry of Life – 52 Ancestors #445 52 Ancestors 5-4-2025 https://dna-explained.com/2025/05/04/catherine-savoie-c1661-c1722-5-whispered-threads-weave-a-tapestry-of-life-52-ancestors-445/
25 Discover’s Ancient Connections – How Are You Related? Discover, Ancient DNA 5-8-2025 https://dna-explained.com/2025/05/08/discovers-ancient-connections-how-are-you-related/
26 Mother’s Day and Legacies 52 Ancestors, Genealogy 5-10-2025 https://dna-explained.com/2025/05/11/mothers-day-and-legacies/
27 The Mystery of the Blue Fugates and Smiths: A Study in Blue Genes and Pedigree Collapse Genetics, Genealogy 5-18-1015 https://dna-explained.com/2025/05/19/the-mystery-of-the-blue-fugates-and-smiths-a-study-in-blue-genes-and-pedigree-collapse/
28 Regeneron Wins Bid for Bankrupt 23andMe – Wedding Planned 23andMe 5-19-2023 https://dna-explained.com/2025/05/19/regeneron-wins-bid-for-bankrupt-23andme-wedding-planned/
29 Francois Savoie’s Homestead Rediscovered – 52 Ancestors #446 52 Ancestors 5-24-2025 https://dna-explained.com/2025/05/24/francois-savoies-homestead-rediscovered-52-ancestors-446/
30 Memorial Day – Some Gave All Memorial 5-25-2025 https://dna-explained.com/2025/05/25/memorial-day-some-gave-all/
31 Mitotree Webinar – What It Is, How We Did It, and What Mitotree Means to You Mitochondrial DNA 6-4-2025 https://dna-explained.com/2025/06/04/mitotree-webinar-what-it-is-how-we-did-it-and-what-mitotree-means-to-you/
32 Catherine LeJeune (c1633-1671/1686), Meet Your Grandchildren – 52 Ancestors #447 52 Ancestors 6-7-2025 https://dna-explained.com/2025/06/07/catherine-lejeune-c1633-1671-1686-meet-your-grandchildren-52-ancestors-447/
33 Mitotree Q&A for Everyone Mitochondrial DNA 6-11-2025 https://dna-explained.com/2025/06/11/mitotree-qa-for-everyone/
34 Father’s Day: Bravery and Love 52 Ancestors, Genealogy 6-14-2025 https://dna-explained.com/2025/06/14/fathers-day-bravery-and-love/
35 Francoise Bourgeois (c1659-1693/1697), High Drama in Beaubassin and Terror at Port Royal – 52 Ancestors #448 52 Ancestors 6-16-2025 https://dna-explained.com/2025/06/16/francoise-bourgeois-c1659-1693-97-high-drama-in-beaubassin-and-terror-at-port-royal-52-ancestors-448/
36 Requesting Suggestions for RootsTech 2026 Topics RootsTech 6-18-2025 https://dna-explained.com/2025/06/18/requesting-suggestions-for-rootstech-2026-topics/
37 FamilyTreeDNA and WikiTree Collaboration – In Two Easy Steps!! FamilyTreeDNA, WikiTree 6-25-2025 https://dna-explained.com/2025/06/25/familytreedna-and-wikitree-collaboration-in-two-easy-steps/
38 Jacques Bourgeois (c1620-c1700), Surgeon of Port Royal – 52 Ancestors #449 52 Ancestors 7-1-2025 https://dna-explained.com/2025/07/01/jacques-bourgeois-c1620-c1700-surgeon-of-port-royal-52-ancestors-449/
39 TTAM, a Nonprofit Formed by 23andMe’s Founder Now Plans to Buy 23andMe 23andMe 7-1-2025 https://dna-explained.com/2025/07/01/ttam-a-nonprofit-formed-by-23andmes-founder-now-plans-to-buy-23andme/
40 Jacques Bourgeois: Complex Acadian, Founder of Beaubassin – 52 Ancestors #450 52 Ancestors 7-6-2025 https://dna-explained.com/2025/07/06/jacques-bourgeois-complex-acadian-founder-of-beaubassin-52-ancestors-450/
41 How to Use Ancestry’s New Match Clusters and What They Mean Ancestry 7-10-2025 https://dna-explained.com/2025/07/10/how-to-use-ancestrys-new-match-clusters-and-what-they-mean/
42 Walk with Your Ancestors: Peace, Light and Healing in an Abandoned Medieval Village History 7-21-2025 https://dna-explained.com/2025/07/21/walk-with-your-ancestors-peace-light-and-healing-in-an-abandoned-medieval-village/
43 Jeanne Trahan (c1629-c1699), Life in Chinon, La Heve, Port Royal, and Beaubassin – 52 Ancestors #451 52 Ancestors 8-2-2025 https://dna-explained.com/2025/07/28/jeanne-trahan-c1629-c1699-life-in-chinon-la-heve-port-royal-and-beaubassin-52-ancestors-451/
44 Wherefore Art Thou, Oh Ancestor – New Generation Tree Chart Suggests Where to Look in Your Matches’ Trees Techniques, Genetics, Genealogy 8-2-2025 https://dna-explained.com/2025/08/02/wherefore-art-thou-oh-ancestor-new-generation-tree-chart-suggests-where-to-look-in-your-matches-trees/
45 Guillaume Trahan (c1601-1625), More Than Meets the Eye – 52 Ancestors #452 52 Ancestors 8-13-2025 https://dna-explained.com/2025/08/13/guillaume-trahan-c1601-c1684-more-than-meets-the-eye-52-ancestor-452/ 
46 The East Coast Genetic Genealogy Conference – ECGGC – Register Now for the Best of the Best ECGGC Conference 8-14-2025 https://dna-explained.com/2025/08/14/the-east-coast-genetic-genealogy-conference-ecggc-register-now-for-the-best-of-the-best/
47 Schelly Talalay Dardashti – May Her Memory Be a Blessing Memorial 8-17-2025 https://dna-explained.com/2025/08/17/schelly-talalay-dardashti-may-her-memory-be-a-blessing/
48 Francoise Corbineau (c1609-c1665), Bride in Chinon, Founder of Acadia – 52 Ancestors #453 52 Ancestors 8-25-2025 https://dna-explained.com/2025/08/23/francoise-corbineau-c1609-c1665-bride-in-chinon-founder-of-acadia-52-ancestors-453/
49 Nicolas Trahan (c1570->1632), Life in the Heart of French Wine Country – 52 Ancestors #454 52 Ancestors 8-31-2015 https://dna-explained.com/2025/08/31/nicolas-trahan-c1570-1632-life-in-the-heart-of-french-wine-country-52-ancestors-454/
50 Mitochondrial DNA A-Z: A Step-by-Step Guide to Matches, Mitotree, and mtDNA Discover Mitochondrial DNA, Discover, Genealogy, Techniques 10-2-2025 https://dna-explained.com/2025/09/02/mitochondrial-dna-a-z-a-step-by-step-guide-to-matches-mitotree-and-mtdna-discover/
51 Renée Desloges (c1570-1627/1632), Fragments of Life in Montreuil-Bellay – 52 Ancestors #454 (this is actually 455) 52 Ancestors 9-6-2025 https://dna-explained.com/2025/09/06/renee-desloges-c1570-1627-1632-fragments-of-life-in-montreuil-bellay-52-ancestors-454/
52 Best Mitochondrial DNA Presentation EVER – You’re Invited to DNA Academy!! Mitochondrial DNA 9-9-2025 https://dna-explained.com/2025/09/09/best-mitochondrial-dna-presentation-ever-youre-invited-to-dna-academy/
53 Unfillable Shoes Memorial – Douglas Rhodenbaugh 9-14-2025 https://dna-explained.com/2025/09/14/unfillable-shoes/
54 Concepts: What Does a Cousin “Once Removed” Mean? Concepts, Genealogy 9-24-2025 https://dna-explained.com/2025/09/24/concepts-what-does-a-cousin-once-removed-mean/
55 Daniel Vannoy (1752-after 1820), “Lived in the Boundary of the Cherokee Indians” – Say What??? 52 Ancestors 9-29-2025 https://dna-explained.com/2025/09/29/daniel-vannoy-1752-after-1820-lived-in-the-boundary-of-the-cherokee-indians-say-what/
56 Daniel Vannoy and the Strange Case of the Two Sarahs – 52 Ancestors #457 52 Ancestors 10-5-2025 https://dna-explained.com/2025/10/06/daniel-vannoy-and-the-strange-case-of-the-two-sarahs-52-ancestors-457/
57 Cousin Finder – MyHeritage’s Innovative New Tool Finds Your Relatives MyHeritage 10-9-2025 https://dna-explained.com/2025/10/09/cousin-finder-myheritages-innovative-new-tool-finds-your-relatives/
58 Sarah Hickerson Vannoy (c1761 – after 1826), Threw More than Shade – 52 Ancestors #458 52 Ancestors https://dna-explained.com/2025/10/13/sarah-hickerson-vannoy-c1761-after-1826-threw-more-than-shade-52-ancestors-458/
59 MyHeritage Introduces a Low-Pass Whole Genome Autosomal DNA Test & Why It Matters MyHeritage 10-14-2025 https://dna-explained.com/2025/10/14/myheritage-introduces-a-low-pass-whole-genome-autosomal-dna-test-why-it-matters/
60 Henriette Pelletret (c1640 – before 1694), Life Death in the Shadow of the Fort – 52 Ancestors #459 52 Ancestors 10-21-2025 https://dna-explained.com/2025/10/21/henriette-pelletret-c1640-before-1694-life-and-death-in-the-shadow-of-the-fort-52-ancestor-459/
61 Cheat Sheet: Mitochondrial Matches, Haplotype Clusters, and Haplogroups Mitochondrial DNA 10-22-2025 https://dna-explained.com/2025/10/22/cheat-sheet-mitochondrial-matches-haplotype-clusters-and-haplogroups/
62 Simon Pelletret (1610-1642/1645): A Walk Through Port Royal – 52 Ancestors #460 52 Ancestors 10-27-2025 https://dna-explained.com/2025/10/27/simon-pelletret-c1610-1642-1645-a-walk-through-port-royal-52-ancestors-460/
63 Perrine Bourg (c1626-1693/1698): Phoenix Rising from the Ashes – 52 Ancestors #461 52 Ancestors 11-2-2025 https://dna-explained.com/2025/11/02/perrine-bourg-c1626-1693-1698-phoenix-rising-from-the-ashes-52-ancestors-461/
64 Concepts: What is a Half Relationships, Life Half First Cousins, Anyway? Concepts, Genealogy 11-4-2025 https://dna-explained.com/2025/11/04/concepts-what-is-a-half-relationship-like-half-first-cousins-anyway/
65 Marie Broussard (1686-after 1752), Life Across the River from Port Royal – 52 Ancestors #462 52 Ancestors 11-10-2025 https://dna-explained.com/2025/11/10/marie-broussard-1686-after-1752-life-across-the-river-from-port-royal-52-ancestors-462/
66 Francois Broussard (1653-1716), Intractable Acadian – 52 Ancestors #463 52 Ancestors 11-22-2025 https://dna-explained.com/2025/11/22/francois-broussard-1653-1716-intractable-acadian-52-ancestors-463/
67 Mitotree Sprouts 12,773 New Branches and Includes Ancient DNA Mitochondrial DNA 11-24-2025 https://dna-explained.com/2025/11/24/mitotree-sprouts-12773-new-branches-and-includes-ancient-dna/
68 Catherine Richard (c1663 – after 1714), Mother of Beausoleil, Acadian Freedom Fighters – 52 Ancestors #464 52 Ancestors 11-29-2025 https://dna-explained.com/2025/11/29/catherine-richard-c1663-after-1714-mother-of-beausoleil-acadian-freedom-fighters-52-ancestors-464/
69 Ancestry’s ThruLines Has a New Pedigree View Ancestry 12-2-2025 https://dna-explained.com/2025/12/03/ancestrys-thrulines-has-a-new-pedigree-view/
70 Ancestry Reverts ThruLines to the Original View Ancestry 12-6-2025 https://dna-explained.com/2025/12/06/ancestry-reverts-thrulines-to-the-original-view/
71 Michel Richard (c1630-1686/1689), Carefree Acadian – 52 Ancestors #465 52 Ancestors 12-7-2025 https://dna-explained.com/2025/12/08/michel-richard-dit-sansoucy-c1630-1686-1689-carefree-acadian-52-ancestors-465/ 
72 Mitochondrial DNA: How Do I Know if I’m a Candidate to Receive a New Haplogroup? Mitochondrial DNA 12-9-2025 https://dna-explained.com/2025/12/09/mitochondrial-dna-how-do-i-know-if-im-a-candidate-to-receive-a-new-haplogroup/
73 Heavens Ablaze: the 1833 Leonid Meteor Storm and Your Ancestors History, Genealogy 12-15-2025 https://dna-explained.com/2025/12/15/heavens-ablaze-the-1833-leonid-meteor-storm-and-your-ancestors/
74 Madelaine Blanchard (c1643 – 1678/1683), Gone Too Soon – 52 Ancestors #466 52 Ancestors 12-20-2025 https://dna-explained.com/2025/12/20/madelaine-blanchard-c1643-1678-1683-gone-too-soon-52-ancestors-466/
75 Soar Inspiration 12-24-2025 https://dna-explained.com/2025/12/24/soar/

_____________________________________________________________

Share the Love!

You’re always welcome to forward articles or links to friends and share on social media.

Subscribe!

If you haven’t already subscribed, it’s free. You’ll receive an e-mail whenever I publish by clicking the “follow” button at the top of the main blog page, here.

Help Keep This Blog Free

I receive a small commission when you click a vendor link in my articles and purchase that item. This does NOT increase your price but helps me keep the lights on and this informational blog free for everyone. Please click on the affiliate links in the articles or to the vendors below if you are purchasing products or DNA testing.

Thank you so much.

DNA Purchases and Free Uploads

Genealogy Products and Services

My Books

Genealogy Books

Genealogy Research